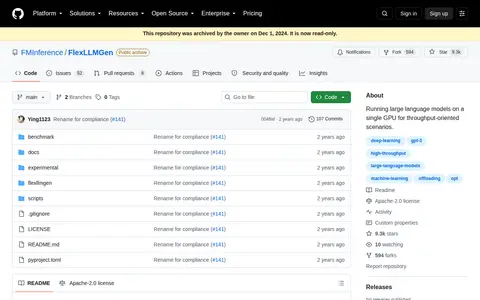
FlexGen is a software project that enables running large language models on a single GPU. It focuses on throughput-oriented scenarios, offering an approach to efficient inference. The project is available on GitHub as FMInference/FlexLLMGen.
Directory
Search results
Published directory entries matching your search.
Apache Flink is a distributed data processing engine for stateful computations over data streams. It offers exactly-once state consistency, event-time processing, layered APIs including SQL on stream and batch data, and flexible deployment with savepoints. Its stated use cases include event-driven applications, stream and batch analytics, and data pipelines and ETL.
Drag & drop UI to build your customized LLM flow using LangchainJS.
Library for high performance deep learning inference on NVIDIA GPUs.
Full Stack Deep Learning offers news, community, and courses for people building AI-powered products. It covers the lifecycle of an AI-powered product, from defining the problem and picking a GPU or foundation model to production deployment and continual learning.
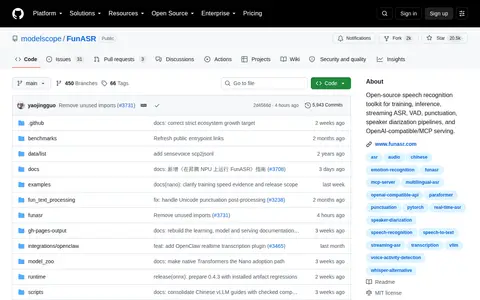
FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.
Future AGI is an open-source, self-hostable platform for evaluating, observing, and improving LLM and AI agent applications. It combines tracing, evals, simulations, datasets, a gateway and guardrails on one platform with a feedback loop. The Apache 2.0 core can be self-hosted, and a managed Cloud option is offered.
Future AGI SDK is a production-grade software development kit for AI evaluation, prompt management, and observability. It offers automated evaluations with sub-100ms guardrails and does not require human-in-the-loop. The SDK supports Python and TypeScript.
Host inference APIs, bulk inference and fine tune text, vision, audio and multi-modal models.
Testing framework dedicated to ML models, from tabular to LLMs. Detect risks of biases, performance issues and errors in 4 lines of code.
Cloud-Native LLM Routing Engine. Improve LLM app resilience and speed.
Go binding for MXNet c predict api to do inference with a pre-trained model.
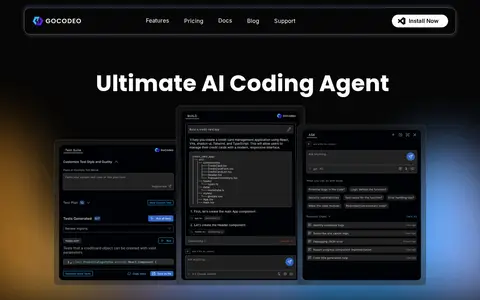
GoCodeo is an AI coding agent that integrates with IDEs to generate code and tests. Its sources describe framework support, MCP-based tool integration, Supabase integration and Vercel deployment, and automated test generation.
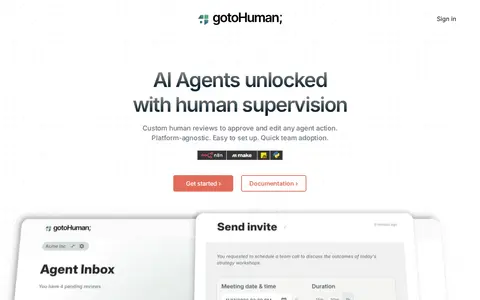
gotoHuman is a platform for supervising AI agents, letting workflows request human review of critical steps. Reviewers approve and edit AI-generated content in an Agent Inbox, with email and Slack notifications, and completed reviews return to the workflow via webhook. Review types are configured in a no-code editor and can capture text, images, markdown and JSON.
Creating semantic cache to store responses from LLM queries.
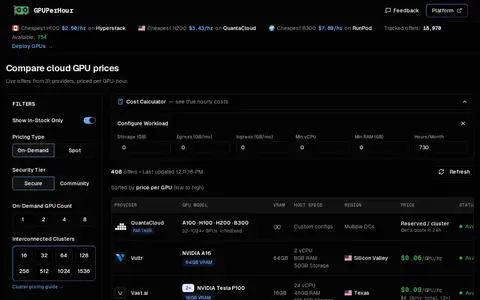
GPU Per Hour is a website that compares live cloud GPU pricing from 31 providers. It lists prices per GPU-hour for various GPU models, including H100, H200, B200, A100, and RTX 4090, and provides market snapshots and historical averages.
GPUStack is a GPU cluster manager built for high-performance AI model serving, with support for vLLM and SGLang, and offers on-demand SSH-accessible GPU instances, hosted in the gpustack/gpustack GitHub repository.
Gradio is an open-source Python library that enables developers to build and share machine learning web applications easily. It provides simple interfaces for creating demos and sharing models, supporting a wide range of ML frameworks.
Groq is a platform for inference, described as one fully integrated platform for infrastructure, inference, and control. It offers tiers including GroqMetal for bare-metal infrastructure, GroqCore for an inference stack, and GroqAssured for governance, auditability, and control.
Guild is a vendor-neutral control plane for AI agents. It lets engineering teams manage, govern, and share agents in production, with security and observability built in. Features include scoped credentials, action approval, policy enforcement, tracing, and evaluations. It supports any model or framework and provides a shared agent catalog and CLI access.
LogMeIn Hamachi is a hosted VPN service that extends secure LAN-like network connectivity to distributed teams and mobile users over the web. It supports gateway, hub-and-spoke and mesh virtual networking, web-based management, centralized software deployment and AES 256-bit encrypted communications. Hamachi is free for up to 5 computers in a network.
Helicone AI supports deploying, serving, monitoring, or operating AI and machine-learning systems.
Helium Edu is a free, color-coded online student planner for tracking classes, homework, grades, and notes. Its source code is organized into separate backend, frontend, deployment infrastructure, and marketing/support site repositories, maintained primarily by Alex Laird.
Hexo is a blog framework powered by Node.js that generates static files from posts written in Markdown or other markup languages. It offers theming, plugins and one-command deployment to platforms such as GitHub Pages or Heroku.