vitepress.dev
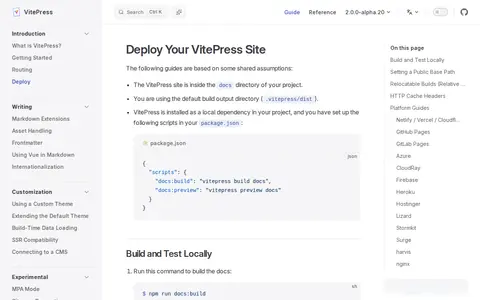
VitePress deployment guide is a setup or documentation resource for developer tools, deployments, or web projects.
Directory
Published directory entries matching your search.
VitePress deployment guide is a setup or documentation resource for developer tools, deployments, or web projects.
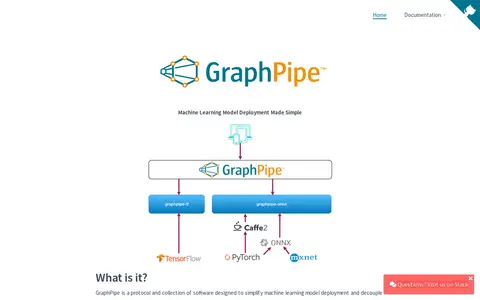
GraphPipe is a protocol and collection of software designed to simplify machine learning model deployment. It decouples deployment from framework-specific model implementations, allowing models to be served in a consistent manner across different environments.
KServe is a standardized distributed generative and predictive AI inference platform for scalable, multi-framework deployment on Kubernetes. It is a Cloud Native Computing Foundation incubating project. The platform supports backends such as vLLM and llm-d for serving LLMs, and multi-framework predictive serving. Standalone installation on standard Kubernetes is described as more lightweight but without canary deployment or request-based autoscaling with scale-to-zero.
NCNN is a neural network inference framework optimized for mobile, embedded, and desktop deployment. It has no third-party runtime dependencies and runs across CPU and Vulkan GPU backends. Tools such as pnnx convert PyTorch and ONNX models to ncnn, allowing deployment to phones, PCs, browsers, and edge devices. The project is used in several Tencent applications.
Anvil is a Python-based drag-and-drop web app builder. It provides a visual designer, Python in the browser and on the server, and one-click deployment. Apps are automatically hosted, and deployment environments map a URL or Uplink key to a version of the app with its configuration. Apps can be exported from the cloud editor and hosted on a computer using the open-source Anvil App Server.
BentoML is a unified model serving framework. It enables users to build model inference APIs, job queues, LLM applications, and multi-model pipelines. The framework supports local execution and deployment via Docker.
Epsilla is a high-performance vector database hosted on GitHub under the epsilla-cloud organization. It leverages parallel graph computing for its operations, and offers an experimental option to use it as a Python library without requiring a Docker image, alongside Epsilla Cloud as a deployment option.
Eurybia is an open-source tool hosted on GitHub under the MAIF organization. It is designed to monitor model drift over time and secure model deployment processes through data validation functionality, with public documentation covering overview, quickstart, installation, features, and project background.
Hydrosphere is a GitHub repository for an MLOps platform. The repository provides documentation for getting started with the platform, including installation instructions and guidance for deployment using Docker and Kubernetes.
Hydrosphere Mist is a serverless proxy for Spark clusters. It offers a functional programming framework and deployment model for Spark applications, with a REST HTTP and messaging API for Scala and Python Spark jobs. Sessions are managed across EMR, Hortonworks, Cloudera, DC/OS and vanilla Spark clusters.
Kaito is the Kubernetes AI Toolchain Operator, an operator suite that automates LLM inference, fine-tuning and RAG engine deployment in a Kubernetes cluster. It simplifies the CRD API and provides optimized preset configurations for inference engine scheduling parameters. Workspaces are the basic CRD for managing inference and tuning workloads, and all vLLM-supported models can be run.
LLMKube is a Kubernetes operator for self-hosted large language model inference across heterogeneous GPU fleets supporting NVIDIA CUDA, AMD Vulkan, and Apple Silicon Metal. It supports runtimes including llama.cpp, vLLM, TGI, and mlx-server, offers multi-GPU sharding, model caching, and OpenAI-compatible endpoints. It is licensed under Apache-2.0 and designed for homelab and on-prem fleet deployment, and is actively developed.
Mastra is a TypeScript AI framework for building agents and AI applications. It includes built-in memory, tool support, MCP compatibility, and observability features to support development from prototype to production. The framework also offers workflow tools, agent factory functionality, cloud deployment servers, and an agent builder for evaluation and iteration.
Bifrost is an open-source AI gateway for LLMs, MCP and agents, offered by Maxim AI. It provides routing, governance, guardrails and observability, and is described as a drop-in replacement for AI SDKs. Enterprise adds features such as SSO, RBAC, adaptive load balancing, cluster mode and in-VPC deployment, free for 14 days.

Full-stack AI platform focused on multimodal agents and consumer-scale deployment.
Modelz LLM is an inference server for running open source large language models such as FastChat, LLaMA and ChatGLM on local or cloud environments with an OpenAI compatible API. It supports interaction through the OpenAI python SDK or LangChain and provides docker images for deployment on Kubernetes or Modelz.
Nexdata is a data service and annotation platform offering services including annotation, fine-tuning, RLHF, red teaming, in-cabin sensing datasets, LiDAR data labeling, and LLM annotation. It provides a human-computer interaction semi-automatic annotation platform with flexible deployment options for public cloud or privatized deployment, and multi-level quality inspections.
An Easy-to-Use and High-Performance AI deployment framework.
Presenton is an open-source AI-powered presentation tool available in multiple deployment options: as a cloud application, self-hosted software for user-controlled infrastructure, and via an open API for automation. It generates editable PPTX and PDF slide decks from text prompts and uploaded documents, supports local deployment via Docker, and features a public community gallery of user-created decks, with no vendor lock-in for users.
Tutorial on Python time-series model deployment.
TensorFlow Model Optimization is a toolkit designed to optimize machine learning models for deployment for Keras and TensorFlow. It includes techniques such as quantization and pruning to reduce model size and improve inference performance.
TrueFoundry is an enterprise AI gateway that sits between applications and LLM providers and MCP servers. It offers a unified API for accessing more than 1000 LLMs, along with routing, fallbacks, rate limiting, access control, budgets, guardrails and observability. Deployment options include SaaS, hybrid and self-hosted VPC environments.
Vast.ai is a cloud GPU rental platform for AI, machine learning, deep learning and rendering workloads. Prices are set by supply and demand across 40+ data centers, with on-demand, interruptible and reserved instance types and per-second billing. Deployment is available through console, CLI, SDK and REST API.

vLLM is an open-source library for efficient serving of large language models. It provides an API server, supports offline and online inference, deployment options, and features such as automatic prefix caching, batch invariance, context extension, and speculative decoding. It can be used with GPUs, CPUs, and TPUs.