InnoCentive describes itself as a science, technology and innovation crowd connecting organizations with individual solvers. Companies and universities post challenges with awards, while solvers submit proposals; the site lists live challenges and a marketplace for funded opportunities.
Flink
Apache Flink is a distributed data processing engine for stateful computations over data streams. It offers exactly-once state consistency, event-time processing, layered APIs including SQL on stream and batch data, and flexible deployment with savepoints. Its stated use cases include event-driven applications, stream and batch analytics, and data pipelines and ETL.
Features
- Exactly-once state consistency Source: flink.apache.org
- Stream & Batch Analytics Source: flink.apache.org
Links
Tags
-
0InnoCentive describes itself as a science, technology and innovation crowd connecting organizations with individual solvers. Companies and universities post challenges with awards, while solvers submit proposals; the site lists live challenges and a marketplace for funded opportunities.
-
0MatlabBGL is a Matlab package for working with graphs that uses the Boost Graph Library to implement graph algorithms. It is designed for large sparse graphs with hundreds of thousands of nodes and was written by David Gleich. The page lists version 4.0 as the latest release, with downloads hosted on the Matlab File Exchange.
-
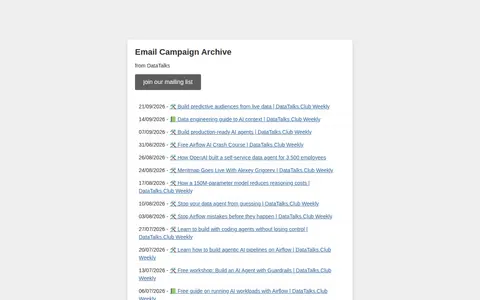
0DataTalks.Club. A weekly newsletter about data-related things..
-
0Apache Hadoop is an open-source project that develops software for reliable, scalable, distributed computing. Its library is a framework for distributed processing of large data sets across clusters of computers using simple programming models, scaling from single servers to thousands of machines with local computation and storage, and detecting failures at the application layer.
-
0
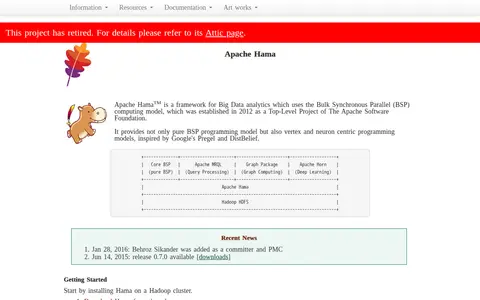
Apache Hama is a retired Apache Software Foundation Top-Level Project established in 2012. It is a framework for Big Data analytics that uses the Bulk Synchronous Parallel (BSP) computing model. It also provides vertex-centric and neuron-centric programming models inspired by Google's Pregel and DistBelief. Its components include core BSP, Apache MRQL for query processing, a graph computing package, and Apache Horn for deep learning, and it integrates with Hadoop HDFS.
-
0dplyr is an R package providing a grammar of data manipulation with a consistent set of verbs, including mutate(), select(), filter(), summarise() and arrange(), which combine with group_by(). It is designed to abstract over how data is stored, so the same R code works with local data frames and remote database tables via the dbplyr package.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review