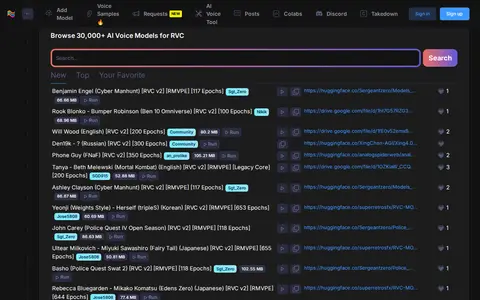
A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.
FunASR
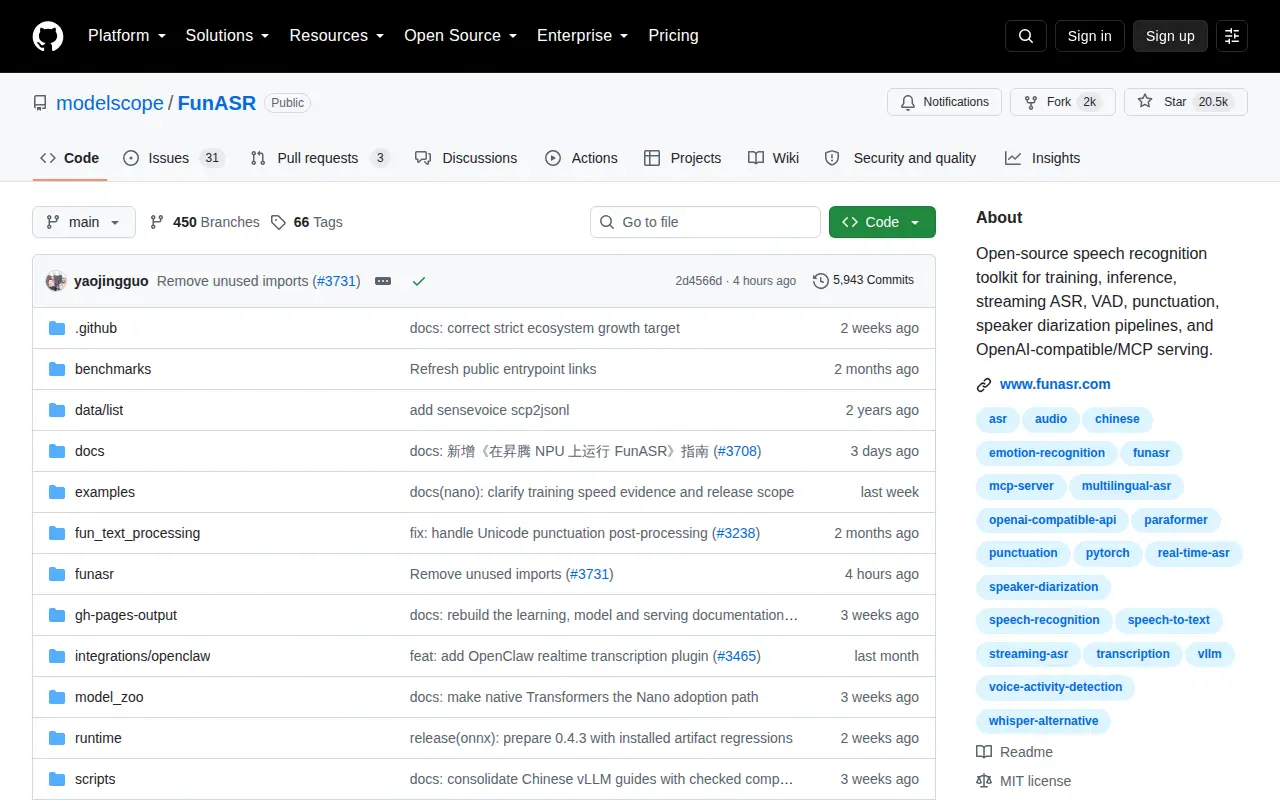
FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.
Features
- Industrial speech recognition toolkit for offline, streaming, and edge deployment Source: github.com
Links
Tags
-
0A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.
-
0Works with speech, voice, music or other audio using machine-learning models.
-
0A YouTube Blog post announcing an early look at the company's first AI-related music experiments: Dream Track for Shorts and Music AI tools, built in collaboration with Google DeepMind. Dream Track is powered by the Lyria music generation model and initially lets a small group of select US creators create soundtracks of up to 30 seconds for Shorts.
-
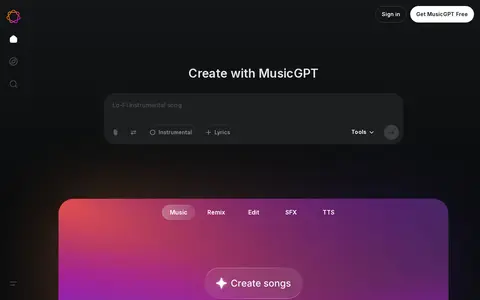
0MusicGPT is an AI music generator and song maker. It creates original songs, beats, instrumentals and sound effects, and offers editing tools to split stems, change voices and enhance audio. The site lists Plus, Pro and Ultra plans, with a free start and upgrades for more minutes and commercial use.
-
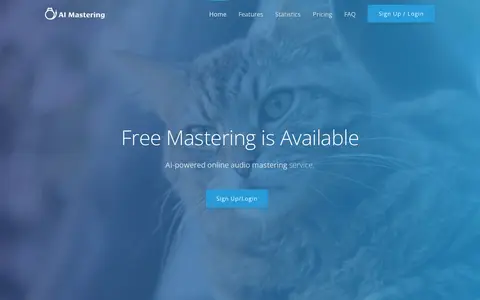
0AI Mastering is an automated online audio mastering service that uses AI. Free mastering is available, with drag-and-drop uploading, target loudness and mastering level customization, and output format, spectrum and loudness analysis. An API is documented, and a desktop offline version has been released.
-
0Applio is an open-source AI voice conversion suite. It provides voice conversion, real-time voice changing, speech synthesis, model training, voice blending and audio analysis. The project states it is MIT licensed and runs on Windows, macOS and Linux, with a desktop app or Gradio WebUI, and no accounts or telemetry.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review