Applio is an open-source AI voice conversion suite. It provides voice conversion, real-time voice changing, speech synthesis, model training, voice blending and audio analysis. The project states it is MIT licensed and runs on Windows, macOS and Linux, with a desktop app or Gradio WebUI, and no accounts or telemetry.
Directory
Search results
Published directory entries matching your search.
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Audify AI is a text-to-speech converter that turns written text into speech using AI models from OpenAI. Users can select voices, adjust speaking speed, and download audio in formats such as MP3, WAV, FLAC and OPUS. The site lists voiceovers, podcasts, audiobooks, accessibility and education among use cases.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Audio.Z.AI uses AI for speech, voice, transcription, music, or other audio workflows.
AudioCraft is a code base for generative audio tasks including music, sound effects, and compression, trained on raw audio signals. MusicGen produces music samples from text inputs, and AudioGen produces audio from environmental sounds via text-to-sound generation. The models use the EnCodec neural audio codec to learn discrete audio tokens from waveforms.
You can also find more comprehensive list on and There's an AI AI Voice Cloning list.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Bespoke Sounds is a sonic identity studio that creates custom branded soundtracks for lifestyle, luxury, and boutique hospitality brands. The studio is run by a team of DJs, musicians, and audiophiles.
Boomy uses AI for speech, voice, transcription, music, or other audio workflows.
Boppy is a free AI music generator that creates full songs from a text description. It writes the lyrics and generates a complete track in under a minute, with no signup or credit card required. Tracks run up to 2 minutes, and the apps for iOS and Android add in-app Premium at US$5.99/month in the US.
Cartesia uses AI for speech, voice, transcription, music, or other audio workflows.
Chatterbox TTS is a Hugging Face Space by ResembleAI that converts up to 300 characters of written text into spoken audio. It can optionally use a short reference recording to make the voice resemble a specific speaker, and includes adjustable settings described as expressive zeroshot text-to-speech.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Dadabots describes itself as a band of music hackers using DIY neural nets and open source tools such as PyTorch and Ableton. Its featured works include 24/7 livestreams generating death metal and a neural technical death metal livestream.
Discover amazing ML apps made by the community.
A Text-to-Speech bot for Discord with support for multiple languages and Text-to-Speech engines. It is intended as a way for people without a microphone, or unable to use one, to communicate on a voice channel, and as an entertainment tool. It supports 46 languages through the Google Translate Provider and saves settings for each user. The documentation site is still under development.
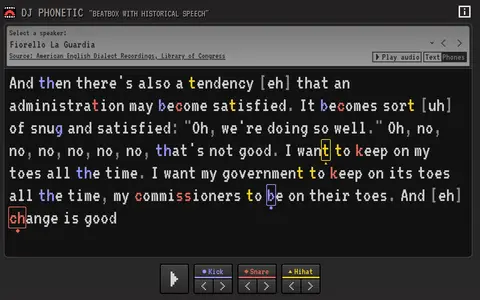
DJ Phonetic is a free online tool for creating beats using the percussive sounds hidden in human speech. It also supports beatboxing with historical speech sourced from the Library of Congress, and includes options to toggle International Phonetic Alphabet text and phone views.
ElevenLabs is an AI voice and audio platform. It provides an AI voice generator with access to more than 5,000 voices across over 70 languages, plus voice cloning, text-to-speech, dubbing, music generation, sound effect design, and conversational AI agent tools. The platform serves both individual creators and enterprise customers, with SDKs and APIs available for developers.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
EmotiVoice is an open-source text-to-speech engine that speaks English and Chinese with over 2000 voices. Its main feature is emotional synthesis across emotions such as happy, excited, sad and angry. It provides a web interface and a scripting interface for batch generation.
En uses AI for speech, voice, transcription, music, or other audio workflows.
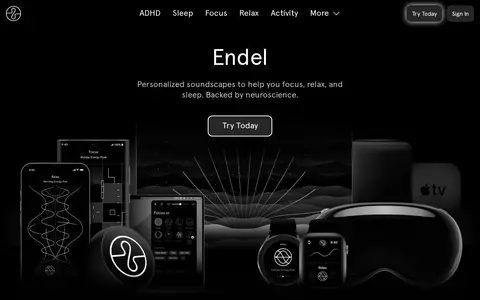
Endel is a mobile app that provides personalized soundscapes intended to help with focus, relaxation and sleep, backed by neuroscience. The app adapts sounds in real time using inputs such as time of day, weather, heart rate and location. It also offers versions for Apple Watch, Amazon Alexa, TV, desktop and streaming platforms.