
bronze.ai
Works with speech, voice, music or other audio using machine-learning models.
Applio is an open-source AI voice conversion suite. It provides voice conversion, real-time voice changing, speech synthesis, model training, voice blending and audio analysis. The project states it is MIT licensed and runs on Windows, macOS and Linux, with a desktop app or Gradio WebUI, and no accounts or telemetry.
Screenshot unavailable. The listing stays available while a preview is prepared.
Works with speech, voice, music or other audio using machine-learning models.
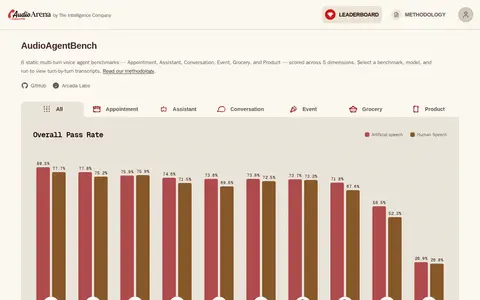
AudioArena is a site for benchmarking and comparing voice models through real conversations. It offers AudioAgentBench, a set of six static multi-turn voice agent benchmarks, scored across five dimensions, and lets users select a benchmark, model, and run to view turn-by-turn transcripts.

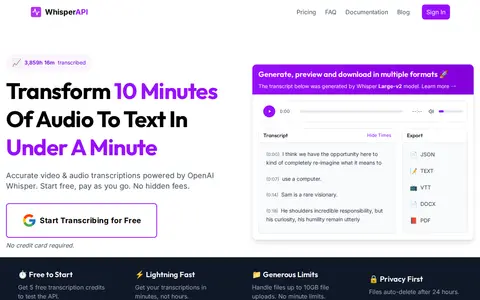
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.

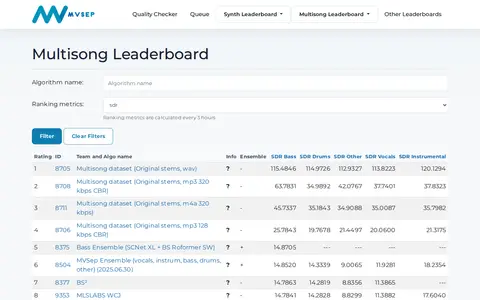
MultiSong Leaderboard is a ranking page on the MVSEP music and voice separation platform. It evaluates multisong audio separation algorithms using metrics including SDR, SI-SDR, L1 frequency, log WMSE, aura STFT, aura MRSTFT, bleedless, and fullness, with rankings updated every three hours. The page lists top-performing algorithms and their scores for separation tasks such as bass, drums, other stems, vocals, and instrumentals.
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
Works with speech, voice, music or other audio using machine-learning models.
Community notes
Be the first to share how this project worked for you.
Sign in with a verified account to leave a review or join the discussion.
Sign in to reviewKeep exploring
Works with speech, voice, music or other audio using machine-learning models.
AudioArena is a site for benchmarking and comparing voice models through real conversations. It offers AudioAgentBench, a set of six static multi-turn voice agent benchmarks, scored across five dimensions, and lets users select a benchmark, model, and run to view turn-by-turn transcripts.
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
MultiSong Leaderboard is a ranking page on the MVSEP music and voice separation platform. It evaluates multisong audio separation algorithms using metrics including SDR, SI-SDR, L1 frequency, log WMSE, aura STFT, aura MRSTFT, bleedless, and fullness, with rankings updated every three hours. The page lists top-performing algorithms and their scores for separation tasks such as bass, drums, other stems, vocals, and instrumentals.
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
Works with speech, voice, music or other audio using machine-learning models.