Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.
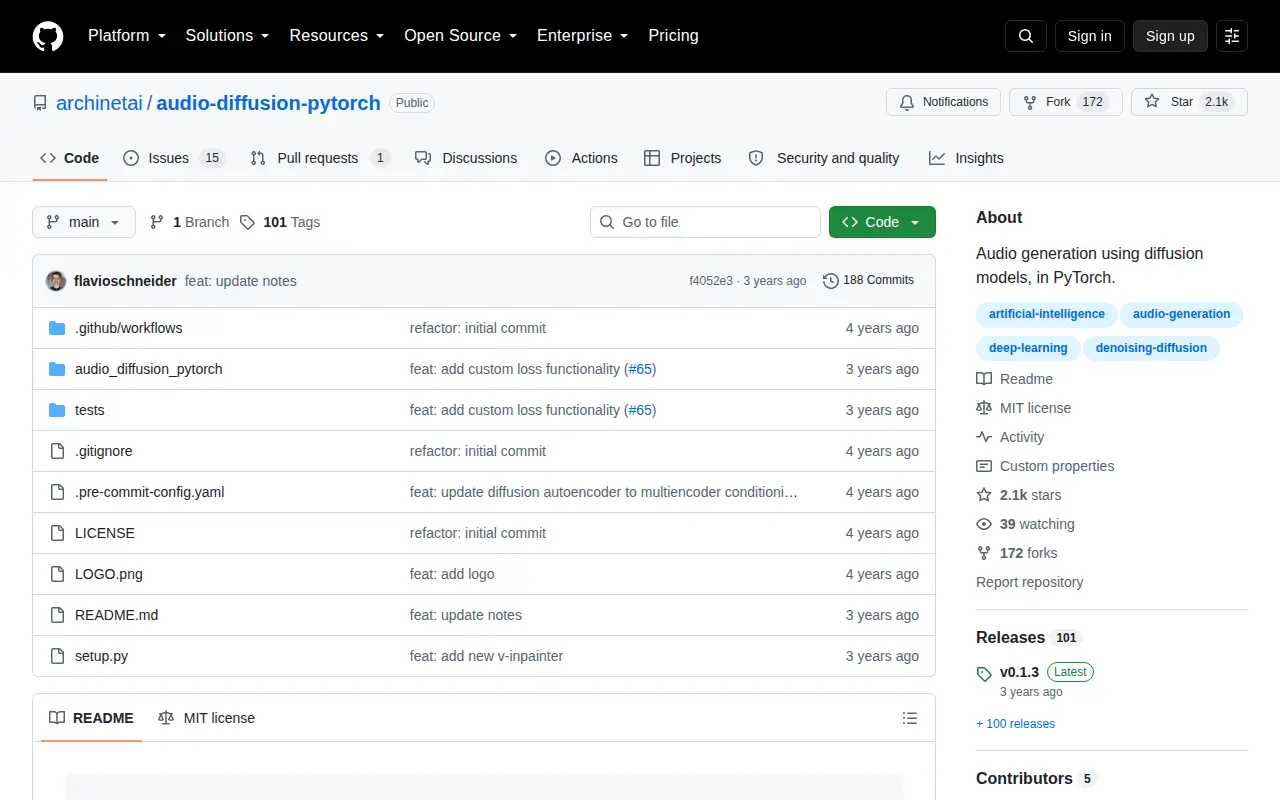
archinetai/audio-diffusion-pytorch
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.
Features
- Includes models for unconditional audio generation, text-conditional audio generation Source: github.com
- no pre-trained models are provided here Source: github.com
Links
Tags
-
0Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.
-
0
StemGen is an end-to-end music generation model trained to listen to musical context and respond appropriately. It is built on a non-autoregressive language-model type architecture similar to SoundStorm and VampNet, and is presented as examples for an ICASSP2024 paper.
-
0
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
-
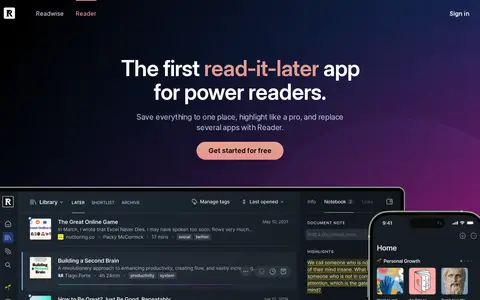
0Readwise Reader is a read-it-later app that saves articles, newsletters, RSS feeds, PDFs, EPUBs, YouTube videos and Twitter threads in one place. It offers web highlighting and annotation through a browser extension and integrates with the Readwise app, which resurfaces highlights via Daily Review and exports them to note-taking tools.
-
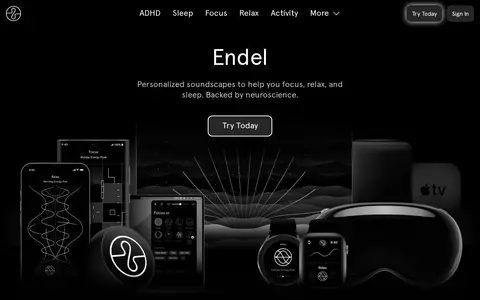
0Endel is a mobile app that provides personalized soundscapes intended to help with focus, relaxation and sleep, backed by neuroscience. The app adapts sounds in real time using inputs such as time of day, weather, heart rate and location. It also offers versions for Apple Watch, Amazon Alexa, TV, desktop and streaming platforms.
-
0
CMUSphinx is an open source speech recognition system for mobile and server applications. It supports C, C++, C#, Python, Ruby, Java and JavaScript, and Unix, Windows, iOS, Android and hardware platforms. The related PocketSphinx 5.1.0 release adds Python 3.14 support and pre-built wheels for Linux/arm64.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review