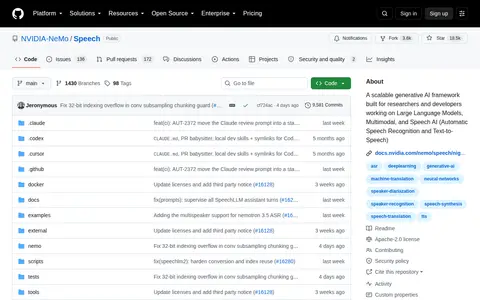
NVIDIA NeMo Speech is a framework built for researchers and developers working on speech AI, including automatic speech recognition and text-to-speech. The repository provides open weight checkpoints and demos through a Hugging Face collection. It is licensed under Apache-2.0 and has pivoted to focus on audio, speech, and multimodal LLMs.
Directory
Search results
Published directory entries matching your search.
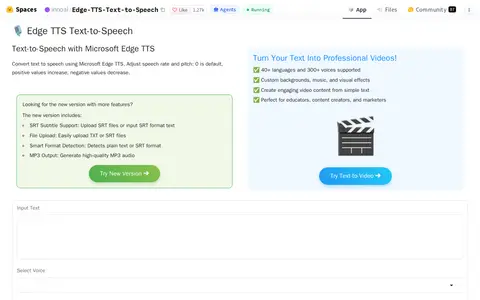
Edge TTS Text To Speech is a Hugging Face Space developed by innoai that converts user-input text to speech. Users can select from dozens of voice options, adjust speech speed and pitch, and generate high-quality MP3 audio files for playback or download. The space is currently running.
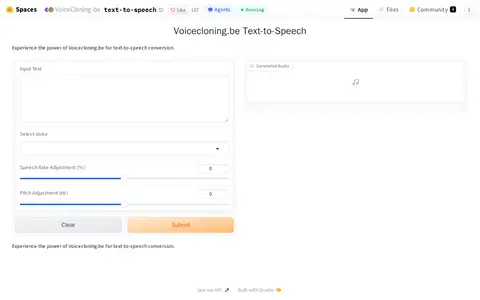
This is a duplicated instance of the Edge TTS Text To Speech Hugging Face Space, created by VoiceCloning-be. It offers the same text-to-speech functionality as the original, allowing users to input text, select voices, adjust speech rate and pitch, and generate customized audio output. The space is currently running.
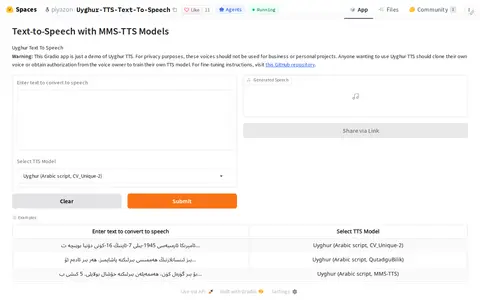
Uyghur TTS Text To Speech is a Hugging Face Space developed by piyazon. The application allows users to input Uyghur text, including numbers, Chinese characters and punctuation, select a Uyghur text-to-speech voice, and convert the typed text into natural-sounding Uyghur speech audio.
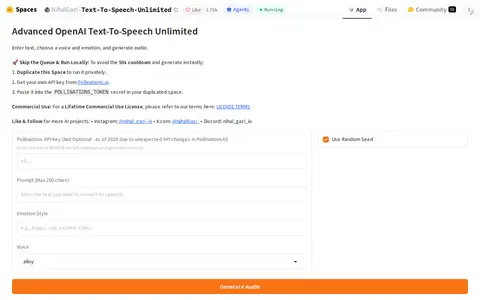
A Hugging Face Space that generates speech from entered text. Users choose a voice and an emotion style and can optionally set a seed. The app sends requests to the Pollinations service and returns an MP3 file with the synthesized speech.
A Hugging Face Space by amphion titled Text To Speech. The application converts text into speech using various voice options, with speaker selection and adjustable speaking rate. For advanced users, it also allows mixing two voices.
This Hugging Face Space by k2-fsa is a text-to-speech application that converts user-entered text to spoken audio. Users can select a language or model, and may upload or record a short reference audio clip to generate speech in a specific person's voice.
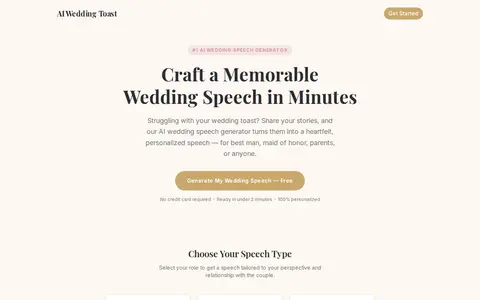
AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.
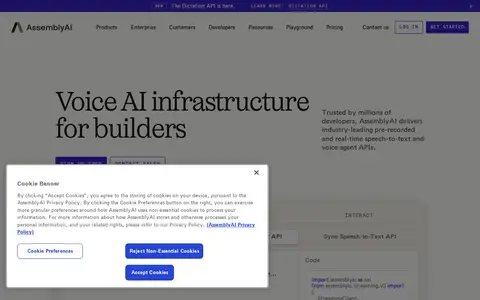
AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.
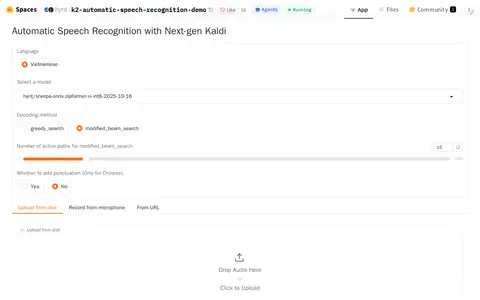
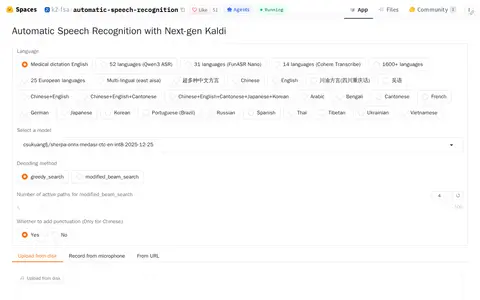
This Automatic Speech Recognition Hugging Face Space converts spoken audio to written text. Users can upload audio files, record from their microphone, or provide an audio URL, and select options including language, model, decoding method, and punctuation.
This Automatic Speech Recognition Hugging Face Space processes audio files, microphone recordings, or audio clips up to 40 seconds from a URL, and outputs the spoken content as written text.
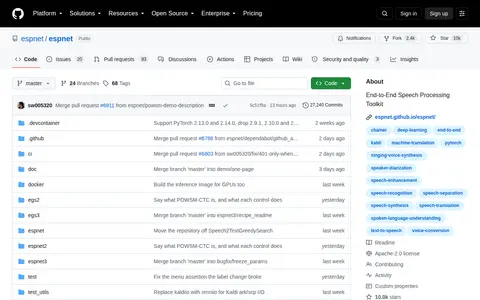
EspNet is an end-to-end speech processing toolkit hosted on GitHub. It is open-source software designed for speech processing tasks, with repository documentation covering installation steps, quick start guidance, and details of supported processing tasks. Contributors can participate in its development via the GitHub platform.
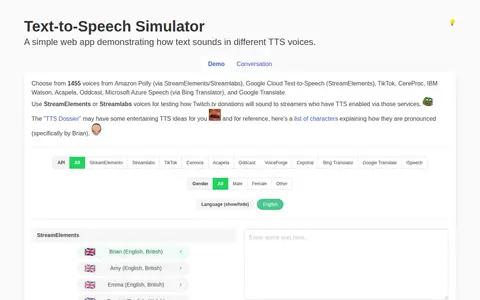
LazyPy is a web-based text-to-speech simulator that demonstrates how text sounds in different TTS voices. It offers a choice of over 1,000 voices from Amazon Polly, Google Cloud Text-to-Speech, TikTok, CereProc, IBM Watson, Acapela, Oddcast, Microsoft Azure Speech and Google Translate. Voices from StreamElements or Streamlabs can be used to test how Twitch.tv donations will sound.
A Hugging Face Space that converts text into speech in various languages, including Lojban and English. Users enter text and choose language and voice settings, then receive audio output. The Space is listed as sleeping due to inactivity.
Works with speech, voice, music or other audio using machine-learning models.
Murf AI is an AI voice and conversational agent platform. It provides tools to generate human-like speech and deploy conversational agents for use by developers, businesses, and creators. The platform offers a text-to-speech API, supports over 200 voices across 35+ languages, includes voice cloning and video translation features, and provides enterprise-grade security. It is described as trusted by over 10 million developers, businesses, and creators.
Qwen3-TTS is an open-source series of text-to-speech models developed by the Qwen team at Alibaba Cloud. It supports speech generation, streaming output, free-form voice design and voice cloning, and covers ten major languages with dialectal voice profiles. The release includes models of 0.6B and 1.7B parameters.
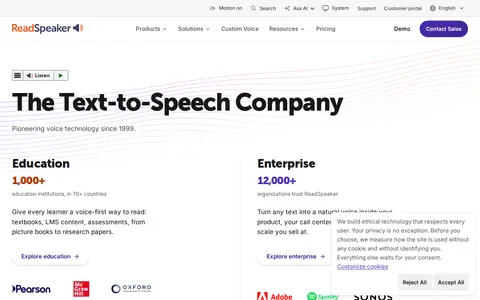
ReadSpeaker is a text-to-speech company that converts text to natural-sounding voice output for education and enterprise use cases. Its offerings include web accessibility tools, custom brand voice development, and voice AI for third-party products, with support for more than 90 languages. The company provides a range of products including text-to-speech APIs, SDKs, and embedded solutions, with sector-specific solutions for gaming, transportation, government, healthcare, and other industries.
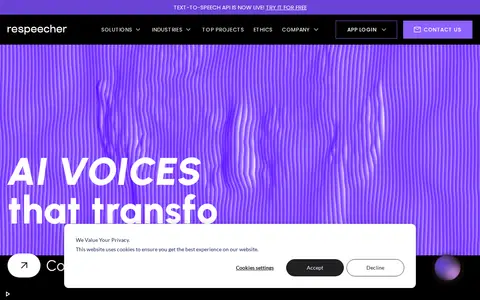
Respeecher provides an AI voice generator for professional production workflows. It offers enterprise-grade voice cloning and synthetic speech services, including a real-time text-to-speech API for voice agents. Its Voice Marketplace supplies over 40 AI voices and a plugin for Pro Tools. The company serves entertainment, film, TV, animation, games, broadcasting, sports, podcasts, audiobooks, music, and advertising sectors. Free testing and flexible integration are available.
Robust Speech Recognition Leaderboard 2022 uses AI for speech, voice, transcription, music, or other audio workflows.
Sindhi Speech To Text is a Hugging Face Space that converts spoken Sindhi language into written text. Users can upload an audio or video file or record directly from their microphone. The application also offers an option to remove background music.
Works with speech, voice, music or other audio using machine-learning models.