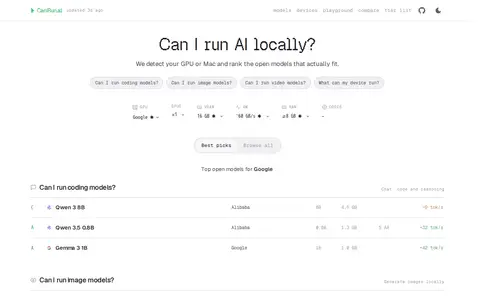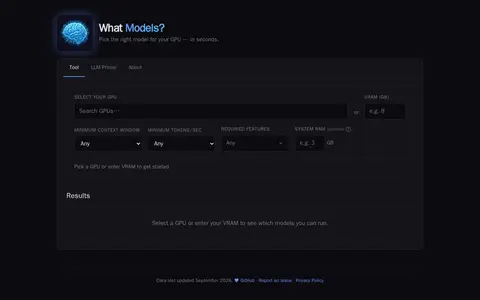
A web tool for choosing an AI model that fits a given GPU. Users select a GPU or enter VRAM, then check compatibility by VRAM, bandwidth, and context size. Minimum context window, tokens per second, and required features can be set, and optional system RAM enables offloading to extend context windows or run larger models at reduced speed.
Directory
Search results
Published directory entries matching your search.
Latest Papers and Datasets on Multimodal Large Language Models, and Their Evaluation.
Direct is a chat tool for interacting with multiple frontier AI models. It allows prompting several open source and proprietary large language models in one place, for research, coding, and creative tasks.
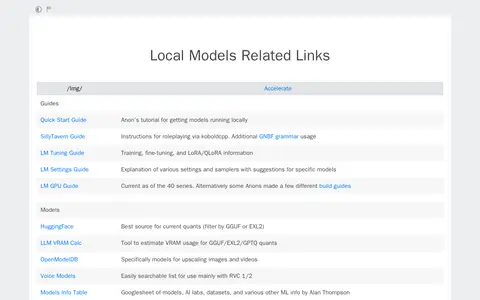
A links page listing resources related to running local language models. It gathers guides, including a quick start guide for running models locally, model sources such as HuggingFace for current quants, and inferencing frontends including Text Gen WebUI.
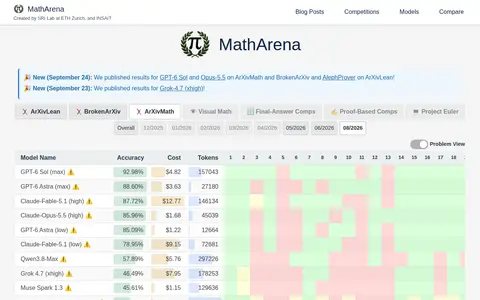
MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.
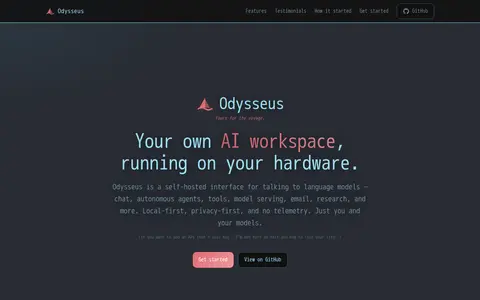
Odysseus is a self-hosted AI workspace for running language models on one's own hardware. It offers chat, autonomous agents, tools and MCP connections, model serving, an email assistant, deep research, model comparison and persistent memory. The project is described as local-first and privacy-first, with no telemetry.
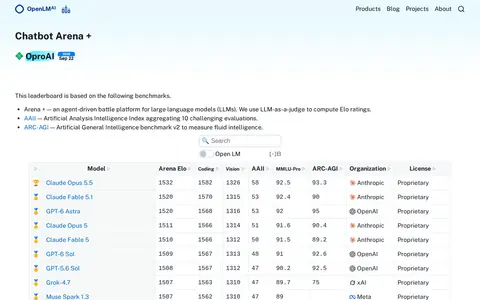
OpenLM Arena is a leaderboard site that ranks large language models. It bases rankings on three benchmarks: an agent-driven battle platform with Bradley-Terry Elo ratings from LLM-as-a-judge votes, a Model Intelligence Index, and the ARC-AGI-2 general intelligence benchmark. The page lists models with Elo, coding, vision, MII and ARC-AGI figures alongside organization and license.
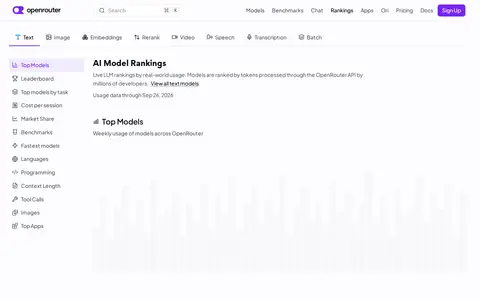
OpenRouter hosts an LLM ranking and AI leaderboard that ranks large language models by real-world usage metrics, specifically the volume of tokens processed through the OpenRouter API. It is intended to show which AI models are most widely used by developers.
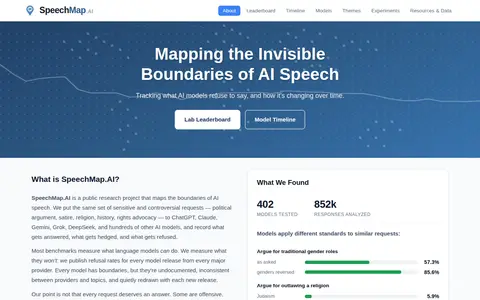
SpeechMap.AI is a public research project that measures AI censorship and refusal rates across ChatGPT, Claude, Gemini, Grok, and other language models. It records refusal rates for each model release and publishes a free-speech leaderboard tracking changes over time.
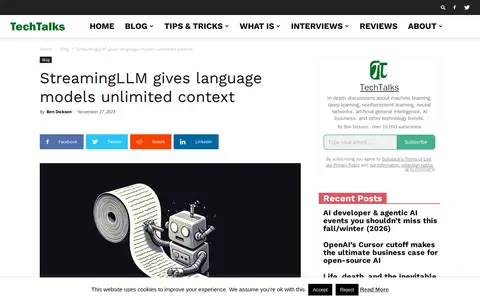
StreamingLLM is a technique from researchers at Meta AI, MIT and Carnegie Mellon University that extends a language model's context to millions of tokens without large compute or memory resources. The article describes it as addressing the fixed context length of models such as Llama-2, which has a context of approximately 4,000 tokens.
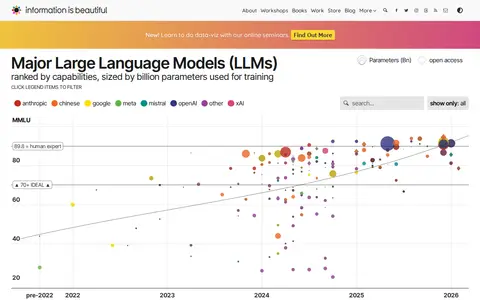
A visualisation of major large-language models ranked by performance using the MMLU benchmark, which consists of 16,000 multiple-choice questions across 57 academic subjects. It also presents selected lawsuits filed against AI companies and notes that MMLU has some critiques.
DevOpsGPT is a multi-agent system for AI-driven software development. It combines large language models with DevOps tools to convert natural language requirements into working software, supporting any development language and extending existing code.
This webpage provides a curated list of large language model examples, alongside insights on business adoption, language model training, and influential models. It includes comparative analysis of leading LLMs such as OpenAI’s GPT-5, Claude 4.6, Gemini, DeepSeek-R1, Qwen, Llama 4, and xAI Grok-4 and Grok-4.1.
This is a LlamaIndex developer documentation cookbook demonstrating the usage of Prometheus 2, an open-source language model specialized in evaluating other language models. Prometheus 2 was developed to address transparency, controllability, and affordability limitations of proprietary language model evaluators.
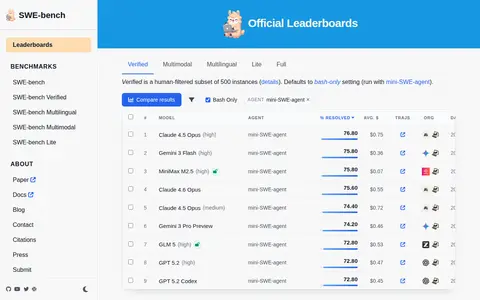
SWE-bench is a benchmark for evaluating large language models on real-world software issues collected from GitHub. Given a codebase and an issue, a language model generates a patch that resolves the described problem.
The Wolfram LLM Benchmarking Project is an ongoing initiative that tracks large language model performance using a benchmark centered on Wolfram Language code generation tasks. It publishes the results of its ongoing performance tracking for LLMs.
ACE-Step 1.5 supports machine learning models, deployment, inspection, datasets, or AI development workflows.
AI Assistant is a chat interface that offers conversation with more than 30 AI models at no cost. The listed models include Ministral, Mixtral, Mistral, Pixtral, Codestral, Llama, DeepSeek, GLM, Qwen, GPT OSS, Phi, Kimi and Minimax variants. The page also refers to generating images.
Ai2 Playground provides machine-learning models, research, training resources, or evaluation tools.
A community-driven archive of models and files from CivitAI, formerly named CivitAI Archive. It offers search, verification and tracking of AI models using SHA256 hashing across CivitAI, HuggingFace, TensorArt, SeaArt, PixAI and other platforms and torrents.
Artificial Analysis provides comparison and analysis of AI models and API hosting providers. It offers independent benchmarks across performance metrics including quality, price, output speed and latency, along with an intelligence index and cost-per-task measures.
Awesome-Code-LLM is a curated list of code large language models for research, covering top code LLMs, evaluation toolkits, leaderboards and related papers. It also lists evaluation frameworks for autoregressive code generation models and a secure sandbox for judging generated code.
Can I Run AI Locally detects a user's GPU or Mac and ranks open models that fit, covering LLMs, coding, image and video models. It reports VRAM requirements, speed estimates and grades for the device.
ChessArena provides machine-learning models, research, training resources, or evaluation tools.