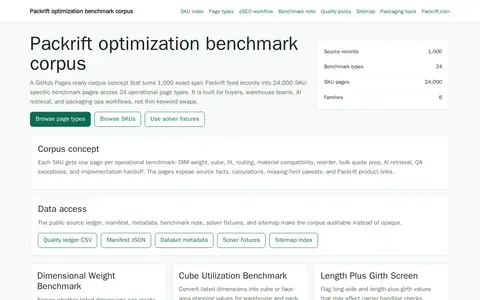
The Packrift Packaging Optimization Benchmark Corpus is a publicly available dataset generated from 1,000 exact-spec Packrift feed records, containing 24,000 SKU-specific benchmark pages across 24 operational page types for packaging optimization workflows, with public source ledgers, manifests, metadata, and solver fixtures to support auditability.
Large Language Model Evaluation in 2024: 5 Methods
This webpage provides a curated list of large language model examples, alongside insights on business adoption, language model training, and influential models. It includes comparative analysis of leading LLMs such as OpenAI’s GPT-5, Claude 4.6, Gemini, DeepSeek-R1, Qwen, Llama 4, and xAI Grok-4 and Grok-4.1.
Links
Tags
-
0
The Packrift Packaging Optimization Benchmark Corpus is a publicly available dataset generated from 1,000 exact-spec Packrift feed records, containing 24,000 SKU-specific benchmark pages across 24 operational page types for packaging optimization workflows, with public source ledgers, manifests, metadata, and solver fixtures to support auditability.
-
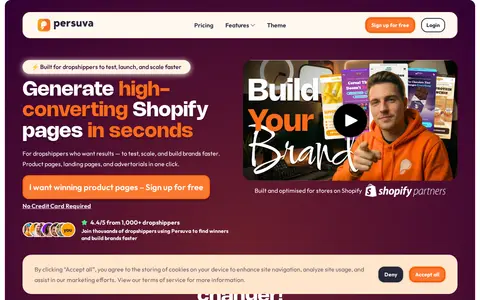
0Persuva generates Shopify product pages, landing pages and advertorials in one click, aimed at dropshippers. The site lists an audience analyser among its features and states the product is built and optimised for stores on Shopify. Pricing details with explicit plans are not stated in the supplied documents.
-
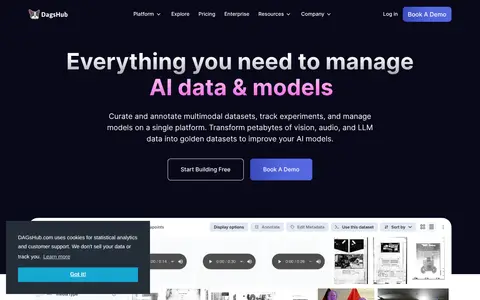
0DagsHub is an AI platform for managing the machine learning lifecycle, covering dataset curation and annotation, experiment tracking, and model management. It supports unstructured and multimodal data such as text, images, audio, video, and documents. The platform is built on open source tools and formats. DagsHub states it does not currently provide compute resources and relies on the user's own infrastructure.
-
0Tribuo is a machine learning library written in Java, developed by Oracle Labs' Machine Learning Research Group and released under the Apache 2.0 license. It supports classification, regression, clustering, anomaly detection and multi-label classification, and provides interfaces to libraries such as XGBoost and TensorFlow along with ONNX model exchange support.
-
0
Surprise is a Python scikit for building and analyzing recommender systems that deal with explicit rating data. It includes built-in datasets, prediction algorithms such as SVD and NMF, similarity measures, and cross-validation tools. The documentation states that Surprise does not support implicit ratings or content-based information.
-
0Hong Jing (Jingles) is a data scientist and Alibaba PhD student who writes about machine learning and neuroscience. The site collects blog articles on topics such as reinforcement learning agents, learned optimizers, convolutional layers, transformer models and decoding brain signals.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review