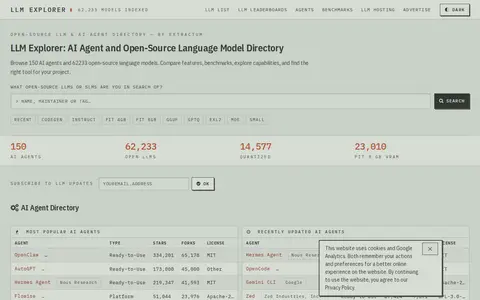
LLM Explorer is a directory of open-source language models and AI agents. It lists 150 AI agents and 64,811 open-source large and small language models, grouped into categories with benchmarks and analytics.
OpenLM Arena
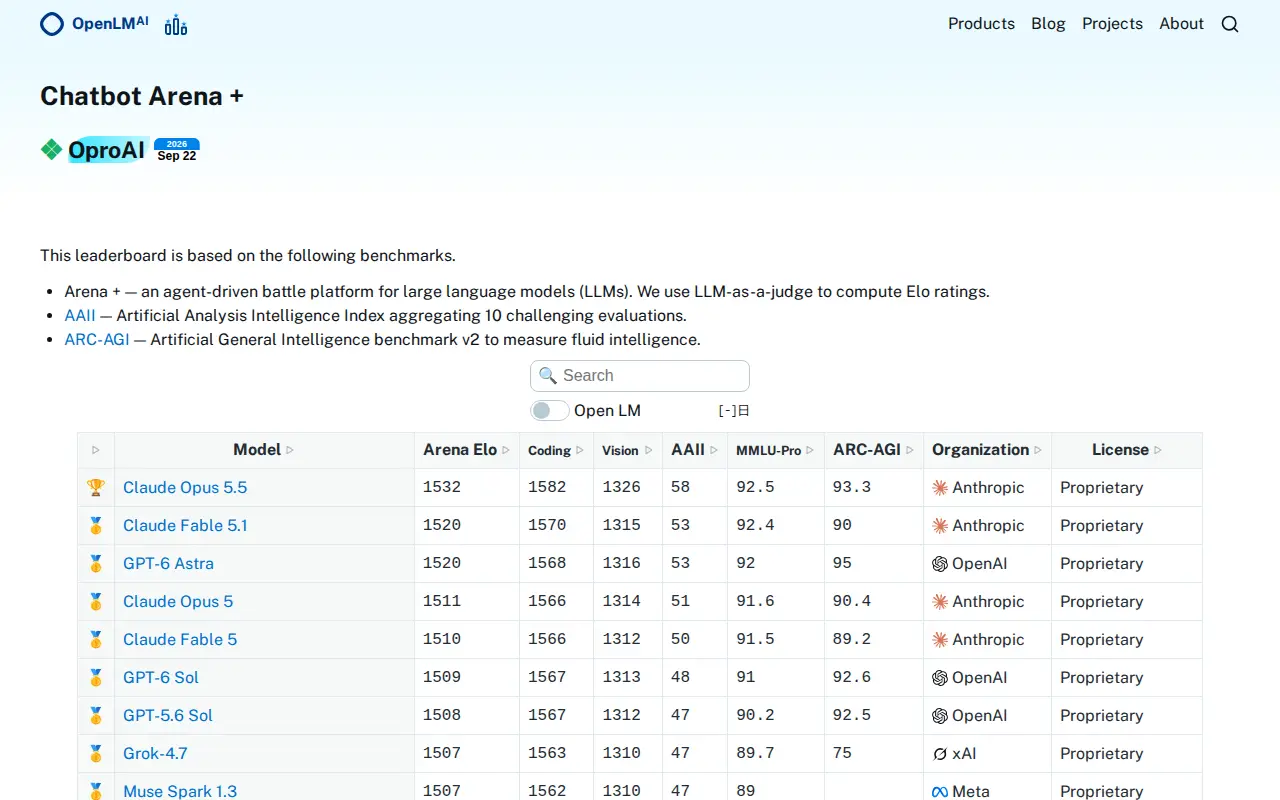
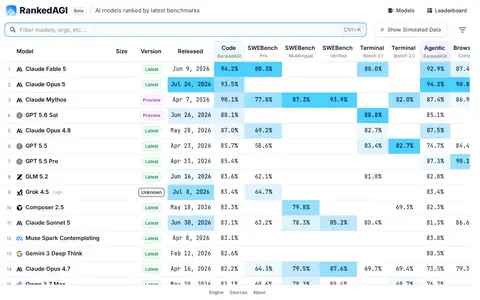
OpenLM Arena is a leaderboard site that ranks large language models. It bases rankings on three benchmarks: an agent-driven battle platform with Bradley-Terry Elo ratings from LLM-as-a-judge votes, a Model Intelligence Index, and the ARC-AGI-2 general intelligence benchmark. The page lists models with Elo, coding, vision, MII and ARC-AGI figures alongside organization and license.
Features
- agent-driven battle platform for large language models (LLMs) Source: openlm.ai
Links
Tags
-
0LLM Explorer is a directory of open-source language models and AI agents. It lists 150 AI agents and 64,811 open-source large and small language models, grouped into categories with benchmarks and analytics.
-
0RankedAGI is a website that compares benchmarks across different AI models. It features benchmarks such as SWE Bench Verified, Codeforces, LMSYS and LiveBench, and presents a ranked table of models with size, version, release date, context length, cutoff knowledge, license and organization.
-
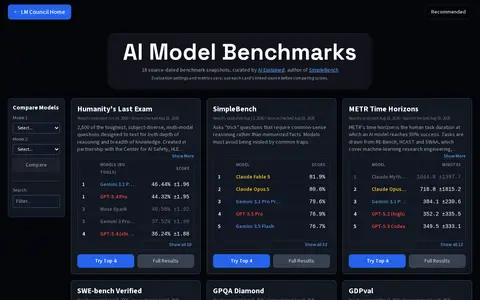
0LM Council presents source-dated benchmark snapshots for AI models. It covers GPT, Claude, Gemini and other frontier models across benchmarks including Humanity's Last Exam, FrontierMath, GPQA and SWE-bench, with a comparison tool selecting two models. Each snapshot links its source and checked date, and evaluation settings and metrics vary.
-
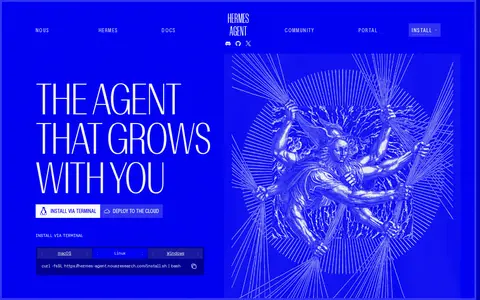
0Hermes Agent is an open-source, self-hosted AI agent by Nous Research. It is available as a terminal app and as Hermes Desktop for macOS, Windows and Linux, with persistent memory and a messaging gateway for platforms such as Telegram, Discord, Slack, WhatsApp, Signal and email. It is free under the MIT license.
-
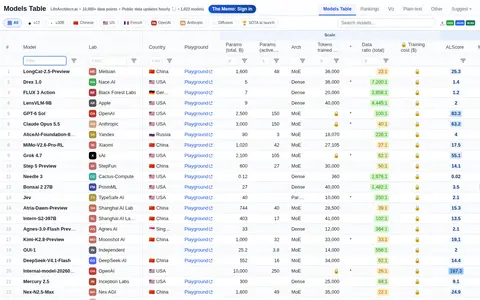
0LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
-
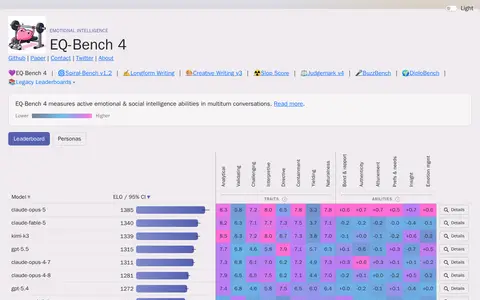
0EQ-Bench 4 is a benchmark that measures active emotional and social intelligence abilities in multiturn conversations. It uses 120 personas with assigned traits, including adversarial ones, in roleplay chats played by Gemini 3.1 Pro Preview. Transcripts are assessed by three judges to produce a ranked Elo score.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review