Exhibit is an open source publishing framework for creating data-rich interactive web pages. It provides advanced text search and filtering, along with interactive maps, timelines and other visualizations. The software is licensed under the BSD license and was originally sponsored partially by The Andrew W. Mellon Foundation as part of the SIMILE project.
Directory
Search results
Published directory entries matching your search.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
Datawrapper An open source data visualization platform helping everyone to create simple, correct and embeddable charts. Also at.
Apache Hadoop is an open-source project that develops software for reliable, scalable, distributed computing. Its library is a framework for distributed processing of large data sets across clusters of computers using simple programming models, scaling from single servers to thousands of machines with local computation and storage, and detecting failures at the application layer.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
Knowledge Repo is a next-generation curated knowledge sharing platform designed for data scientists and other technical professionals. It is maintained as a public open source repository on GitHub under the Airbnb organization.
Kyso was a universal aggregator for all research formats that ceased operation on September 31, 2023, and is now maintained as an open source project. It launched in 2018 to help the data science community share insights and address collaboration challenges across varied workflows and tools, with an initial focus on Jupyter Notebooks. During its operation, it served thousands of users and hundreds of organizations.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
Marquez is an open source metadata service for collecting, aggregating and visualizing a data ecosystem's metadata. It maintains provenance of how datasets are consumed and produced and provides visibility into job runtime and dataset access. Metadata is collected via OpenLineage, and a web UI shows job and dataset dependencies through a lineage graph.
Mars is an open source tensor-based unified framework for large-scale data computation. It scales numpy, pandas and scikit-learn, offering tensor, DataFrame and learn interfaces that resemble the original libraries. A session can be started locally or connected to an existing Mars cluster.
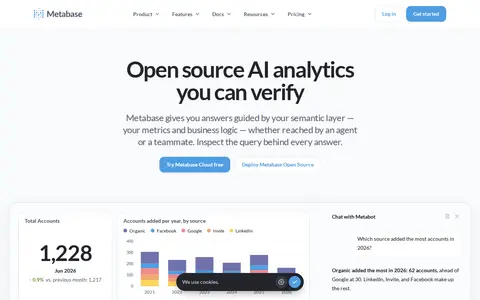
Metabase is an open source analytics and business intelligence platform. It grounds answers in a governed semantic layer of metrics and business logic so the query behind each answer can be inspected. It supports querying data in plain English with AI, interactive dashboards, documents, subscriptions and alerts, and embedded analytics. Users can self-host or use Metabase Cloud.
ModelDB is an open-source system for versioning machine learning models, including their code, data, config and environment, and for tracking ML metadata across the model lifecycle. It supports reproducible models, experiment management and lifecycle tracking. It runs on Docker and Kubernetes, offers Python and Scala clients, and is maintained by Verta.ai.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
Bring multiple data streams into one dashboard.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
Panthera is an open-source Clojure library available on GitHub that provides data-frame and array functionality for the Clojure programming language. The repository is maintained by alanmarazzi and accepts contributions from users.
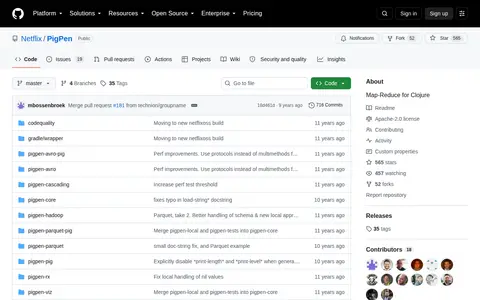
PigPen is an open-source Map-Reduce library for the Clojure programming language, hosted on GitHub under the Netflix organization. The repository includes documentation for getting started, tutorials, and support for data formats including Parquet and Avro.
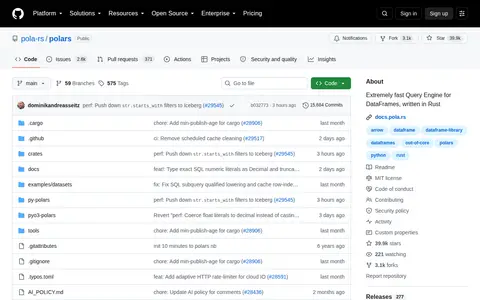
Polars is an extremely fast open-source query engine for DataFrames written in Rust, hosted as a GitHub repository under the pola-rs organization. It is built to handle large datasets, including data volumes that exceed available system RAM.
Open-source project that applies AI to data analysis, extraction, visualization, or business intelligence.
Open source GPU accelerated data science libraries.
Somoclu is a massively parallel implementation of self-organizing maps, using multicore CPUs, MPI for cluster workload distribution, and CUDA acceleration. It supports OpenMP, MPI, and CUDA, runs on Linux, macOS, and Windows, and offers planar and toroid maps, rectangular and hexagonal grids, and Gaussian and bubble neighborhood functions. Both dense and sparse input data are supported, with interfaces for Python, R, Julia, and MATLAB.
Apache Storm is a free and open source distributed realtime computation system. It processes unbounded streams of data and is simple, can be used with any programming language, and integrates with queueing and database technologies. Listed use cases include realtime analytics, online machine learning, continuous computation, distributed RPC and ETL.