Apache Hadoop is an open-source project that develops software for reliable, scalable, distributed computing. Its library is a framework for distributed processing of large data sets across clusters of computers using simple programming models, scaling from single servers to thousands of machines with local computation and storage, and detecting failures at the application layer.
Mars
Mars is an open source tensor-based unified framework for large-scale data computation. It scales numpy, pandas and scikit-learn, offering tensor, DataFrame and learn interfaces that resemble the original libraries. A session can be started locally or connected to an existing Mars cluster.
Features
- tensor-based unified framework for large-scale data computation Source: github.com
Links
Tags
-
0Apache Hadoop is an open-source project that develops software for reliable, scalable, distributed computing. Its library is a framework for distributed processing of large data sets across clusters of computers using simple programming models, scaling from single servers to thousands of machines with local computation and storage, and detecting failures at the application layer.
-
0Apache Spark is a multi-language engine for executing data engineering, data science, and machine learning on single-node machines or clusters. It provides high-level APIs in Java, Scala, Python and R, and supports Spark SQL, pandas API on Spark, MLlib, GraphX and Structured Streaming. The documentation covers downloads, the shell and client applications.
-
0
Analyzes structured data and helps produce queries, insights or visualizations.
-
0Odyssey.js is an open source tool that combines maps, narratives and other multimedia into stories. It offers templates including scrolling, slide based and temporal designs, and Actions for map movements and content display. The sandbox lets users test the library and edit story content with Markdown. It is an early-stage project developed by cartodb.com with Knight Foundation funding.
-
0
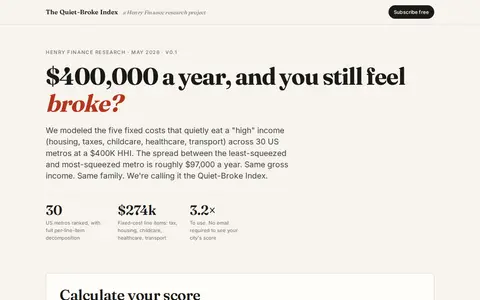
The Quiet-Broke Index is a research project modeled by Henry Finance that estimates the high-earner squeeze across 30 US metros at a $400,000 household income. It combines five fixed costs: housing, taxes, childcare, healthcare and transportation. A calculator gives a 0–100 score from five inputs, and the site ranks cities and reports per-line-item decomposition.
-
0IGSR, the International Genome Sample Resource, provides open human variation data. Data files from many studies are shared via FTP, with key data sets presented in a data portal browsable by sample, population, technology, data type and collection. Ensembl presents some key call sets in genomic context. Bulk downloads are recommended via Globus, with FTP and Aspera also available.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review