
aistudio.google.com
Google Speech Gen helps build, test, automate, or manage AI agents, prompts, models, and API workflows.
Directory
AI audio and speech covers voice synthesis, transcription, and machine learning tools for sound. Listings include text to speech services, dictation and meeting transcription, voice cloning, music generation, and open source models you can run yourself. The languages and accents each one handles matter, along with the length limit for a single job and whether processing happens on your device or on a remote server. Quality and cost also move, since some services change their limits often and a model you can host yourself behaves differently from a hosted one. Voice cloning and generated speech raise consent and rights questions, so use your own recordings or material you are allowed to use.
Google Speech Gen helps build, test, automate, or manage AI agents, prompts, models, and API workflows.
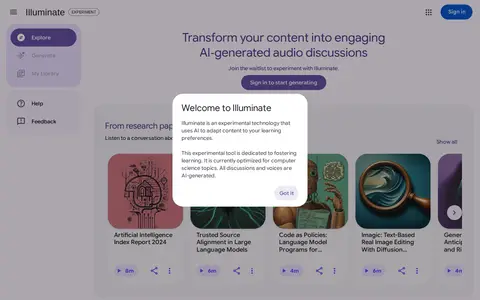
Google Illuminate uses AI for speech, voice, transcription, music, or other audio workflows.
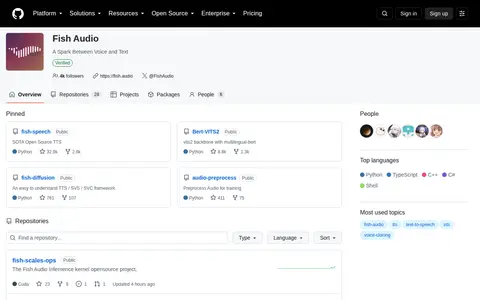
Fish Audio is an AI platform for voice generation, voice cloning, and audio storytelling, and its GitHub organization hosts open source repositories. Public repositories include fish-speech, described as SOTA open source TTS, Bert-VITS2, a vits2 backbone with multilingual-bert, and fish-diffusion, a TTS / SVS / SVC framework.
Acapela Group is a company that develops personalized digital voices using voice AI technology. It offers text-to-speech solutions for services, applications and devices, with support for over 30 languages and more than 200 pre-made voices, plus custom voice creation options. The company provides SDKs for multiple platforms, cloud streaming APIs, and specialized solutions including voice AI for accessibility, transport and customer interaction.
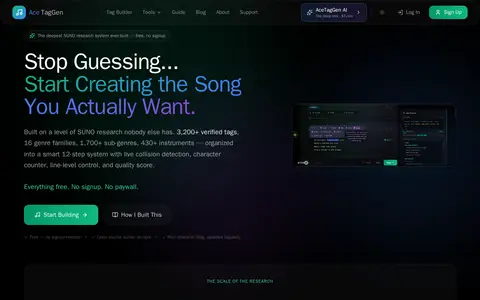
AceTagGen is a free prompt system for SUNO AI. It offers a structured 12-step Tag Builder, a library of verified tags, a prompt scorer, and a research blog with articles and guides. No signup is required.
AI Dictation is a voice typing app for people who mix English into Russian, Ukrainian or Belarusian. It removes filler words and adds punctuation without translating work terms. It runs on Mac, Windows, iPhone and Android, and speech recognition can run on device while cleanup runs in the cloud.
AI Mastering is an automated online audio mastering service that uses AI. Free mastering is available, with drag-and-drop uploading, target loudness and mastering level customization, and output format, spectrum and loudness analysis. An API is documented, and a desktop offline version has been released.
A web tool for generating songs from text, lyrics or uploaded audio, with style, voice and tempo options and instrumental-only tracks. Songs can be downloaded or shared. The free tier offers 20 daily credits and royalty-free output.
AI Voice Generator is a free online tool that produces natural-sounding text-to-speech voice overs. Users enter text, select from various AI voices, and generate a voiceover. The service emphasizes simplicity and accessibility for creating spoken content.

AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.
A YouTube Blog post announcing an early look at the company's first AI-related music experiments: Dream Track for Shorts and Music AI tools, built in collaboration with Google DeepMind. Dream Track is powered by the Lyria music generation model and initially lets a small group of select US creators create soundtracks of up to 30 seconds for Shorts.
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.

AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.
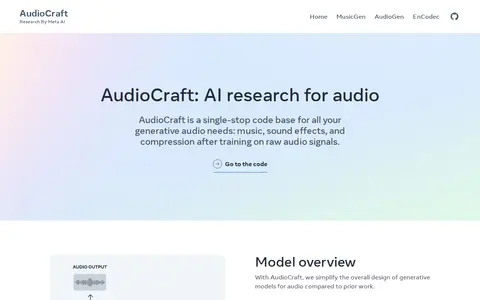
AudioCraft is a code base for generative audio tasks including music, sound effects, and compression, trained on raw audio signals. MusicGen produces music samples from text inputs, and AudioGen produces audio from environmental sounds via text-to-sound generation. The models use the EnCodec neural audio codec to learn discrete audio tokens from waveforms.
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
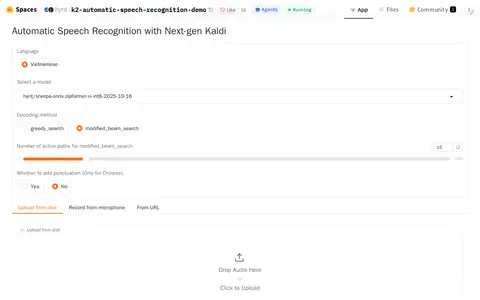
This Automatic Speech Recognition Hugging Face Space converts spoken audio to written text. Users can upload audio files, record from their microphone, or provide an audio URL, and select options including language, model, decoding method, and punctuation.
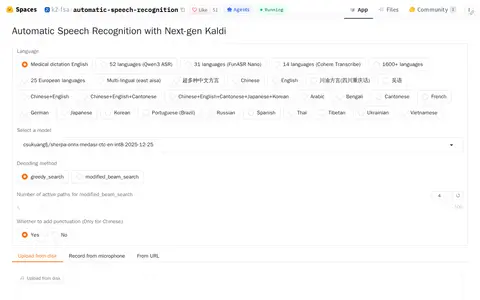
This Automatic Speech Recognition Hugging Face Space processes audio files, microphone recordings, or audio clips up to 40 seconds from a URL, and outputs the spoken content as written text.
You can also find more comprehensive list on and There's an AI AI Voice Cloning list.
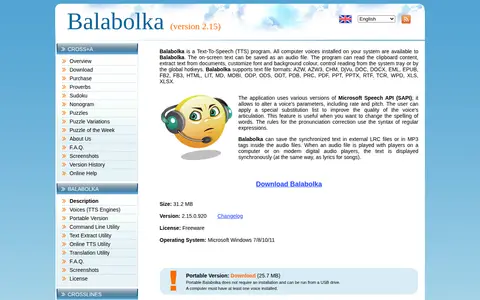
Balabolka is a freeware text-to-speech application that uses computer voices installed on the system. It can save on-screen text as an audio file, read clipboard content, extract text from documents, and save synchronized text in LRC files or MP3 tags.
Bespoke Sounds is a sonic identity studio that creates custom branded soundtracks for lifestyle, luxury, and boutique hospitality brands. The studio is run by a team of DJs, musicians, and audiophiles.
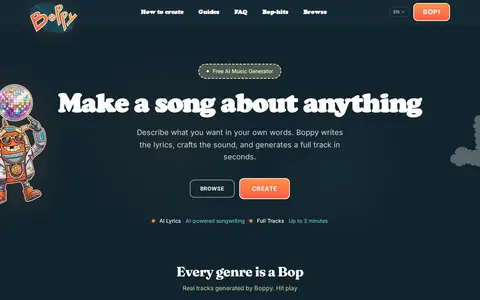
Boppy is a free AI music generator that creates full songs from a text description. It writes the lyrics and generates a complete track in under a minute, with no signup or credit card required. Tracks run up to 2 minutes, and the apps for iOS and Android add in-app Premium at US$5.99/month in the US.

Works with speech, voice, music or other audio using machine-learning models.

Text-to-speech solutions with character.
CMUSphinx is an open source speech recognition system for mobile and server applications. It supports C, C++, C#, Python, Ruby, Java and JavaScript, and Unix, Windows, iOS, Android and hardware platforms. The related PocketSphinx 5.1.0 release adds Python 3.14 support and pre-built wheels for Linux/arm64.
Details from each project's website. Open a listing for its full overview.