kyutai.org
Kyutai TTS uses AI for speech, voice, transcription, music, or other audio workflows.
Directory
AI audio and speech covers voice synthesis, transcription, and machine learning tools for sound. Listings include text to speech services, dictation and meeting transcription, voice cloning, music generation, and open source models you can run yourself. The languages and accents each one handles matter, along with the length limit for a single job and whether processing happens on your device or on a remote server. Quality and cost also move, since some services change their limits often and a model you can host yourself behaves differently from a hosted one. Voice cloning and generated speech raise consent and rights questions, so use your own recordings or material you are allowed to use.
Kyutai TTS uses AI for speech, voice, transcription, music, or other audio workflows.
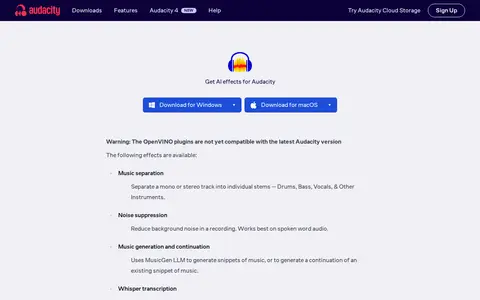
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.
MusicFX uses AI for speech, voice, transcription, music, or other audio workflows.

Pack Generator uses AI for speech, voice, transcription, music, or other audio workflows.
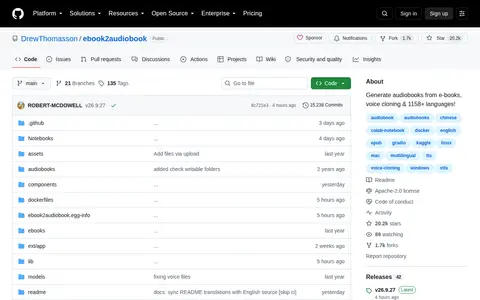
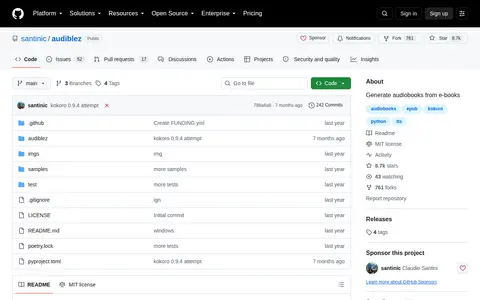
Ebook2Audiobook is an open-source GitHub repository created by DrewThomasson that generates audiobooks from e-books, supports voice cloning, and is compatible with 1158 or more languages. The tool can be run locally or remotely.
AnyVoiceLab is a free, no-login-required AI voice cloning tool. Users provide a short voice sample to create lifelike voice replicas, generate studio-quality speech, and download the resulting audio for free. Additional features include long-form text-to-speech, voice changing, sound effect generation, premium voice options, AI voice generation, payment plans, and support for emotion tags in speech.
ACE-Step 1.5 supports machine learning models, deployment, inspection, datasets, or AI development workflows.

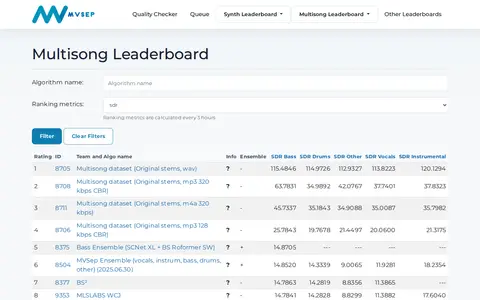
MultiSong Leaderboard is a ranking page on the MVSEP music and voice separation platform. It evaluates multisong audio separation algorithms using metrics including SDR, SI-SDR, L1 frequency, log WMSE, aura STFT, aura MRSTFT, bleedless, and fullness, with rankings updated every three hours. The page lists top-performing algorithms and their scores for separation tasks such as bass, drums, other stems, vocals, and instrumentals.
MMAudio is a CVPR 2025 project for video-to-audio synthesis that generates synchronized audio from video and/or text inputs. It uses multimodal joint training and a synchronization module to align generated audio with video frames. A pretrained large_44k_v2 model is used by default, with inference around 6GB of GPU memory in 16-bit mode.
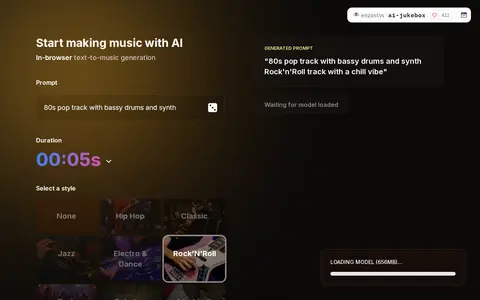
AI Jukebox is a Hugging Face Space that generates AI-powered music. Users can input a description of their desired music, select the clip length and preferred style or mood, and the app produces a matching audio clip directly in the web browser.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Chatterbox TTS is a Hugging Face Space by ResembleAI that converts up to 300 characters of written text into spoken audio. It can optionally use a short reference recording to make the voice resemble a specific speaker, and includes adjustable settings described as expressive zeroshot text-to-speech.
ACE-Step 1.5 is an open-source local music generation model released by the ace-step project under an MIT license. The repository states it supports Mac, AMD, Intel and CUDA devices, and describes a hybrid architecture combining a language model planner with a diffusion transformer on consumer hardware.
MMAudio is a Hugging Face Space that generates synchronized audio from video or text. Users can upload a short video and write a prompt, including a negative prompt, to add realistic sound, or create a standalone audio clip from a text description.
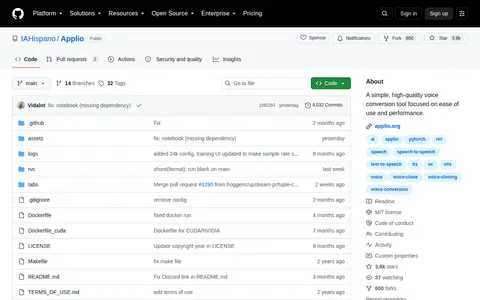
Applio is a GitHub repository or organization with source code, releases, documentation, or project resources.
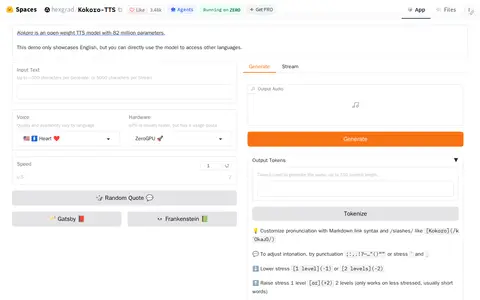
Kokoro TTS is a Hugging Face Space developed by hexgrad that converts input English text to spoken audio. Users can select a voice and speaking speed, and choose to download the generated audio or listen to a live streaming version.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
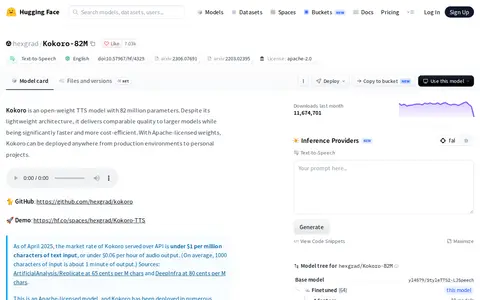
Kokoro-82M is an open-weight text-to-speech model with 82 million parameters, released under the Apache 2.0 license. It delivers audio quality comparable to larger TTS models while being faster and more cost-efficient, and its weights can be deployed in both production and personal environments.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Moe TTS is a Hugging Face Space created by skytnt that enables users to generate speech from input text and convert existing audio to a different speaker's voice. Users can input text to create speech output, select from available speakers, and adjust the playback speed of generated audio.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
EmotiVoice is an open-source text-to-speech engine that speaks English and Chinese with over 2000 voices. Its main feature is emotional synthesis across emotions such as happy, excited, sad and angry. It provides a web interface and a scripting interface for batch generation.
GPT-SoVITS is a few-shot voice conversion and text-to-speech WebUI. It supports zero-shot TTS from a five-second vocal sample and fine-tuning with one minute of training data. Cross-lingual inference covers English, Japanese, Korean, Cantonese and Chinese. Integrated WebUI tools include voice accompaniment separation, training set segmentation, Chinese ASR and text labeling.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.