
soundoftext.com
SoundofText uses AI for speech, voice, transcription, music, or other audio workflows.
Directory
AI audio and speech covers voice synthesis, transcription, and machine learning tools for sound. Listings include text to speech services, dictation and meeting transcription, voice cloning, music generation, and open source models you can run yourself. The languages and accents each one handles matter, along with the length limit for a single job and whether processing happens on your device or on a remote server. Quality and cost also move, since some services change their limits often and a model you can host yourself behaves differently from a hosted one. Voice cloning and generated speech raise consent and rights questions, so use your own recordings or material you are allowed to use.
SoundofText uses AI for speech, voice, transcription, music, or other audio workflows.
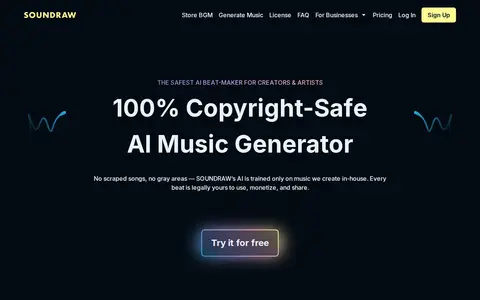
SOUNDRAW is an AI music generator that lets users create royalty-free beats in seconds. It supports genre blending, instrument customization, stem downloads, and music monetization. Its AI is trained exclusively on in-house created music, with no use of scraped content, to ensure copyright-safe outputs for creators and artists.
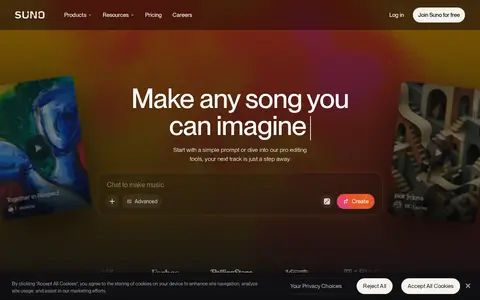
Suno is an AI music generator that creates original music from user prompts. It offers a browser-based digital audio workstation for editing and mixing tracks, voice cloning to make any voice sing user-written content, stem separation to split songs into individual components, and remix functionality.
Treblo, formerly Sonauto, is a free AI music generator that turns ideas into songs with lyrics, vocals and thousands of styles. It offers unlimited songs, editing, covers and remixes, and is available on iOS and Android.
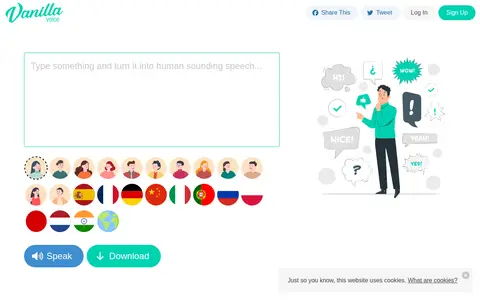
VanillaVoice is a free online text to speech tool that reads text aloud with human-sounding voices. Users can pick male, female or child voices in many languages, adjust volume and speed, and download audio as an MP3 without installing software. A Professional Plan offers a commercial license, speech-enabled products and up to 500 words per recording.
VocalRemover is a free online application that separates a song into a karaoke version without vocals and an acapella version with isolated vocals. It uses artificial intelligence algorithms and processing usually takes about 10 seconds.
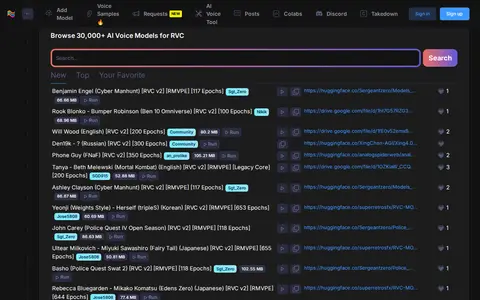
A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.
WolframTones uses AI for speech, voice, transcription, music, or other audio workflows.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
A Hugging Face Space that turns an ebook file or pasted text into a complete audiobook. The user selects a language, voice and audio format, then generates audio to listen to or download; sections can also be previewed and edited. The page states support for 1107+ languages.
Cartesia uses AI for speech, voice, transcription, music, or other audio workflows.
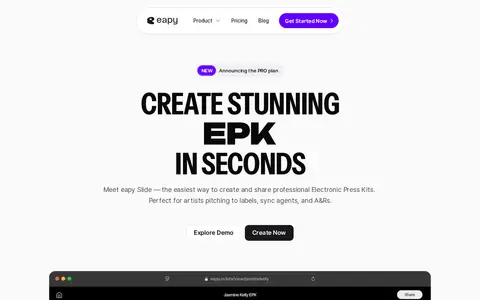
Eapy Slide is a tool for creating professional Electronic Press Kits (EPKs) for music artists. Users upload music, images, and text to generate formatted, shareable EPKs to pitch to labels, sync agents, and A&R representatives.
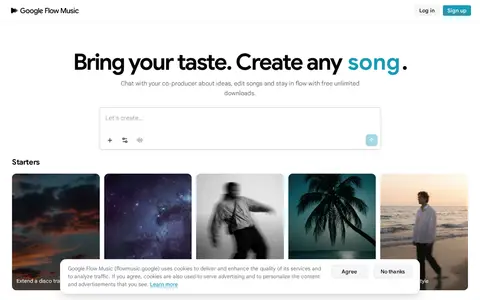
Google Flow Music is a generative AI platform for creating, remixing, and sharing songs. It includes a chat with Producer, AI music video, and tools to build audio plugins, music games, and custom DAWs. It is free to start without a credit card.

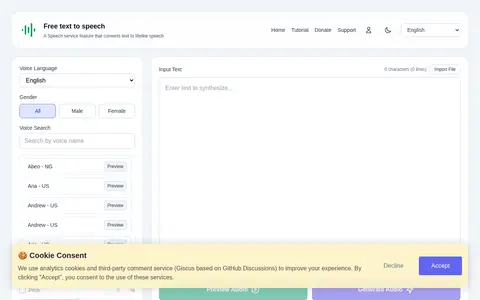
A free online text-to-speech tool that converts text into speech using an AI voice generator. It offers 100+ voices in 27 languages, allows MP3 download, and lets users adjust speed and pitch. No registration is required.
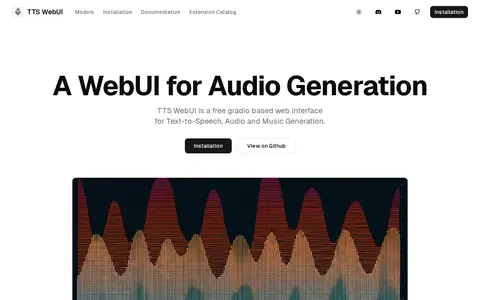
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
Vocal Remover uses AI for speech, voice, transcription, music, or other audio workflows.
AnyVoiceLab offers a free long-form text-to-speech converter that processes up to 50,000 characters, about one hour of audio, without requiring login. Users paste text and choose a voice to generate narration and can download the audio for free. A paid premium tier adds a timeline editor for pauses, speed changes, splitting and merging audio.
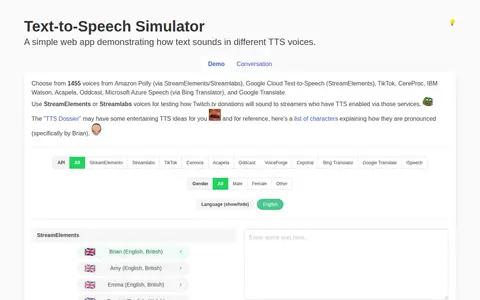
LazyPy is a web-based text-to-speech simulator that demonstrates how text sounds in different TTS voices. It offers a choice of over 1,000 voices from Amazon Polly, Google Cloud Text-to-Speech, TikTok, CereProc, IBM Watson, Acapela, Oddcast, Microsoft Azure Speech and Google Translate. Voices from StreamElements or Streamlabs can be used to test how Twitch.tv donations will sound.
Readwise Reader is a read-it-later app that saves articles, newsletters, RSS feeds, PDFs, EPUBs, YouTube videos and Twitter threads in one place. It offers web highlighting and annotation through a browser extension and integrates with the Readwise app, which resurfaces highlights via Daily Review and exports them to note-taking tools.
Vocali.se is a free web service that separates vocals and music from songs or audio files, allowing users to create karaoke versions. It runs a machine learning engine using pre-trained Demucs models and requires no software installation or account registration. Processing takes less than three minutes, after which the separated files download automatically.
En uses AI for speech, voice, transcription, music, or other audio workflows.
Ondoku is text-to-speech software that reads text up to 5,000 characters free of charge and offers paid plans converting up to 1 million characters a month. Generated audio can be saved as MP3 files and used commercially. It runs in a browser on PC or smartphone without installation.
Splitter uses AI for speech, voice, transcription, music, or other audio workflows.
Zyphra uses AI for speech, voice, transcription, music, or other audio workflows.