huggingface.co
Space emoji (emoji-only character allowed).
Directory
AI audio and speech covers voice synthesis, transcription, and machine learning tools for sound. Listings include text to speech services, dictation and meeting transcription, voice cloning, music generation, and open source models you can run yourself. The languages and accents each one handles matter, along with the length limit for a single job and whether processing happens on your device or on a remote server. Quality and cost also move, since some services change their limits often and a model you can host yourself behaves differently from a hosted one. Voice cloning and generated speech raise consent and rights questions, so use your own recordings or material you are allowed to use.
Space emoji (emoji-only character allowed).
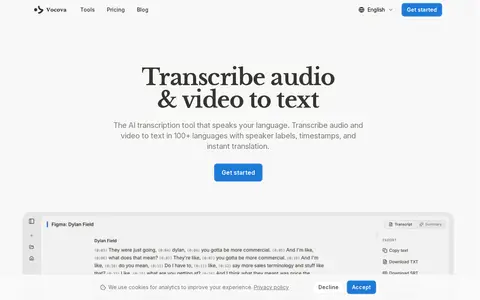
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.

Voctro Labs is a Barcelona-based company founded in 2011 that develops AI-based voice, music and audio technologies for creative companies and individuals. Its products include Voiceful, a toolkit for speech and singing voice experiences with a cloud-based API and SDK libraries, and Virtual Singers for Yamaha's VOCALOID software. Services include personalized voices and customized algorithms.
Voice Dream Reader is a text-to-speech app that reads PDFs, web pages, and books aloud. It supports importing PDFs, EPUBs, Word documents, PowerPoint files, and web pages, with highlighting, notes, offline listening, and syncing across iPhone, iPad, and Mac. Accessibility features include VoiceOver support, Dynamic Type, Voice Control, and braille display support.
Voicery is a company that creates natural-sounding text-to-speech engines and custom brand voices for enterprise clients. Its solutions leverage deep-learning research optimized for specific business use cases and technical infrastructure.
Voicesphere is an AI document interaction tool that allows users to upload documents including PDFs, DOCs, PPTs, videos, texts, and CSVs to ask natural language questions and receive context-specific answers. It includes a secure document management system, and is designed for use by manufacturing companies, medical professionals, law firms, researchers, recruitment agencies, and customer service teams.
voicetoinstrument.com is an AI audio conversion platform that transforms uploaded voice recordings, hummed melodies, or vocal tracks into realistic instrument sounds. It supports conversion to more than 100 instruments including piano, guitar, violin, saxophone, drums, and flute, and offers a free online converter alongside additional AI audio tools such as stem splitters and vocal removers.
Vosk is an offline speech recognition API hosted in the alphacep/vosk-api GitHub repository. It is compatible with Android, iOS, Raspberry Pi, and server environments, and provides SDKs for Python, Java, C#, and Node.
A simple and efficient end-to-end Automatic Speech Recognition (ASR) system from Facebook AI Research.
Works with speech, voice, music or other audio using machine-learning models.
USE BAZEL VERSION=5.0.0./bazelisk-linux-amd64 build wavegru mod -c opt --copt=-march=native.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.

A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
Works with speech, voice, music or other audio using machine-learning models.
Whisper command line client compatible with the original OpenAI client and based on CTranslate2. It uses CTranslate2 and the Faster-whisper implementation. The project lists Docker images with pre-loaded models, speaker diarization, voice activity detection and live transcription from a microphone. It is installed as a Python package or run from a Docker image.
A C/C++ port of OpenAI's Whisper automatic speech recognition model, providing high-performance inference without dependencies. It supports CPU-only inference and GPU backends, and runs on platforms including macOS, iOS, Android, Linux, Windows, WebAssembly and Raspberry Pi. The whisper-cli example currently runs only with 16-bit WAV files.
Wispr Flow is a voice-to-text dictation tool that converts speech into text in any app and on every device. It includes a Notetaker feature. It is available on Mac, Windows, iPhone, and Android. A free plan includes speech-to-text in any app and 100+ languages; paid plans add team management and admin controls.
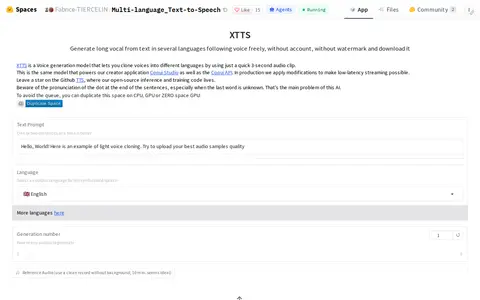
XTTS is a Hugging Face Space that provides multi-language text-to-speech functionality. It converts written text into spoken audio across multiple languages, and allows users to optionally upload a short voice recording or use their microphone for voice input.
YobiYoba is a speech recognition service that transcribes audio and video recordings into editable, time-coded text. Users upload files, specify or auto-detect the language, verify and edit transcripts, then download them in formats such as SRT, PDF, or VTT. Processing produces speaker labels, time codes, and confidence scores. Pricing is pay-as-you-go, from 0.01 € per minute of speech.

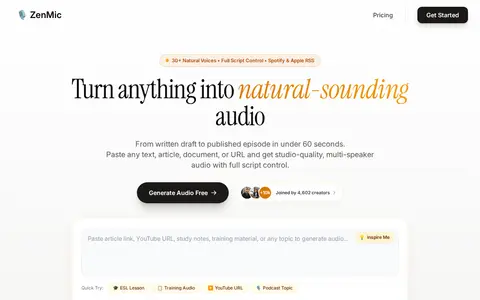
Zenmic.com is an AI audio generation tool that converts text, documents, URLs or topics into natural-sounding audio. It is targeted at ESL teachers, learning and development teams, and podcast creators, and offers features including full script control, over 30 voices, MP3 export, support for 125 languages, up to six speaker tracks, and voice cloning. Users can start using the tool for free without a credit card.
Audio.Z.AI uses AI for speech, voice, transcription, music, or other audio workflows.
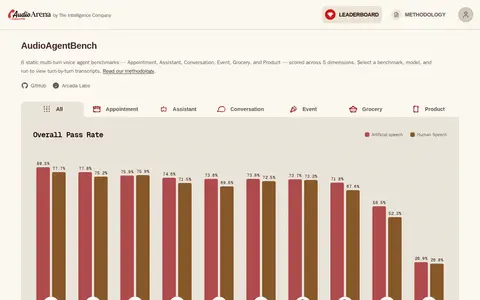
AudioArena is a site for benchmarking and comparing voice models through real conversations. It offers AudioAgentBench, a set of six static multi-turn voice agent benchmarks, scored across five dimensions, and lets users select a benchmark, model, and run to view turn-by-turn transcripts.
Fish Audio provides AI text-to-speech and voice cloning with emotion control and multilingual support. It offers TTS, speech-to-text, voice agents, and developer APIs with Python and TypeScript SDKs. The site lists a free tier with 8,000 monthly credits and paid Plus, Pro, and Max plans.
Paper2Audio is a free text-to-speech service designed for reading digital documents aloud. It supports PDFs, EPUBs, web articles, and other common document formats, uses natural AI voices for accurate reading, and includes no ads or paywalled voice features. The tool correctly processes figures, tables, and mathematical content, and skips extraneous page elements like inline references and endnotes to focus on relevant content.