app.coval.dev
Architecture of voice AI, from speech recognition to emotional intelligence, and learn how to build, scale, and evaluate them.
Directory
AI audio and speech covers voice synthesis, transcription, and machine learning tools for sound. Listings include text to speech services, dictation and meeting transcription, voice cloning, music generation, and open source models you can run yourself. The languages and accents each one handles matter, along with the length limit for a single job and whether processing happens on your device or on a remote server. Quality and cost also move, since some services change their limits often and a model you can host yourself behaves differently from a hosted one. Voice cloning and generated speech raise consent and rights questions, so use your own recordings or material you are allowed to use.
Architecture of voice AI, from speech recognition to emotional intelligence, and learn how to build, scale, and evaluate them.
Free speech-to-text tool for content creators that accurately transcribes audio & video files up to 2GB.
Dadabots describes itself as a band of music hackers using DIY neural nets and open source tools such as PyTorch and Ableton. Its featured works include 24/7 livestreams generating death metal and a neural technical death metal livestream.
Discover amazing ML apps made by the community.
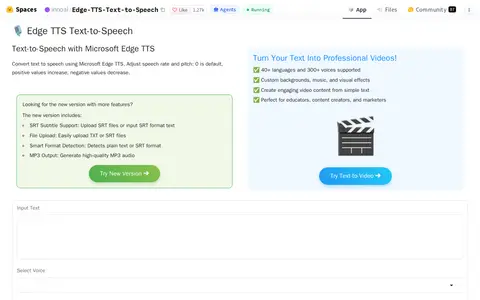
Edge TTS Text To Speech is a Hugging Face Space developed by innoai that converts user-input text to speech. Users can select from dozens of voice options, adjust speech speed and pitch, and generate high-quality MP3 audio files for playback or download. The space is currently running.
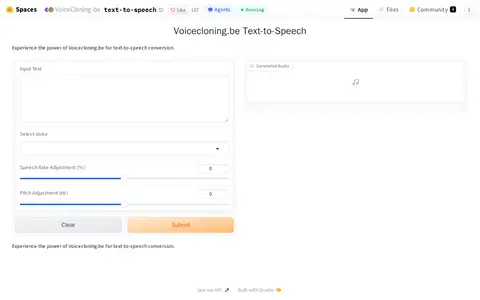
This is a duplicated instance of the Edge TTS Text To Speech Hugging Face Space, created by VoiceCloning-be. It offers the same text-to-speech functionality as the original, allowing users to input text, select voices, adjust speech rate and pitch, and generate customized audio output. The space is currently running.
Endel is a mobile app that provides personalized soundscapes intended to help with focus, relaxation and sleep, backed by neuroscience. The app adapts sounds in real time using inputs such as time of day, weather, heart rate and location. It also offers versions for Apple Watch, Amazon Alexa, TV, desktop and streaming platforms.
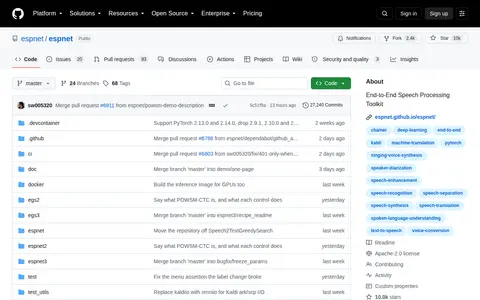
EspNet is an end-to-end speech processing toolkit hosted on GitHub. It is open-source software designed for speech processing tasks, with repository documentation covering installation steps, quick start guidance, and details of supported processing tasks. Contributors can participate in its development via the GitHub platform.
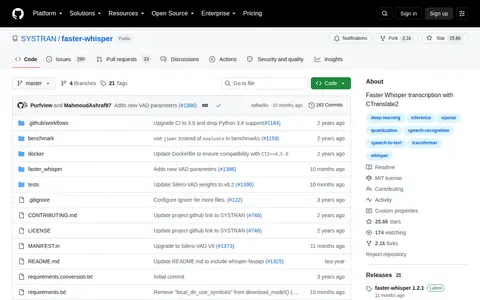
Fast inference engine for whisper in C++ using CTranslate2.
結婚式スピーチ・弔辞・年賀状・退職挨拶・お礼状・お詫び文など、冠婚葬祭と日常の手紙・挨拶文をAIが作成します。シチュエーションを選んで項目を埋めるだけで、そのまま使える文面が完成。82種類のツールを登録不要・完全無料で今すぐ使えます。.
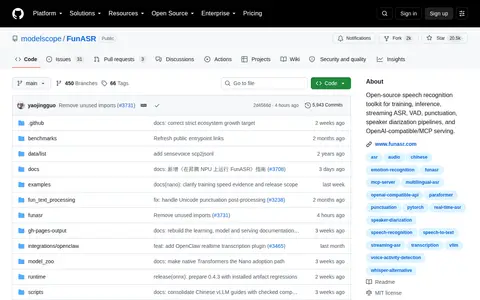
FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.
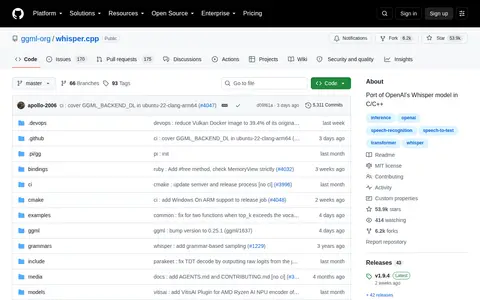
Port of OpenAI's Whisper model in C/C++. It can be executed locally.
Good Tape is an automated transcription tool for video and audio that supports more than 100 languages. It offers speaker labels, AI summaries and a recorder app for iOS and Android. Uploaded recordings are processed and stored on servers inside the EU and are not used to train any model.
Harmonai is a Stability AI lab that releases open-source generative audio tools for music production. Its stated goal is to make music creation more accessible and enjoyable for all users, with tools that support custom infinite sound library generation to expand creative possibilities for musicians.
Img To Music uses AI for speech, voice, transcription, music, or other audio workflows.
Infinite Music provides distribution, publishing, funding, marketing, and a hands-on team for independent artists. It claims to have paid out over $10 million to artists building their catalogs. The service targets independent musicians seeking comprehensive support.

High-quality text-to-speech and voice recognition.
Kaldi is a speech recognition toolkit, and kaldi-asr/kaldi is described as the official location of the Kaldi project. The repository includes build instructions for UNIX systems and Windows and points to example system builds.
Deploy and scale machine learning models on Kubernetes. Built for LLMs, embeddings, and speech-to-text.
LANDR is a music creation and release platform combining AI mastering, distribution, plugins, samples, collaboration tools and courses. The site describes unlimited AI mastering, distribution to over 150 streaming platforms, samples and effect and instrument plugins. It also lists online music courses and collaboration tools for remote sessions. Pricing is presented as starting at USD $8.25/month for LANDR Studio.
Letterfork is an AI tool that turns one Substack, Beehiiv or Ghost newsletter issue into posts for LinkedIn, X, Bluesky, Substack Notes, Threads, Instagram and Reddit in the writer's own voice. Users train a voice profile from past newsletters, then paste an issue to generate platform-native drafts.
A Hugging Face Space that converts text into speech in various languages, including Lojban and English. Users enter text and choose language and voice settings, then receive audio output. The Space is listed as sleeping due to inactivity.
Implementation of MusicLM, Google's new SOTA model for music generation using attention networks, in Pytorch.
Lyria by Google DeepMind is a music generation model developed by Google DeepMind, positioned as the organization's most advanced system for AI-powered music creation. It is designed to support creative music production alongside related AI experiments, as part of Google DeepMind's broader portfolio of specialized AI models for generating high-fidelity music and audio.