Directory

Search results

Published directory entries matching your search.

Search results

210 listings
github.com

NVIDIA NeMo Speech is a framework built for researchers and developers working on speech AI, including automatic speech recognition and text-to-speech. The repository provides open weight checkpoints and demos through a Hugging Face collection. It is licensed under Apache-2.0 and has pivoted to focus on audio, speech, and multimodal LLMs.
AI Audio & Speech 0

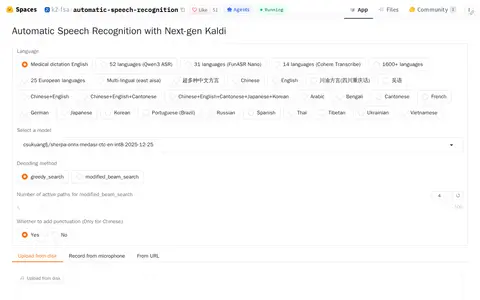
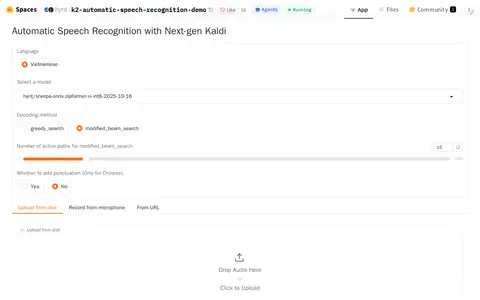
This Automatic Speech Recognition Hugging Face Space converts spoken audio to written text. Users can upload audio files, record from their microphone, or provide an audio URL, and select options including language, model, decoding method, and punctuation.

AI Audio & Speech 0

This Automatic Speech Recognition Hugging Face Space processes audio files, microphone recordings, or audio clips up to 40 seconds from a URL, and outputs the spoken content as written text.

AI Audio & Speech 0

Tunisian Speech Recognition is a Hugging Face Space created by SalahZa. The application transcribes spoken Tunisian Arabic into text using Arabic characters. Users can provide input audio either by recording through a microphone or uploading an audio file, and the tool returns the corresponding text transcription.
AI Audio & Speech 0
huggingface.co

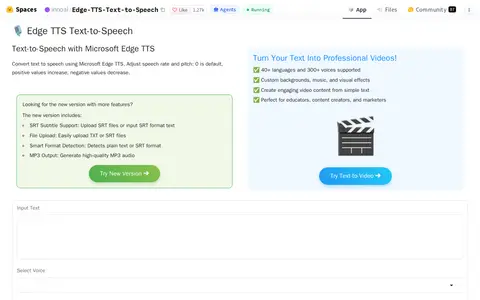
Edge TTS Text To Speech is a Hugging Face Space developed by innoai that converts user-input text to speech. Users can select from dozens of voice options, adjust speech speed and pitch, and generate high-quality MP3 audio files for playback or download. The space is currently running.

AI Audio & Speech 0
huggingface.co

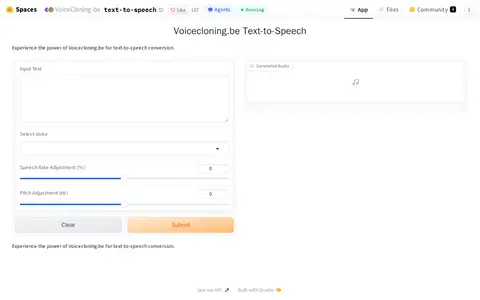
This is a duplicated instance of the Edge TTS Text To Speech Hugging Face Space, created by VoiceCloning-be. It offers the same text-to-speech functionality as the original, allowing users to input text, select voices, adjust speech rate and pitch, and generate customized audio output. The space is currently running.

AI Audio & Speech 0
huggingface.co

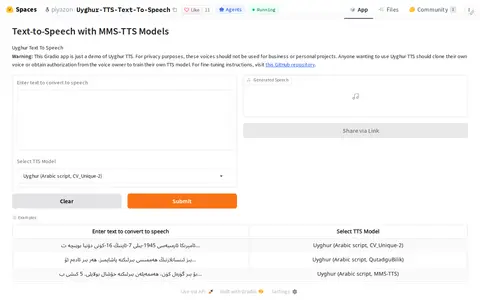
Uyghur TTS Text To Speech is a Hugging Face Space developed by piyazon. The application allows users to input Uyghur text, including numbers, Chinese characters and punctuation, select a Uyghur text-to-speech voice, and convert the typed text into natural-sounding Uyghur speech audio.

AI Audio & Speech 0
yobiyoba.com

YobiYoba is a speech recognition service that transcribes audio and video recordings into editable, time-coded text. Users upload files, specify or auto-detect the language, verify and edit transcripts, then download them in formats such as SRT, PDF, or VTT. Processing produces speaker labels, time codes, and confidence scores. Pricing is pay-as-you-go, from 0.01 € per minute of speech.

AI Audio & Speech 0

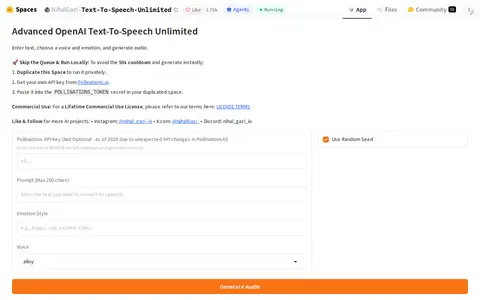
A Hugging Face Space that generates speech from entered text. Users choose a voice and an emotion style and can optionally set a seed. The app sends requests to the Pollinations service and returns an MP3 file with the synthesized speech.

AI Audio & Speech 0
huggingface.co

A Hugging Face Space by amphion titled Text To Speech. The application converts text into speech using various voice options, with speaker selection and adjustable speaking rate. For advanced users, it also allows mixing two voices.

AI Audio & Speech 0
huggingface.co

This Hugging Face Space by k2-fsa is a text-to-speech application that converts user-entered text to spoken audio. Users can select a language or model, and may upload or record a short reference audio clip to generate speech in a specific person's voice.

AI Audio & Speech 0
aidictation.com

AI Dictation is a voice typing app for people who mix English into Russian, Ukrainian or Belarusian. It removes filler words and adds punctuation without translating work terms. It runs on Mac, Windows, iPhone and Android, and speech recognition can run on device while cleanup runs in the cloud.

AI Audio & Speech 0
cmusphinx.github.io

CMUSphinx is an open source speech recognition system for mobile and server applications. It supports C, C++, C#, Python, Ruby, Java and JavaScript, and Unix, Windows, iOS, Android and hardware platforms. The related PocketSphinx 5.1.0 release adds Python 3.14 support and pre-built wheels for Linux/arm64.

AI Audio & Speech 0
app.coval.dev

Architecture of voice AI, from speech recognition to emotional intelligence, and learn how to build, scale, and evaluate them.

AI Audio & Speech 0
github.com

FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.

AI Audio & Speech 0
ispeech.org

High-quality text-to-speech and voice recognition.

AI Audio & Speech 0
github.com

Kaldi is a speech recognition toolkit, and kaldi-asr/kaldi is described as the official location of the Kaldi project. The repository includes build instructions for UNIX systems and Windows and points to example system builds.

AI Audio & Speech 0
github.com

OpenQuack is a menu-bar voice dictation app for macOS. Pressing a hotkey and speaking places the transcript at the cursor. Speech recognition runs locally via WhisperKit on Apple Silicon, with no cloud, account, or signup by default. The project is written in Swift and released under the MIT license.

AI Audio & Speech 0
huggingface.co

NeMo Parakeet ASR Models attain strong speech recognition accuracy while being efficient for inference. Available in CTC and RNN-Transducer variants.

AI Audio & Speech 0
github.com

Vosk is an offline speech recognition API hosted in the alphacep/vosk-api GitHub repository. It is compatible with Android, iOS, Raspberry Pi, and server environments, and provides SDKs for Python, Java, C#, and Node.

AI Audio & Speech 0
github.com

A simple and efficient end-to-end Automatic Speech Recognition (ASR) system from Facebook AI Research.

AI Audio & Speech 0
github.com

A C/C++ port of OpenAI's Whisper automatic speech recognition model, providing high-performance inference without dependencies. It supports CPU-only inference and GPU backends, and runs on platforms including macOS, iOS, Android, Linux, Windows, WebAssembly and Raspberry Pi. The whisper-cli example currently runs only with 16-bit WAV files.

AI Audio & Speech 0