


interviewsby.ai
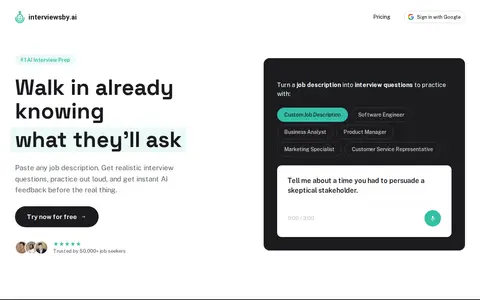
Interviews by AI is an AI-powered interview preparation service. It turns a job description into generated behavioral and technical interview questions that users practice out loud or in writing, then receive instant feedback built on frameworks such as STAR, along with a sample answer.