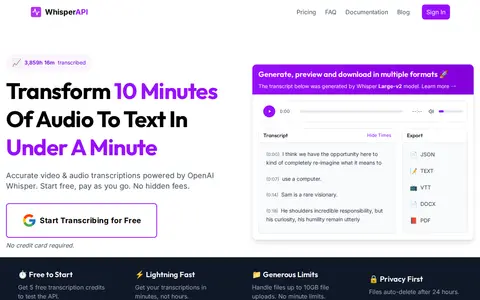
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
Directory
Search results
Published directory entries matching your search.
Sonix service for transcribing radio broadcasts, interviews, podcasts, and spoken audio.
AudioCraft is a code base for generative audio tasks including music, sound effects, and compression, trained on raw audio signals. MusicGen produces music samples from text inputs, and AudioGen produces audio from environmental sounds via text-to-sound generation. The models use the EnCodec neural audio codec to learn discrete audio tokens from waveforms.
Audio.Z.AI uses AI for speech, voice, transcription, music, or other audio workflows.
Stable Audio uses AI for speech, voice, transcription, music, or other audio workflows.
Tunisian Speech Recognition is a Hugging Face Space created by SalahZa. The application transcribes spoken Tunisian Arabic into text using Arabic characters. Users can provide input audio either by recording through a microphone or uploading an audio file, and the tool returns the corresponding text transcription.
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.
Audacity is a free, open-source audio editor and recorder. It can cut, trim, split, reverse and mix audio, apply effects such as reverb, compressor and distortion, reduce noise and remove vocals. It runs on Windows, macOS and Linux, supports major audio formats and third-party plugins, and includes AI transcription.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
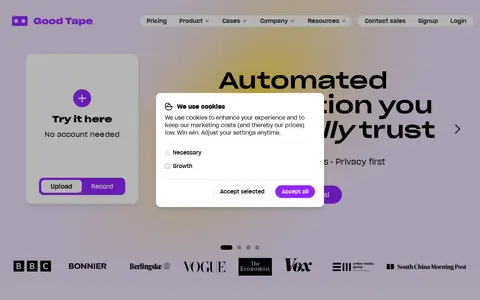
Good Tape is an automated transcription tool for video and audio that supports more than 100 languages. It offers speaker labels, AI summaries and a recorder app for iOS and Android. Uploaded recordings are processed and stored on servers inside the EU and are not used to train any model.
Img To Music uses AI for speech, voice, transcription, music, or other audio workflows.
Replica Studios uses AI for speech, voice, transcription, music, or other audio workflows.
The Prompter vicc Substack uses AI for speech, voice, transcription, music, or other audio workflows.
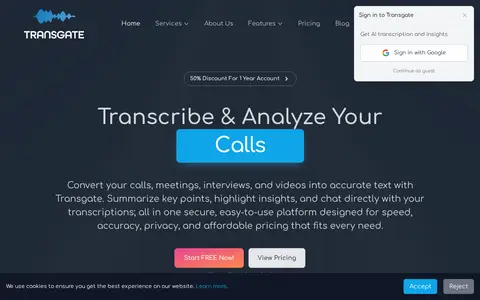
Transgate is an AI transcription and translation service for audio and video. It offers two services: transcribe or translate in 50+ languages, with summaries, highlights and the ability to chat with transcripts. Files are uploaded, processed by AI, and results can be exported. It uses a pay-as-you-go model.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
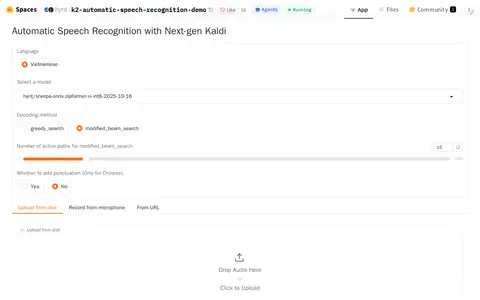
This Automatic Speech Recognition Hugging Face Space converts spoken audio to written text. Users can upload audio files, record from their microphone, or provide an audio URL, and select options including language, model, decoding method, and punctuation.
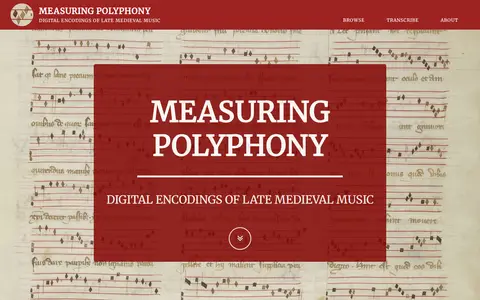
Project presenting digital encodings of late medieval polyphonic music in mensural notation, linked where possible to high-resolution manuscript images and MIDI audio files. It aims to make transcriptions and audio freely available online and to encode the notation in a machine-readable format for search and analysis.
Google Illuminate uses AI for speech, voice, transcription, music, or other audio workflows.
Acapella Extractor uses AI for speech, voice, transcription, music, or other audio workflows.
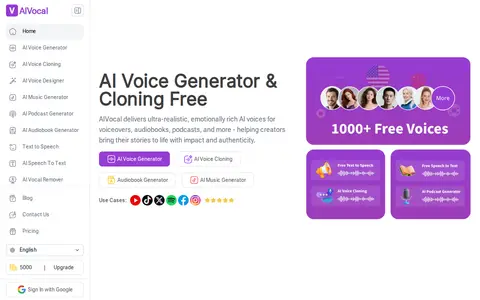
AIVocal is an AI-powered voice assistant platform. It provides tools for AI voice generation, voice cloning, text-to-speech, speech-to-text, vocal removal, audiobook generation, podcast generation and audio transcription, serving creators and professionals for voice-related work.
AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.
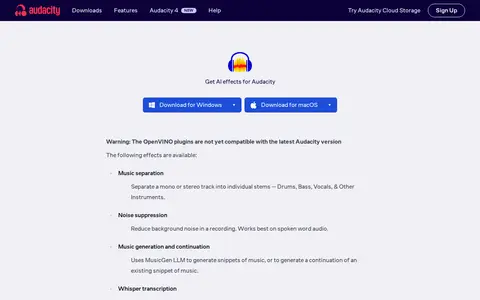
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.