Voice is an open source audiobook player for Android under the GPL. It organizes the user's own audiobook files into a listening library with resume positions, bookmarks, sleep timer, playback speed, silence skipping, and Android Auto support. It has no account, no ads and no forced cloud sync. It is distributed via Google Play, F-Droid and IzzyDroid.
Directory
Search results
Published directory entries matching your search.
Voice is a code project with source, releases, documentation, or setup notes.
AnyVoiceLab is a free, no-login-required AI voice cloning tool. Users provide a short voice sample to create lifelike voice replicas, generate studio-quality speech, and download the resulting audio for free. Additional features include long-form text-to-speech, voice changing, sound effect generation, premium voice options, AI voice generation, payment plans, and support for emotion tags in speech.
Voice-Swap is an AI voice platform for musicians, content creators, and artists. It offers a text-to-speech voiceover studio, a singing studio for voice swapping and stem separation, and custom voice model training. The site states that voice modelling, generation and rights management are combined into a single system.
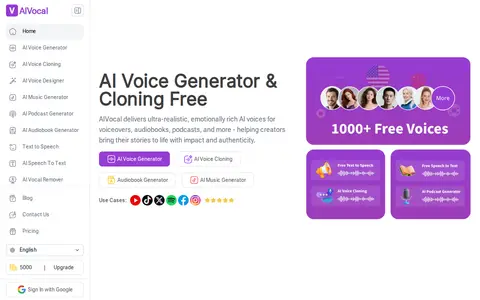
AIVocal is an AI-powered voice assistant platform. It provides tools for AI voice generation, voice cloning, text-to-speech, speech-to-text, vocal removal, audiobook generation, podcast generation and audio transcription, serving creators and professionals for voice-related work.
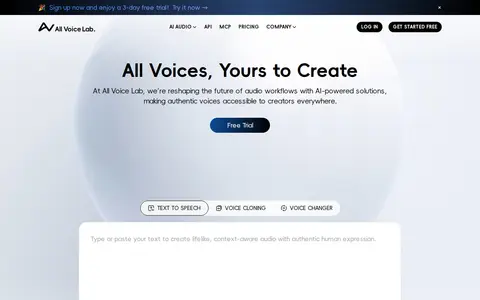
All Voice Lab offers AI voice cloning, text-to-speech and a real-time voice changer for creators, aimed at video dubbing and podcasts. Its text-to-speech is described as adapting tone, rhythm and pitch to text sentiment, and the site states the AI integrates 33 major languages. A proprietary voice model named MaskGCT is also presented, alongside API and MCP access.
Applio is an open-source AI voice conversion suite. It provides voice conversion, real-time voice changing, speech synthesis, model training, voice blending and audio analysis. The project states it is MIT licensed and runs on Windows, macOS and Linux, with a desktop app or Gradio WebUI, and no accounts or telemetry.
Respeecher provides an AI voice generator for professional production workflows. It offers enterprise-grade voice cloning and synthetic speech services, including a real-time text-to-speech API for voice agents. Its Voice Marketplace supplies over 40 AI voices and a plugin for Pro Tools. The company serves entertainment, film, TV, animation, games, broadcasting, sports, podcasts, audiobooks, music, and advertising sectors. Free testing and flexible integration are available.
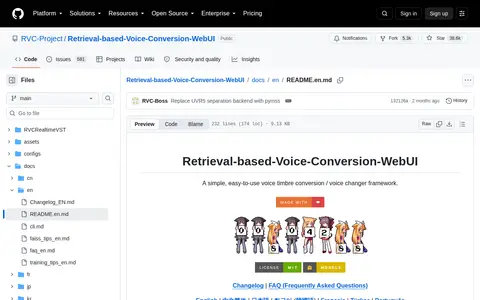
Retrieval-based-Voice-Conversion-WebUI is a project for training voice conversion models from voice data, with an easy-to-use WebUI. It includes a pymss/MSST model to separate vocals and instruments and a high-pitch voice extraction algorithm to prevent a muted sound problem. Dependencies differ by hardware, including CPU, AMD, Intel and NVIDIA GPU setups.
Acapela Group is a company that develops personalized digital voices using voice AI technology. It offers text-to-speech solutions for services, applications and devices, with support for over 30 languages and more than 200 pre-made voices, plus custom voice creation options. The company provides SDKs for multiple platforms, cloud streaming APIs, and specialized solutions including voice AI for accessibility, transport and customer interaction.
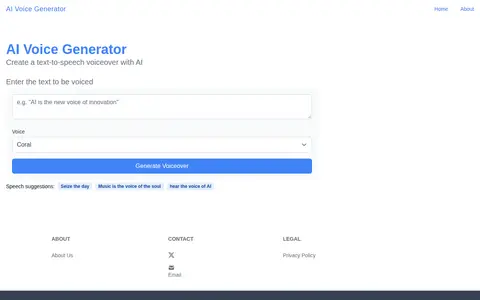
AI Voice Generator is a free online tool that produces natural-sounding text-to-speech voice overs. Users enter text, select from various AI voices, and generate a voiceover. The service emphasizes simplicity and accessibility for creating spoken content.
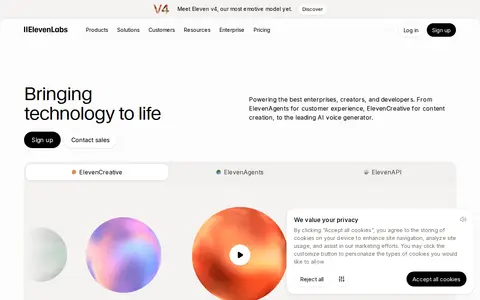
ElevenLabs is an AI voice and audio platform. It provides an AI voice generator with access to more than 5,000 voices across over 70 languages, plus voice cloning, text-to-speech, dubbing, music generation, sound effect design, and conversational AI agent tools. The platform serves both individual creators and enterprise customers, with SDKs and APIs available for developers.
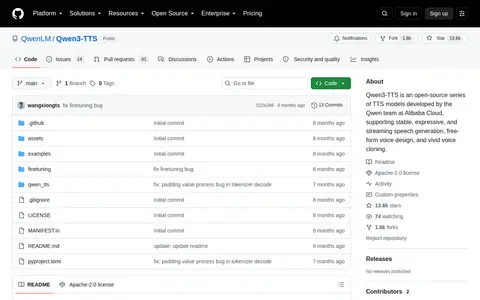
Qwen3-TTS is an open-source series of text-to-speech models developed by the Qwen team at Alibaba Cloud. It supports speech generation, streaming output, free-form voice design and voice cloning, and covers ten major languages with dialectal voice profiles. The release includes models of 0.6B and 1.7B parameters.
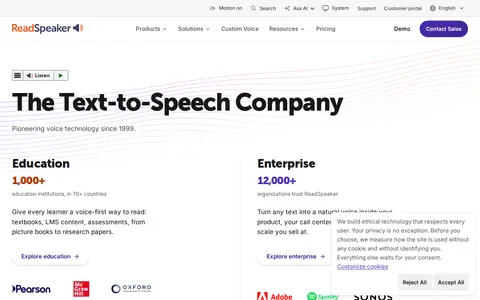
ReadSpeaker is a text-to-speech company that converts text to natural-sounding voice output for education and enterprise use cases. Its offerings include web accessibility tools, custom brand voice development, and voice AI for third-party products, with support for more than 90 languages. The company provides a range of products including text-to-speech APIs, SDKs, and embedded solutions, with sector-specific solutions for gaming, transportation, government, healthcare, and other industries.
Trans Voice Party is a resource hub for trans voice training. It lists starting-point guides, community links such as Reddit and Discord groups, YouTube channels, documentation, masculinization and androgynization resources, and teachers. It also notes outdated resources from roughly 2019 or older.
VCClient is software that performs real-time voice conversion using AI. It supports several AI models and offers both standalone use on a local PC and voice conversion over a network, and it provides a REST API. Editions support different models, and Windows and M1 Mac versions can be downloaded from a Hugging Face repository.
Voice Dream Reader is a text-to-speech app that reads PDFs, web pages, and books aloud. It supports importing PDFs, EPUBs, Word documents, PowerPoint files, and web pages, with highlighting, notes, offline listening, and syncing across iPhone, iPad, and Mac. Accessibility features include VoiceOver support, Dynamic Type, Voice Control, and braille display support.
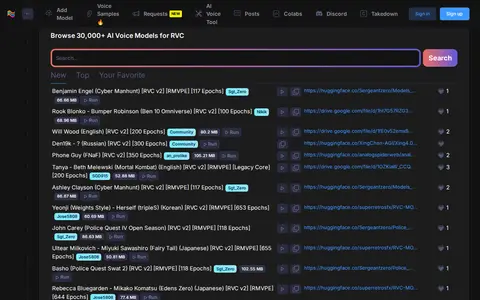
A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.
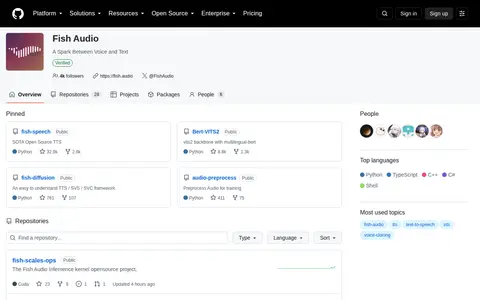
Fish Audio is an AI platform for voice generation, voice cloning, and audio storytelling, and its GitHub organization hosts open source repositories. Public repositories include fish-speech, described as SOTA open source TTS, Bert-VITS2, a vits2 backbone with multilingual-bert, and fish-diffusion, a TTS / SVS / SVC framework.
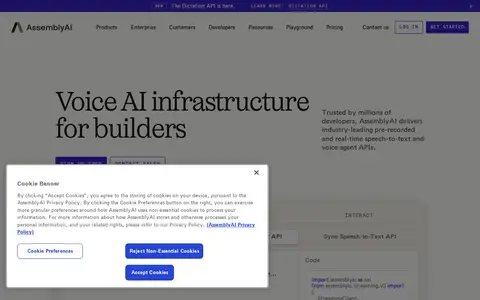
AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.
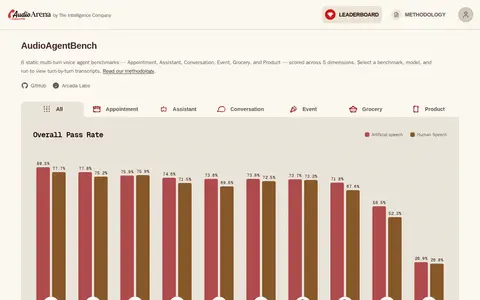
AudioArena is a site for benchmarking and comparing voice models through real conversations. It offers AudioAgentBench, a set of six static multi-turn voice agent benchmarks, scored across five dimensions, and lets users select a benchmark, model, and run to view turn-by-turn transcripts.
A community database of voice over actors and the characters they play. It presents images and sound clips of actors and their roles across cartoons, anime, TV shows, movies, video games, shorts, commercials and attractions.
Common Voice is a miscellaneous web resource for discovery, directories, archives, web culture, or useful tools.
Voice Notepad is a speech-to-text tool that uses Google Speech Recognition to let users type with their voice in any language. It runs in Google Chrome and requires microphone access, and provides controls to start, copy, save, publish, tweet, email, print and clear the transcribed note. A text-to-speech section offers voice, pitch and speed settings.