TEXT-IMAGE.com generates text-images and ASCII art from pictures on a user's device. The converter accepts JPG, PNG, GIF, WEBP and BMP files and lets users choose the characters, their random or sequential order, image width and font size. The resulting HTML representation can be shared via a public link stored for five days.
Directory
Search results
Published directory entries matching your search.
Dezgo is an online tool for generating images and videos from text in styles such as realistic, anime, cartoon, illustrations and logos. It also lists controlled text-to-image, background removal, upscaling, in-painting from text and image editing from text, alongside image-to-image and text-to-video tools.
This is a Hugging Face Space created by Joeythemonster, duplicated from BilalSardar/Text-To-image-AllModels, for text-to-image generation. Users can input text descriptions and select artistic styles to customize generated image output. The space is currently running and refreshing.
Text-to-Music And Text-to-Image Generator is a Hugging Face Space created by HarshRathi09. It accepts text prompts to generate either musical compositions or images, allowing users to turn ideas into audio or visual content. The space is currently running.
Imagen is a text-to-image diffusion model from Google Research's Brain Team that creates photorealistic images from input text. It builds on large transformer language models for text understanding and cascaded diffusion models for image generation. The project also introduced DrawBench, a benchmark for comparing text-to-image models.
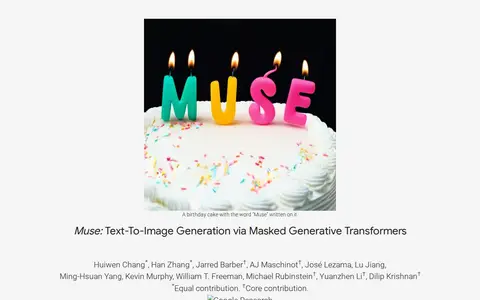
Muse is a text-to-image Transformer model that generates images from text prompts and supports image editing, including inpainting, outpainting and mask-free editing, without fine-tuning or inverting the model. It is trained on a masked modeling task in discrete token space using text embeddings from a pre-trained language model.
This is a Hugging Face Space created by Rowdy013 for text-to-image generation. Users can input text descriptions to generate images using a text-to-image model. The space is currently running and refreshing.
Wan is an AI creative platform. It aims to lower the barrier to creative work using artificial intelligence. The site lists features including text-to-image, image-to-image, text-to-video, image-to-video and image editing.
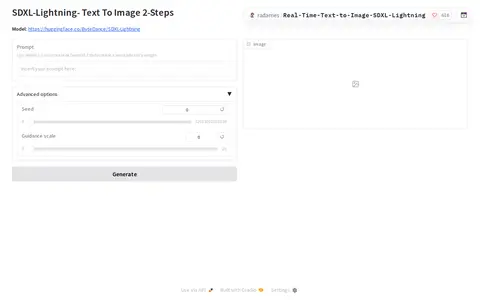
Real-Time Text-to-Image SDXL Lightning is a Hugging Face Space created by user radames. It allows users to input a text description of a desired image, with optional adjustments to seed and guidance strength. The application generates a matching image and provides it as a downloadable file using the SDXL Lightning model for fast generation.
Detextify is a Python library that removes unwanted pseudo-text from images generated by generative AI models. It runs text detection on an image, masks the detected text boxes and in-paints the masked regions until the image is text-free, either locally or through existing APIs.
TextFixer is a collection of free online web tools for text and conversion tasks. It includes tools to fix text, convert text to HTML, remove line breaks, generate random words, remove HTML tags, alphabetize text, convert images to PDF, and convert Word documents to HTML.
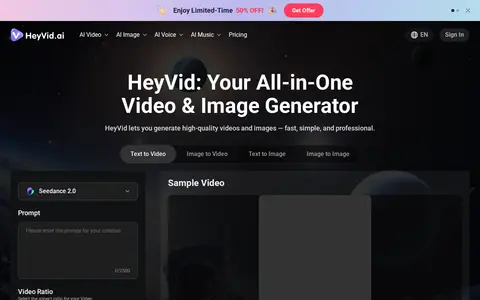
HeyVid is an all-in-one video and image generator that provides access to multiple top video and image models, including Kling, Sora, Runway, Midjourney and Flux, from a single platform. It offers text-to-image, image-to-video and text-to-video creation tools.
Image To Character Text is a Hugging Face Space by Claudz163. It takes an uploaded image and a chosen character and produces a caption describing the image in that character's style, such as a rapper or Shrek.
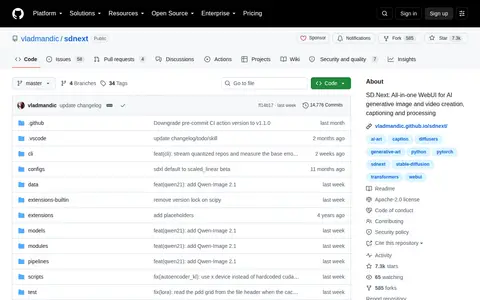
SD.Next is an open-source web interface for generating and editing images and video with diffusion models. It supports text-to-image, image-to-image, text-to-video and image-to-video workflows, and also offers captioning, tagging, upscaling, interpolation and colorization. It runs on NVIDIA, AMD, Intel, Apple Silicon or CPU setups, and includes a queue for scheduling tasks.
A page by pharmapsychotic collecting tools and resources for AI art, organized into sections such as text to image, upscaling, StyleGAN, text video, prompt engineering and music. It links to shared Google Colab notebooks for text-to-image work with pre-trained GAN and diffusion models, and notes Stable Diffusion WebUI for running SD locally.
Real-Time Latent Consistency Model Text to Image creates or edits images with generative AI and text-based controls.
Real-Time Latent Consistency Model Text-to-Image-Lora-SD1.5 creates or edits images with generative AI and text-based controls.
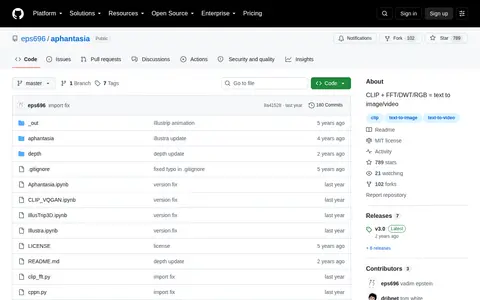
Aphantasia is a collection of text-to-image tools built on the CLIP model and the Lucent library, with FFT/DWT/RGB parameterizers for no-GAN generation. It grew out of the artwork of the same name and offers text-to-image and text-to-video generation.
This is a Hugging Face Space created by user shikharyashmaurya. The application allows users to upload an image, then generates a detailed text prompt that describes the content of the uploaded image. This generated prompt can be used to recreate the original image using an image generation tool. The space is currently active and has received 50 likes from the Hugging Face community.
Prompt Refinery - Text to Image Gradio is a Hugging Face Space created by user awacke1 that expands short user-provided image generation prompts into more detailed versions using MagicPrompt, then generates images from the expanded prompts. The Space has received 44 likes on the Hugging Face platform.
AIFreeForever is a free online text-to-image generation tool that does not require user sign-up or login. It offers unlimited image generation without watermarks, and provides access to over 20 top AI image models including Nano Banana 2, Imagen 4, Flux 2 Pro, and other leading models. Users can generate images from text prompts, adjust output size, select models, and upscale results.
Lucy Text To Image is a Hugging Face Space created by tonyassi that generates realistic dress images using Stable Diffusion. Users input a dress description, select preferences including color, features, occasion, and garment type, and the tool builds a prompt to produce the image, with optional element swapping functionality.
TokenVerse is a method for multi-concept personalization that uses a pre-trained text-to-image diffusion model. It can disentangle complex visual elements and attributes from a single image and combine concepts extracted from multiple images, supporting objects, accessories, materials, pose and lighting. It uses a DiT-based text-to-image model and learns modulation-space directions for each word.
Image To Image Generation is a Hugging Face Space by yashAI007. It generates new images from a prompt and an initial image, with settings for model, scheduler and image dimensions.