github.com
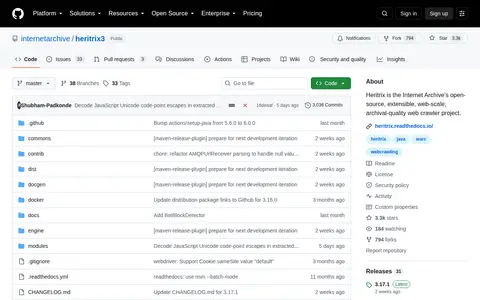
Heritrix is the Internet Archive's open-source web crawler project, described as extensible, web-scale and archival-quality. It is designed to respect robots.txt exclusion directives and META nofollow tags. Documentation covers getting started, operating, configuring crawl jobs and the REST API. It is free software under the Apache License, Version 2.0, with some files under other licenses.