
en.wonderlink.de
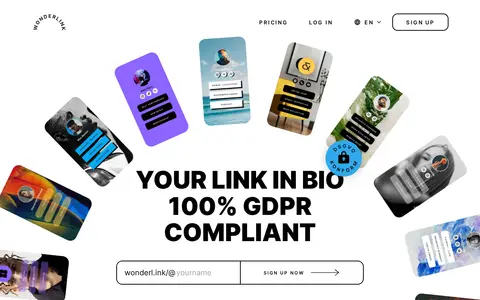
Wonderlink is a link-in-bio service for creating a single mobile page holding links to social profiles, shops, blogs and other channels. It offers a permanently free version and an optional Pro version with more design, statistics and function options. Legal pages such as imprint and data protection can be managed centrally.