Impala is a distributed C++ query engine for SQL queries over petabytes of data stored in Apache Hadoop clusters. It supports data in HDFS, Apache HBase and Amazon S3, window functions and subqueries, and uses LLVM for on-the-fly code generation. It is Apache-licensed and open source, and the repository is a mirror of Apache Impala.
Directory
Search results
Published directory entries matching your search.
A genomics processing engine and specialized file format built using Apache Avro, Apache Spark and Parquet. Apache 2 licensed.
Koalas, from Databricks, implements the pandas DataFrame API on top of Apache Spark. The repository is marked deprecated and in maintenance mode; Koalas supports Apache Spark 3.1 and below, and PySpark is recommended directly for Spark 3.2 and above. It is available under the Apache-2.0 license.
Apache MXNet is a deep learning framework mixing symbolic and imperative programming. It includes a dynamic dependency scheduler that parallelizes symbolic and imperative operations, with a graph optimization layer for symbolic execution. The repository was archived on Nov 17, 2023, and is read-only.
A distributed machine learning framework Apache Spark.
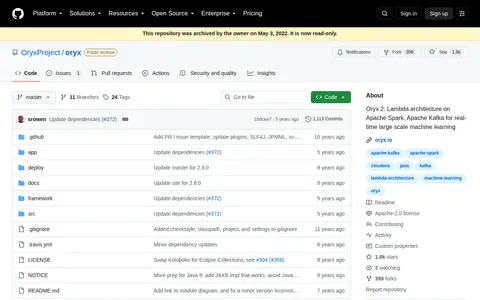
Oryx 2 is a realization of the lambda architecture built on Apache Spark and Apache Kafka, specialized for real-time large scale machine learning. It is a framework for building applications and includes packaged end-to-end applications for collaborative filtering, classification, regression and clustering. The repository was archived by the owner on May 3, 2022, and is read-only.
Platform to programmatically author, schedule, and monitor workflows.
Bernstein is an open-source, Apache-2.0 licensed AI Agents Governance and Orchestration framework. Users can write governance rules declaratively, and Bernstein enforces these rules while producing verifiable, replayable records of agent activity. The project is associated with the website bernstein.run.
Choco is the open-source Chocolatey client, described as a package manager for Windows akin to yum or apt-get. It requires .NET Framework 4.8+, PowerShell 2.0+, and Windows Server 2008 R2+ or Windows 10+. The project is licensed under Apache 2.0, and users can run choco.exe --help for command information.
ClearTK is a framework for developing statistical natural language processing components in Java, built on top of Apache UIMA. It is developed by the Center for Computational Language and Education Research (CLEAR) at the University of Colorado at Boulder. The project is built with Maven, and the repository includes sub-projects such as cleartk-feature and modules for several machine learning libraries.
Clojure-openNLP is an open-source Clojure library that provides an interface to the Apache OpenNLP natural language processing toolkit. Hosted as a public GitHub repository, it includes usage instructions for the Leiningen build tool and sample usage from a Clojure REPL.
DALL·E Mini is a project for generating images from a text prompt. The repository provides installation for inference and development, a training script, and links to trained models on the Hugging Face Model Hub. The model can be used on Craiyon, and community projects include DALL-E Playground and DALL·E Flow. It is released under the Apache-2.0 license.
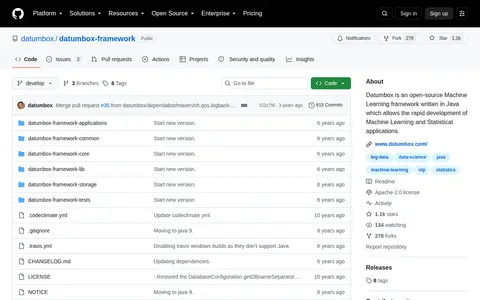
Datumbox is an open-source machine learning framework written in Java for rapid development of machine learning and statistical applications. It focuses on including many machine learning algorithms and statistical methods and on handling large datasets. The code is licensed under the Apache License, Version 2.0, and releases are available on Maven Central, including version 0.8.2.
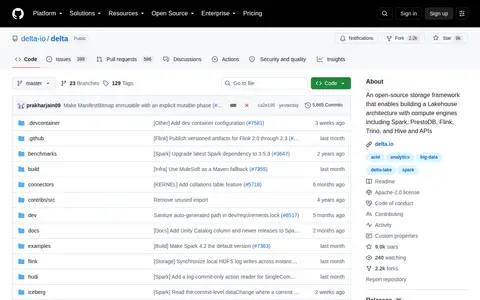
Delta Lake is an open-source storage framework designed to support the construction of a Lakehouse architecture. It is compatible with multiple compute engines including Apache Spark, PrestoDB, Flink, Trino, and Hive, as well as associated APIs.
Flux is the official inference repository for FLUX.1 models from Black Forest Labs. It contains minimal inference code for running image generation and editing with the open-weight models, including text-to-image, in/out-painting, structural conditioning and image variation variants. The repository is distributed under the Apache-2.0 license.
Future AGI is an open-source, self-hostable platform for evaluating, observing, and improving LLM and AI agent applications. It combines tracing, evals, simulations, datasets, a gateway and guardrails on one platform with a feedback loop. The Apache 2.0 core can be self-hosted, and a managed Cloud option is offered.
A Clojure dataframe library that runs on Apache Spark.
H2O Sparkling Water is an open-source GitHub repository maintained by the h2oai organization. It provides H2O machine learning functionality that can run inside Apache Spark clusters. The repository includes getting started guides, user documentation, binary download options, and resources for testing the tool.
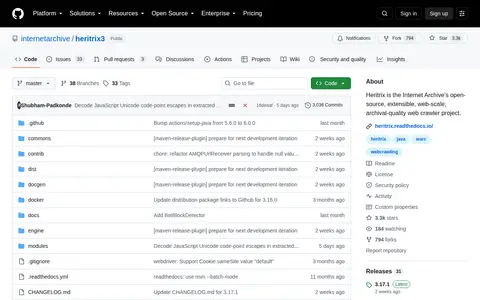
Heritrix is the Internet Archive's open-source web crawler project, described as extensible, web-scale and archival-quality. It is designed to respect robots.txt exclusion directives and META nofollow tags. Documentation covers getting started, operating, configuring crawl jobs and the REST API. It is free software under the Apache License, Version 2.0, with some files under other licenses.
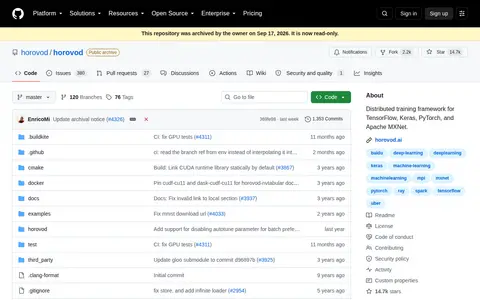
Distributed deep learning training framework for TensorFlow, Keras, PyTorch, and Apache MXNet.
Docs to Markdown is a free Google Docs add-on that converts a Google Doc to simple, readable Markdown or HTML text. It lets users draft in Google Docs and convert part of a document, and requires minimal permissions. The source is published under the Apache 2.0 license.
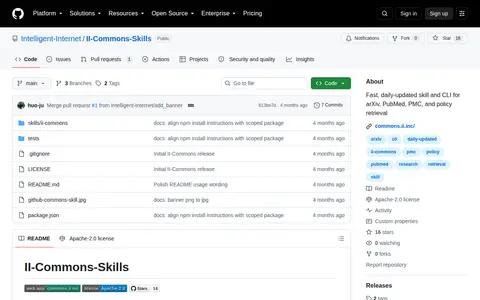
II-Commons-Skills provides fast, deterministic retrieval across arXiv, PubMed / PMC and supported US policy corpora, distributed as an npm package and CLI requiring Node.js 18 or newer. Basic usage works without authentication, and an API token is available for higher usage limits. It is licensed under Apache-2.0.
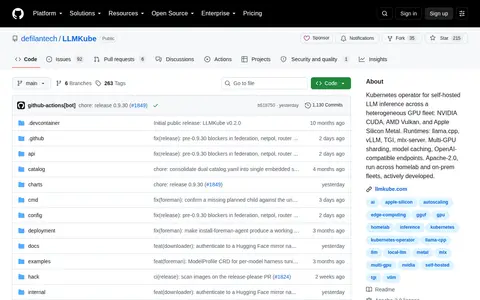
LLMKube is a Kubernetes operator for self-hosted large language model inference across heterogeneous GPU fleets supporting NVIDIA CUDA, AMD Vulkan, and Apple Silicon Metal. It supports runtimes including llama.cpp, vLLM, TGI, and mlx-server, offers multi-GPU sharding, model caching, and OpenAI-compatible endpoints. It is licensed under Apache-2.0 and designed for homelab and on-prem fleet deployment, and is actively developed.
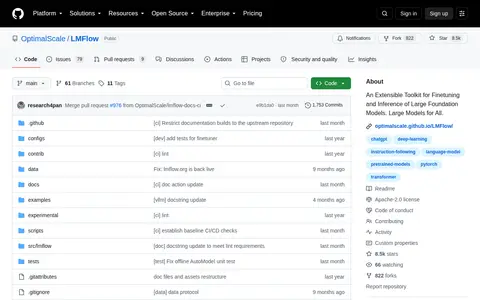
LMFlow is a toolkit for finetuning and inference of large foundation models, presented as extensible, convenient and efficient. It offers support for custom optimizer training, conversation templates, speculative decoding, long context inference with position interpolation for LLaMA models, and Flash Attention-2. The project is released under the Apache-2.0 license and was made available on PyPI.