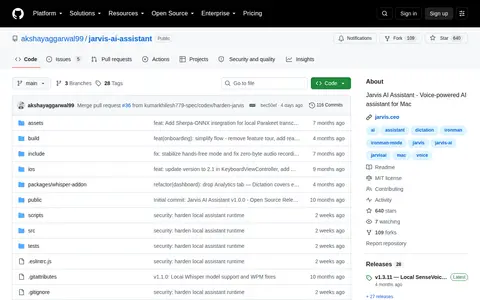
Jarvis AI Assistant is a voice dictation application for Mac that transcribes speech into text. It removes filler words, fixes grammar and supports local transcription with Whisper or Parakeet and local LLMs via Ollama, or cloud services. It is released under the MIT license and is described as open-source and local-capable.
Directory
Search results
Published directory entries matching your search.
Filters
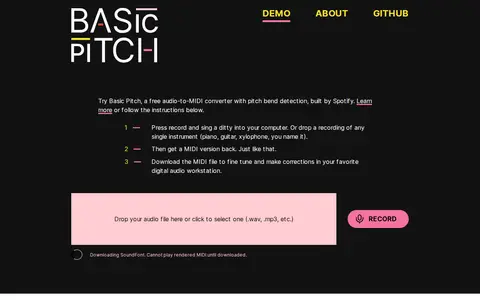

basicpitch.spotify.com
Basic Pitch is an open source audio-to-MIDI converter from Spotify that features pitch bend detection. It works on recordings of almost any single instrument, including voice, and converts audio files into MIDI files that can be edited in a digital audio workstation. It is available as an online demo.
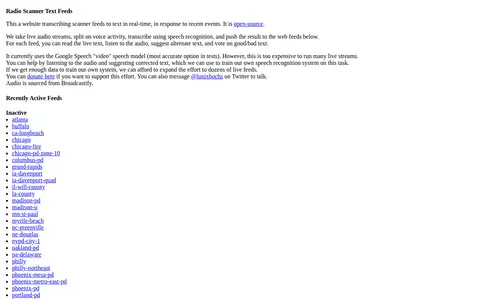
feeds.talonvoice.com
Radio Scanner Text Feeds is an open-source website that transcribes live radio scanner audio into text in real time. Audio streams are split on voice activity, transcribed with speech recognition, and published to web feeds. Visitors can read the live text, listen to the audio, suggest alternate text, and vote on the text. Audio is sourced from Broadcastify.
microsoft.com
Microsoft SwiftKey is a keyboard app for Android and iPhone that adapts to the user's typing style. It offers autocorrect and next-word predictions, swipe typing, voice typing, a cloud clipboard, and support for typing in up to five languages without switching settings.

us-phone-number.com
US-Phone-Number.com is a free website for receiving SMS messages and voice mails online without registration; users select a temporary phone number from a list. The site lists numbers in the Netherlands, United Kingdom and Finland and states the service can receive messages from services including Facebook, Telegram, WeChat, VK, PayPal and AliPay.
github.com
An alternative Discord client with voice support made with C++ and GTK 3
acetaggen.com
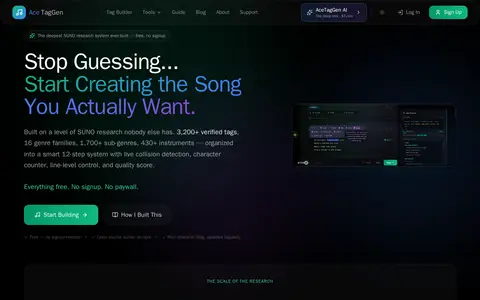
AceTagGen is a free prompt system for SUNO AI. It offers a structured 12-step Tag Builder, a library of verified tags, a prompt scorer, and a research blog with articles and guides. No signup is required.
github.com
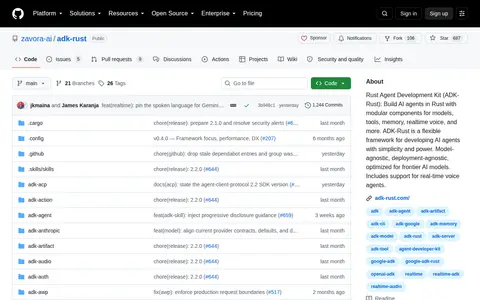
ADK-Rust is a GitHub repository for the Rust Agent Development Kit, a flexible framework for building AI agents in Rust. It includes modular components for models, tools, memory, and realtime voice support, is model-agnostic and deployment-agnostic, and is optimized for frontier AI models.
alex.smola.org
A personal blog by Alex Smola titled Adventures in Data Land, covering machine learning topics. Entries include efficient LLM inference tutorials, random projections, effective sample size, voice agents and evaluation, and porting MXNet to Blackwell and Apple Silicon. Posts reference events such as the Machine Learning Summer School 2026 in NYC.
aimastering.com
AI Mastering is an automated online audio mastering service that uses AI. Free mastering is available, with drag-and-drop uploading, target loudness and mastering level customization, and output format, spectrum and loudness analysis. An API is documented, and a desktop offline version has been released.

aiweddingtoast.com
AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.

aicaller.io
AICaller.io is a robocaller that makes automated outbound phone calls using AI for sales and marketing. It supports lead qualification, meeting booking, appointment booking and data gathering, offers a choice of voices, and connects to over 6,000 applications via Zapier. It can be used through a web portal or APIs.
aider.chat
Aider is an AI pair programming tool that runs in the terminal and works with cloud and local LLMs. It maps the codebase, supports more than 100 code languages, and integrates with Git to automatically commit changes. It can also run in an IDE and accept voice-to-code instructions.
aiva.ai
AIVA is an AI music generation assistant that creates new songs in more than 250 styles within seconds. Users can build style models, upload audio or MIDI influence, and edit generated tracks. A free plan offers non-commercial use with credit to AIVA and three downloads per month.
blog.youtube
A YouTube Blog post announcing an early look at the company's first AI-related music experiments: Dream Track for Shorts and Music AI tools, built in collaboration with Google DeepMind. Dream Track is powered by the Lyria music generation model and initially lets a small group of select US creators create soundtracks of up to 30 seconds for Shorts.
anvevoice.app
AnveVoice adds an AI voice assistant to a website with a script tag. The agent converses with visitors and performs actions such as navigating pages, filling forms and booking appointments. The service supports 50+ languages and reports 487ms P50 latency. A free plan includes 50K tokens per month.
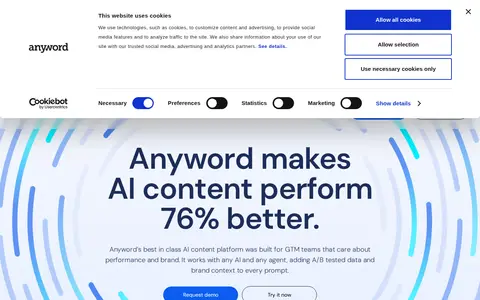
anyword.com
Anyword is a generative AI content platform and performance API for go-to-market teams. It adds A/B-tested data and brand context to prompts and works with any AI model or application. The platform includes a data-driven editor, content intelligence, brand voice features, and integrations with marketing channels such as Google Ads, Meta, and LinkedIn.
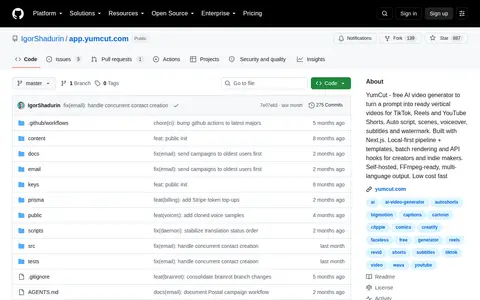
github.com
YumCut - free AI video generator to turn a prompt into ready vertical videos for TikTok, Reels and YouTube Shorts. Auto script, scenes, voiceover, subtitles and watermark. Built with Next.js. Local-first pipeline + templates, batch rendering and API hooks for creators and indie makers. Self-hosted, FFmpeg-ready, multi-language output. Low cost fast
github.com
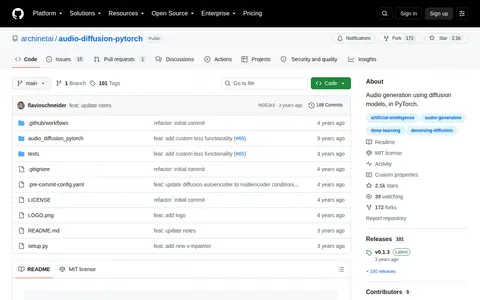
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.
audacityteam.org
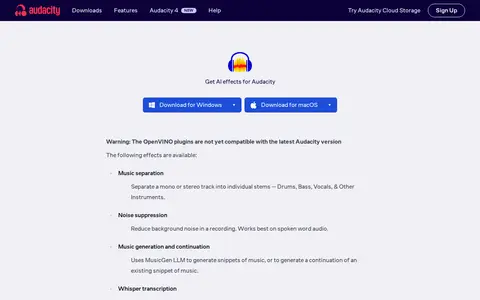
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.

audify-ai.com
Audify AI is a text-to-speech converter that turns written text into speech using AI models from OpenAI. Users can select voices, adjust speaking speed, and download audio in formats such as MP3, WAV, FLAC and OPUS. The site lists voiceovers, podcasts, audiobooks, accessibility and education among use cases.
audiocraft.metademolab.com
AudioCraft is a code base for generative audio tasks including music, sound effects, and compression, trained on raw audio signals. MusicGen produces music samples from text inputs, and AudioGen produces audio from environmental sounds via text-to-sound generation. The models use the EnCodec neural audio codec to learn discrete audio tokens from waveforms.
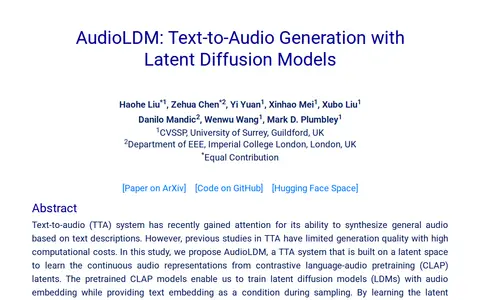
audioldm.github.io
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
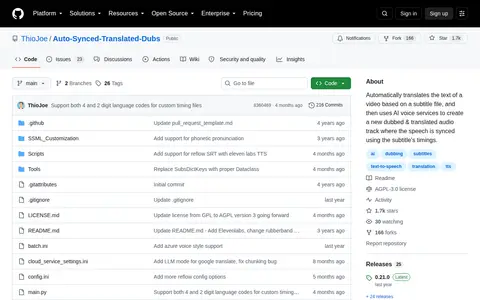
github.com
Auto Synced & Translated Dubs is a GitHub-hosted tool that automatically translates the text of a video's subtitle file, then uses AI voice services to generate a new dubbed and translated audio track synced to the original subtitle timings.