Voice Notepad is a speech-to-text tool that uses Google Speech Recognition to let users type with their voice in any language. It runs in Google Chrome and requires microphone access, and provides controls to start, copy, save, publish, tweet, email, print and clear the transcribed note. A text-to-speech section offers voice, pitch and speed settings.
Directory
Search results
Published directory entries matching your search.
Fish Audio provides AI text-to-speech and voice cloning with emotion control and multilingual support. It offers TTS, speech-to-text, voice agents, and developer APIs with Python and TypeScript SDKs. The site lists a free tier with 8,000 monthly credits and paid Plus, Pro, and Max plans.
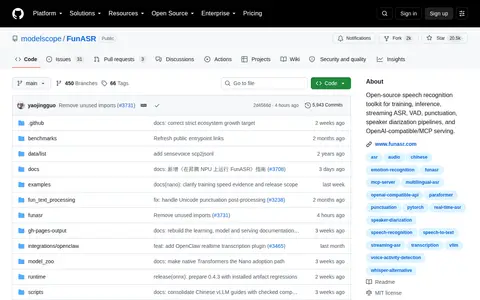
FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.
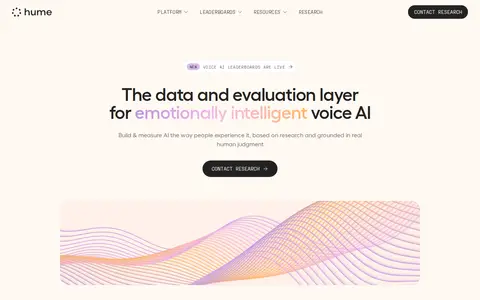
Hume provides voice AI evaluation infrastructure through its VoiceEQ platform. It turns real-world use cases into targeted evaluation suites and combines automated measurement with human judgment to diagnose failures in voice models and agents. The platform covers TTS, speech-to-speech, ASR, and cascaded systems, and the company reports support for over 50 languages.
Img To Music uses AI for speech, voice, transcription, music, or other audio workflows.
High-quality text-to-speech and voice recognition.
Kaldi is a speech recognition toolkit, and kaldi-asr/kaldi is described as the official location of the Kaldi project. The repository includes build instructions for UNIX systems and Windows and points to example system builds.
Deploy and scale machine learning models on Kubernetes. Built for LLMs, embeddings, and speech-to-text.
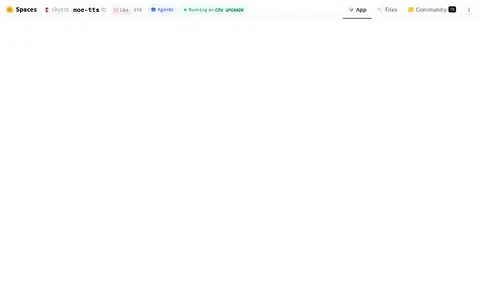
Moe TTS is a Hugging Face Space created by skytnt that enables users to generate speech from input text and convert existing audio to a different speaker's voice. Users can input text to create speech output, select from available speakers, and adjust the playback speed of generated audio.
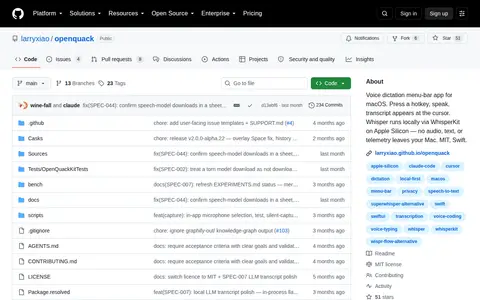
OpenQuack is a menu-bar voice dictation app for macOS. Pressing a hotkey and speaking places the transcript at the cursor. Speech recognition runs locally via WhisperKit on Apple Silicon, with no cloud, account, or signup by default. The project is written in Swift and released under the MIT license.
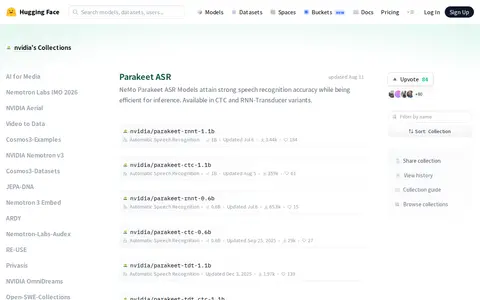
NeMo Parakeet ASR Models attain strong speech recognition accuracy while being efficient for inference. Available in CTC and RNN-Transducer variants.
Replica Studios uses AI for speech, voice, transcription, music, or other audio workflows.
Works with speech, voice, music or other audio using machine-learning models.
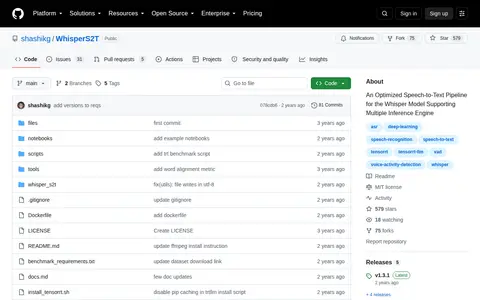
WhisperS2T is an optimized speech-to-text pipeline for the Whisper model that supports multiple inference engines. The repository provides release notes, quickstart guides, future roadmaps, and a benchmark and technical report.
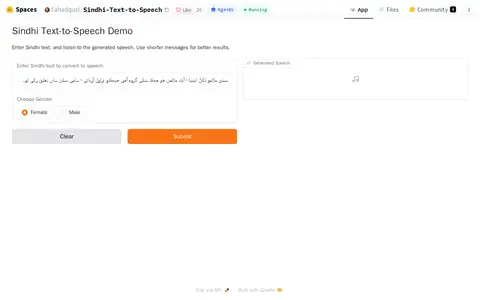
Sindhi TTS is a Hugging Face Space that generates speech from Sindhi text. Users input text and select a gender for the synthesized voice. The system works best with shorter messages.
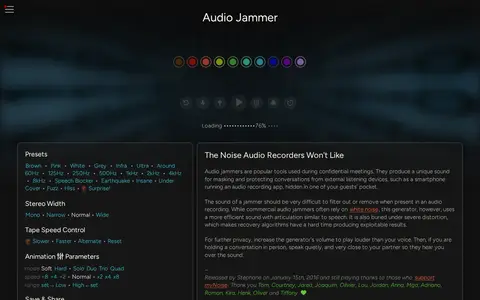
Audio jammer generator that masks speech with noise for privacy or sound experiments.
SpeechChat is a social media utility for platform customization, archives, embeds, or community tools.
Speechify is a text to speech and voice typing assistant that reads books, PDFs, documents and web pages aloud with natural-sounding voices. It offers text highlighting, speed control and scan and listen, and is available as browser extensions, desktop apps for Windows and Mac, and mobile apps for iOS and Android.
Speechling offers a collection of free language learning tools, including listening comprehension practice, dictation practice, vocabulary flashcards, fill-in-the-blank exercises, a language quiz, and an audio dictionary. The tools are described as free forever and require no login.
This Hugging Face Space by Xenova is a web application that converts user-entered text to spoken audio. Users can type or paste text into the app, which generates clear audio playback of the content without requiring file uploads.
Works with speech, voice, music or other audio using machine-learning models.
The Prompter vicc Substack uses AI for speech, voice, transcription, music, or other audio workflows.
SLA Speech Tools is a free and public repository for researchers and teachers interested in materials and tools on second language speech acquisition and pronunciation teaching. It offers peer-reviewed research tools and teaching tools, including explicit instruction, communicative form-focused activities and pronunciation-based tasks.
Works with speech, voice, music or other audio using machine-learning models.