Skale is a distributed data processing and machine learning engine that provides a high-level API in JavaScript and a parallel execution engine on top of Node.js. The repository was archived by its owner on May 29, 2021 and is read-only. It supports multiple data sources and formats, and can run in local or distributed mode.
Directory
Search results
Published directory entries matching your search.
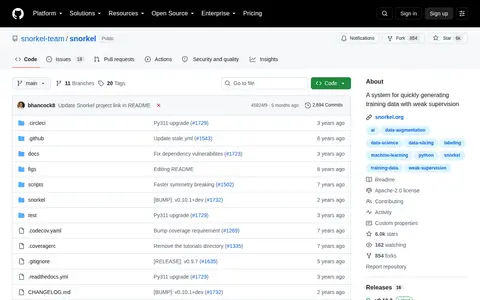
Snorkel is a system for quickly generating training data with weak supervision, released under an Apache-2.0 license and written in Python. The project started at Stanford in 2015 to programmatically label, build, and manage training data. The team now focuses on Snorkel Flow, an end-to-end AI application development platform based on the core ideas behind Snorkel.
Tonic is a tool for downloading, manipulating and loading event-based or spike-based data, described as similar to PyTorch Vision but for neuromorphic data. It provides event datasets and transformations, and the project states it is looking for a new maintainer.
Upgini is an open-source data search and enrichment library for Machine Learning and AI pipelines. It enables users to find and add relevant features from hundreds of public and premium external data sources, including open and commercial large language models.
Open CC-BY-4.0 dataset of evidence-graded dietary-supplement data covering dosing, bioavailability, drug-nutrient interactions and cost-per-effective-dose, with every clinical claim tied to a PubMed PMID. Compiled by Verified Supplement Data, it is mirrored on Hugging Face and Kaggle and offered as a free live JSON API.
AI Models Catalog is a structured YAML catalog of AI model providers and their models, sourced from first-party APIs and official documentation. It includes TypeScript type definitions and Zod runtime validation schemas, plus scripts to sync data from providers and validate YAML files against schemas.
AutoViz is a Python library that automatically visualizes any dataset, any size, with a single line of code. It also offers the FixDQ() function for a quick assessment of dataset quality and fixing data quality issues. The project aims to provide an automated approach to exploratory data analysis through quick and easy data visualization plus data quality, abstracting away the complexities of various plotting libraries and techniques.
CPU and GPU-accelerated matrix library intended to support large-scale exploratory data analysis.
NumPy and Pandas interface to Big Data.
Cerberus is a lightweight and extensible data validation library for Python. It provides type checking and other base functionality out of the box, is designed to be non-blocking and extensible for custom validation, and has no dependencies. It is available on PyPI and maintained according to semantic versioning since version 1.2.
The College ROI Dataset provides the 30-year net present value of U.S. colleges and majors. It is derived from FREOPP, IPEDS, and BEA data and is released under a CC BY 4.0 license. The dataset is maintained by le-teen.com.
d3py is a plotting library for Python based on D3. It builds on d3.js and the pandas DataFrame module to plot data from the command line or simple scripts into a browser window. Its README describes the code as an experiment, notes that it is not actively developed, and points to vincent as an alternative.
Dash is an open-source Python library for building data applications and dashboards without requiring JavaScript expertise. It is maintained by Plotly and hosted on the company's public GitHub repository, where users can access source code and contribute to the project.
A lightweight framework for data analysis in JavaScript.
Collect, clean and visualize your data in Python.
An agentic LLM for autonomous data science that performs data preparation, analysis, modeling, visualization, and report generation without human intervention. It supports open-ended research on structured, semi-structured, and unstructured data sources, and the model, code, training data, and demo are open-sourced.
Deepchecks is an open-source project for validating machine learning models and data from research to production. It includes built-in and custom checks and suites for tabular, NLP and CV validation, CI and testing management, and monitoring of deployed models. Installation is via pip.
Library of SAS Enterprise Miner process flow diagrams to help you learn by example about specific data mining topics.
Tools for exploratory data analysis in Python.
Functions and data dependencies for loading various word embeddings.
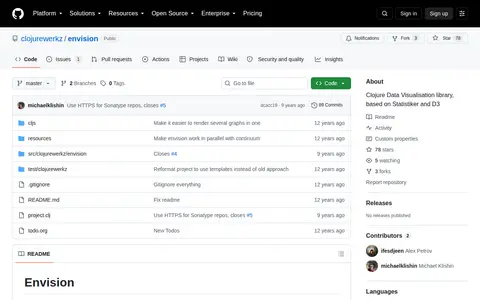
Clojure Data Visualisation library, based on Statistiker and D3.
DALI is a dataset of synchronised audio, lyrics and vocal notes, presented as a collection of gz files. A Python package, dali_code, is stored in the repository for reading and working with the data; release versions are installable via pip. The dataset was created automatically using a teacher-student machine learning paradigm, described in an ISMIR 2018 paper.
Analyzes structured data and helps produce queries, insights or visualizations.
Intake is a lightweight package for finding, investigating, loading, and disseminating data. It is hosted on GitHub at https://github.com/intake/intake. The repository includes documentation, installation instructions, development guidelines, and support information.