Directory

Search results

Published directory entries matching your search.

Search results

192 listings
github.com

FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.
AI Audio & Speech 0

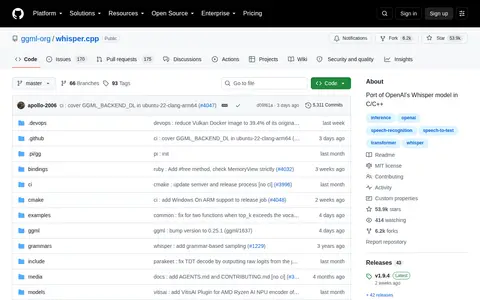
Port of OpenAI's Whisper model in C/C++. It can be executed locally.

AI Audio & Speech 0
github.com

PandasAI is an open-source library that enables conversational data analysis using large language models and retrieval-augmented generation. It allows users to interact with databases or datalakes supporting SQL, CSV, and parquet file formats.

Models & Machine Learning 0
github.com

Kaldi is a speech recognition toolkit, and kaldi-asr/kaldi is described as the official location of the Kaldi project. The repository includes build instructions for UNIX systems and Windows and points to example system builds.

AI Audio & Speech 0

A curated GitHub list of resources on audio-driven talking face generation. It organizes research papers and projects, including encoder-decoder and StyleGAN-based methods, pose-controllable and lip-sync work, and 3D model-based approaches.

AI Tools & Directories 0
github.com

Deploy and scale machine learning models on Kubernetes. Built for LLMs, embeddings, and speech-to-text.

AI Audio & Speech 0

Multidiffusion Upscaler For Automatic1111 is an AI Image Generation project hosted on GitHub that provides tiled diffusion and VAE optimization for the Stable Diffusion web UI, distributed under the CC BY-NC-SA 4.0 license.

AI Image Generation 0
github.com

MusicGen is a single-stage auto-regressive Transformer model for music generation trained over a 32kHz EnCodec tokenizer with four codebooks, part of the AudioCraft library. It supports text-to-music and text-plus-melody-to-music models ranging from 300M to 3.3B parameters. Running it locally requires a GPU, with at least 16 GB of memory recommended for medium-sized models.

AI Audio & Speech 0
github.com

NVIDIA NeMo Speech is a framework built for researchers and developers working on speech AI, including automatic speech recognition and text-to-speech. The repository provides open weight checkpoints and demos through a Hugging Face collection. It is licensed under Apache-2.0 and has pivoted to focus on audio, speech, and multimodal LLMs.

AI Audio & Speech 0
github.com

An offline AI application for phones and Macs that supports chat, image generation, vision, Whisper speech-to-text, tool calling and local-network servers. It runs on CPU, GPU or NPU, requires no account or API key, and keeps data on the device. A paid Pro tier adds voice mode, custom personas and draft-and-approve actions.

AI Image Generation 0
github.com

OpenQuack is a menu-bar voice dictation app for macOS. Pressing a hotkey and speaking places the transcript at the cursor. Speech recognition runs locally via WhisperKit on Apple Silicon, with no cloud, account, or signup by default. The project is written in Swift and released under the MIT license.

AI Audio & Speech 0

OpenVINO AI Plugins for Audacity is a set of AI-enabled effects, generators and analyzers for Audacity. The features run locally on the PC without an internet connection, using OpenVINO to run AI models on the system's CPU, GPU or NPU. Included tools cover music separation, noise suppression, MusicGen-based music generation and continuation, Whisper transcription and audio super resolution.

AI Audio & Speech 0
github.com

Optimum-TPU is a Hugging Face project providing Google TPU optimizations for transformers models, aiming to ease training and inference on TPUs. It supports text generation models including Gemma, Llama2, Llama3 and Mistral, and includes a text-generation-inference backend. The repository was archived in January 2026 and is read-only, with the project in maintenance mode.

Models & Machine Learning 0
github.com

WhisperS2T is an optimized speech-to-text pipeline for the Whisper model that supports multiple inference engines. The repository provides release notes, quickstart guides, future roadmaps, and a benchmark and technical report.

AI Audio & Speech 0
github.com

TabGAN is a software project hosted on GitHub under the Diyago/Tabular-data-generation repository. It focuses on the application of generative adversarial networks (GANs) to tabular data generation, reviewing and analyzing recent research and practical implementations in this field.

Models & Machine Learning 0

Text Generation Inference is a toolkit for deploying and serving large language models, implemented as a Rust, Python and gRPC server. It supports models including Llama, Falcon, StarCoder, BLOOM and GPT-NeoX, with features such as token streaming, continuous batching and quantization. The repository is archived, read-only, and in maintenance mode, with pull requests limited to minor bug fixes and maintenance.

Models & Machine Learning 0
github.com

Works with speech, voice, music or other audio using machine-learning models.

AI Audio & Speech 0

Accelerates transcription with the combination of OpenAI's Whisper Large v2, HF Transformers, Optimum, and flash attention.

AI Audio & Speech 0
github.com

Vosk is an offline speech recognition API hosted in the alphacep/vosk-api GitHub repository. It is compatible with Android, iOS, Raspberry Pi, and server environments, and provides SDKs for Python, Java, C#, and Node.

AI Audio & Speech 0
github.com

A simple and efficient end-to-end Automatic Speech Recognition (ASR) system from Facebook AI Research.

AI Audio & Speech 0
github.com

WFGY is an open-source project focused on AI reasoning, retrieval-augmented generation, AI agents, and real-world workflows. It is developing the WFGY 5.0 Polaris Protocol, and currently includes components such as the Problem Map, Global Debug Card, 4.0 version, and CFV Easter Egg.

Models & Machine Learning 0
github.com

Whisper command line client compatible with the original OpenAI client and based on CTranslate2. It uses CTranslate2 and the Faster-whisper implementation. The project lists Docker images with pre-loaded models, speaker diarization, voice activity detection and live transcription from a microphone. It is installed as a Python package or run from a Docker image.

AI Audio & Speech 0
github.com

A C/C++ port of OpenAI's Whisper automatic speech recognition model, providing high-performance inference without dependencies. It supports CPU-only inference and GPU backends, and runs on platforms including macOS, iOS, Android, Linux, Windows, WebAssembly and Raspberry Pi. The whisper-cli example currently runs only with 16-bit WAV files.

AI Audio & Speech 0
github.com

ACE-Step 1.5 is an open-source local music generation model released by the ace-step project under an MIT license. The repository states it supports Mac, AMD, Intel and CUDA devices, and describes a hybrid architecture combining a language model planner with a diffusion transformer on consumer hardware.
AI Audio & Speech 0