text-generation-inference

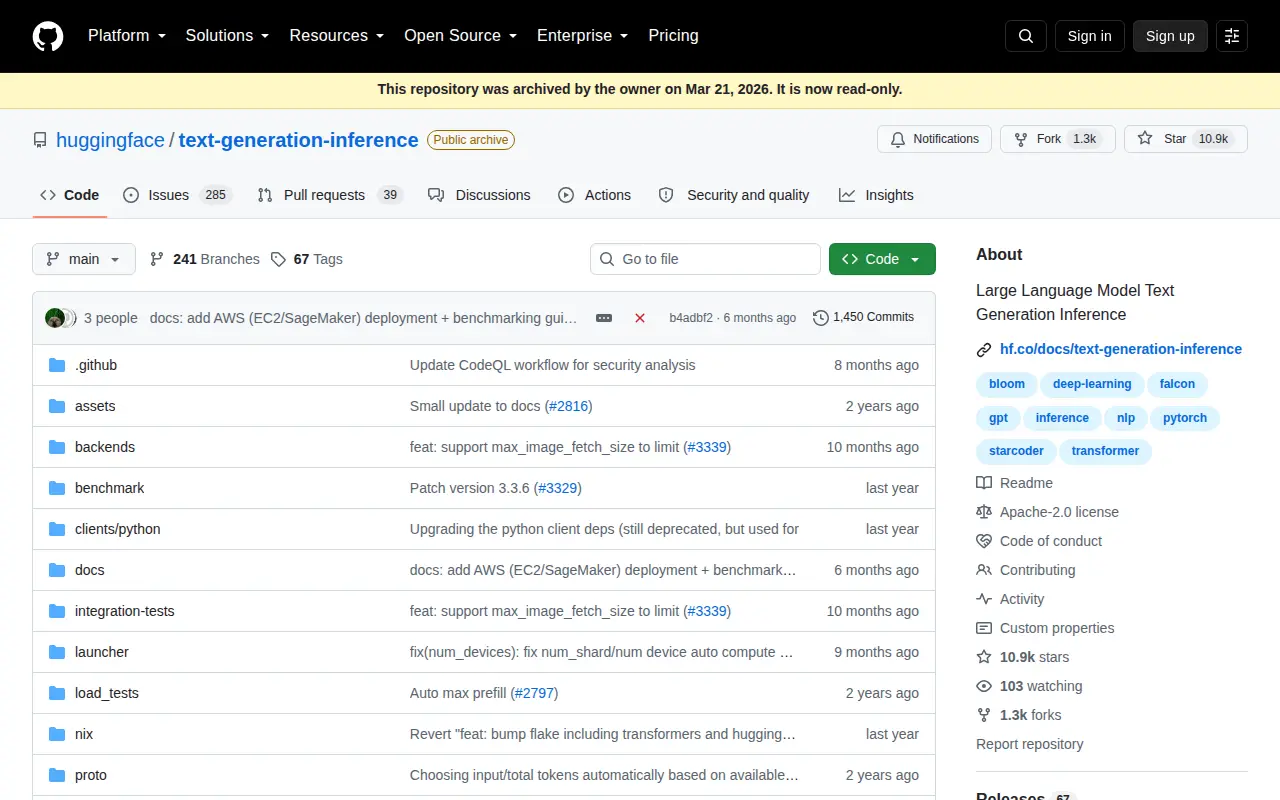
Text Generation Inference is a toolkit for deploying and serving large language models, implemented as a Rust, Python and gRPC server. It supports models including Llama, Falcon, StarCoder, BLOOM and GPT-NeoX, with features such as token streaming, continuous batching and quantization. The repository is archived, read-only, and in maintenance mode, with pull requests limited to minor bug fixes and maintenance.

GitHub repo Directory import
0 shouts Added Sep 23, 2026 github.com
github.com/huggingface/text-generation-inference
text-generation-inference website preview

Features

  • Tensor Parallelism for faster inference on multiple GPUs Source: github.com
  • Token streaming using Server-Sent Events (SSE) Source: github.com

Limitations

  • repository was archived by the owner on Mar 21, 2026 Source: github.com

Links

Tags