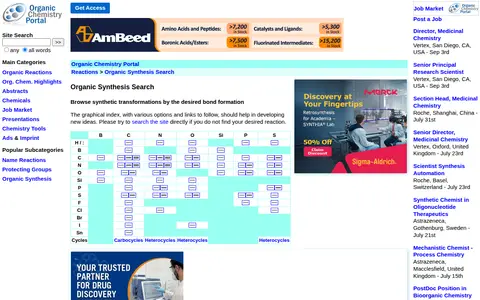
A page on the Organic Chemistry Portal that lets users browse synthetic transformations by desired bond formation through a graphical index with links. It also explains target-oriented synthesis, which develops a short high-yielding route to a specific molecule via retrosynthesis, and diversity-oriented synthesis, which builds libraries of varied compounds for screening.
DataLB
Long Beach public GeoSpatial & Open Data Portal.
Links
Tags
-
0A page on the Organic Chemistry Portal that lets users browse synthetic transformations by desired bond formation through a graphical index with links. It also explains target-oriented synthesis, which develops a short high-yielding route to a specific molecule via retrosynthesis, and diversity-oriented synthesis, which builds libraries of varied compounds for screening.
-
0Find and access engineering research data, with indexed datasets.
-
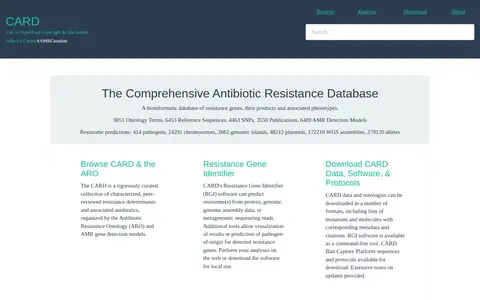
0The Comprehensive Antibiotic Resistance Database is a curated bioinformatic collection of resistance genes, their products and associated phenotypes, organized by the Antibiotic Resistance Ontology and AMR gene detection models. Its Resistance Gene Identifier software predicts resistomes from protein, genome, genome assembly or metagenomic sequencing read data, usable on the web or downloaded for local use. Data and ontologies are downloadable in several formats.
-
0The R. L. Kurucz atomic linelist is hosted among databases maintained at the CfA. The source describes it as data from Kurucz CD-ROM 18 and 23, with links to CD-ROM 23, the CfA AMP Server and CD-ROM 18. Other Kurucz data are maintained separately by R. L. Kurucz.
-
0The Korea Sequence Read Archive (KRA) is a publicly available repository of high throughput sequencing data. It stores qualified raw sequencing data and alignment information and facilitates reproducibility through a cloud-based data analysis service. The site states it is in English only, and news notes restrictions on duplicate data submissions and data brokering to the DDBJ Sequence Read Archive.
-
0PlaBi dataBase is a plant genomics portal focused on eight crop plants and Arabidopsis thaliana. It provides protein, cDNA and genomic sequences for protein-coding genes, PFAM conserved domains, a JBrowser genome browser for some plants, and orthologous protein search based on MCL clustering.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review