The Penn State Data Commons is an institutional repository for data sharing, discovery, and archiving at Penn State. It offers web-based visualization tools for finding data, lists recently added data, outlines steps for sharing data, and provides access to datasets from state, local, and federal agencies.
Bigelow National Center for Algae and Microbiota
The NCMA at Bigelow Laboratory maintains a public collection of marine algae and offers culturing of algae, bacteria, viruses, growth medium and seawater, deposits and ordering by location. It provides search by Tree of Life alignments, collection statistics, and an interactive mapserver for choosing strains by isolation location.
Uses
- Search public collection based upon alignments to the Tree of Life Source: ncma.bigelow.org
Pricing details
- $210 for domestic (US) non-profit institutions Source: ncma.bigelow.org
Links
Tags
-
0The Penn State Data Commons is an institutional repository for data sharing, discovery, and archiving at Penn State. It offers web-based visualization tools for finding data, lists recently added data, outlines steps for sharing data, and provides access to datasets from state, local, and federal agencies.
-
0Dataset repository covering agriculture, forestry and veterinary medicine, with searchable dataset.
-
0Research data portal for exploring empirical social records, including dataset.
-
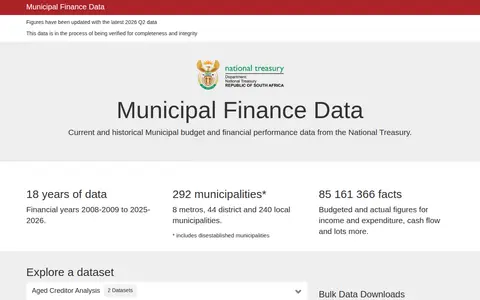
0Municipal Finance Data presents current and historical South African municipal budget and financial performance data from the National Treasury, covering financial years 2008-2009 to 2025-2026. It offers exploratory access to datasets, bulk data downloads, a JSON API, and the Municipal Money website.
-
0
The Virginia Open Data Portal is a state data catalog with featured datasets and popular tags. Datasets cover topics such as broadband application areas, EMS heat-related illness incidents, overdose emergency department visits and deaths, birth defects, and shared risk and protective factors. The portal also includes groups for economy, education, government, business, environment and natural resources, family and health, transportation, and geographic information.
-
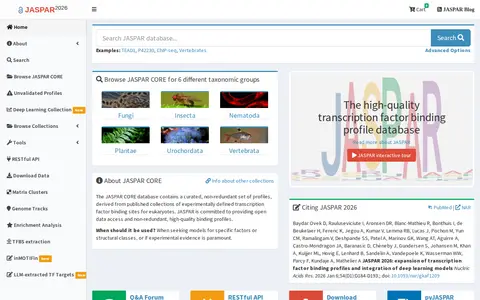
0JASPAR is an open-access database of curated, non-redundant transcription factor binding profiles from six taxonomic groups. It stores manually curated binding preferences as position frequency matrices that can be converted into models for scanning DNA sequences and predicting transcription factor binding sites. From 2026 it also stores deep learning models and discovered position frequency matrices linked to its PFM collections.
Community notes
Reviews and discussion
No reviews yet
Be the first to share how this project worked for you.
Join the discussion
Sign in with a verified account to leave a review or join the discussion.
Sign in to review