Web Scraping FYI is a knowledge base covering popular technology, concepts and techniques used in web scraping. Its sections address web scraping as a subject, a primer on how the modern web works, other tools and communities, and popular community libraries. Pages are designed to be self-sufficient and indexable.
Directory
Search results
Published directory entries matching your search.
A GitHub repository listing packages, services and manuals related to web scraping. It covers libraries for Python, PHP, Ruby, JavaScript and Go, command line tools, and web-scraping manuals. It also lists headless browsers, DNS over HTTPS providers, pastebin sites, tunneling software and captcha solving services.
Wget2 is an open source project with code, documentation, and setup resources for web archiving and scraping.
Heidelberg University Publishing (heiUP) uses Anubis anti-bot software that employs a proof-of-work challenge to block aggressive AI website scraping. The system is designed to reduce server downtime caused by mass scraping activity, and presents a verification page to users before granting access to site content.
The HHU ResearchData website displays an Anubis bot verification page that uses a proof-of-work challenge to block automated scraping. This placeholder solution, set up by the site administrator to protect server resources from aggressive scraping while more permanent detection methods are developed, can cause temporary downtime that renders the site's resources inaccessible for all users.
pagodo (Passive Google Dork) is a Python security tool that automates scraping of the Google Hacking Database and subsequent Google searches to identify potentially vulnerable web pages and applications. It replaces manual Google dork searches, consists of a dork retrieval component and a search execution component, uses the yagooglesearch library, and supports native HTTP(S) and SOCKS5 proxy support. Scraping Google Search results may violate Google's Terms of Service.
80legs offers customizable web scraping, including custom web crawling run on a cloud-enabled platform and a Giant Web Crawl product that pulls custom data from a crawl of the entire web. It also points to Datafiniti for instant access to web data.
SearchTweaks is a website offering tools to improve web search experiences, specifically enhancing Google search functionality. Its tools are organized into four categories: Query Builders, News-Related Search, Time-Related Search and Search Utilities. Some tools simplify existing Google features, while others add new search capabilities. The site requires JavaScript to function, is designed for desktop use, and does not rely on the Google API or web scraping. It uses Simple Analytics for privacy-focused usage tracking.
Data Hoarding is an index of resources and archives related to data hoarding, web archival and digital preservation. It provides a list of resources for getting started, helping archival teams, or backing up web content for personal use, with entries like Archive Team, ArchiveBox, Archivematica and ArchivesSpace.
A simple web scraper powered by Cloudflare Workers, built by Adam Schwartz. Users provide a URL and CSS selector, and the tool returns JSON containing the text contents of matching webpage elements. The project is open-source and available on GitHub.
Ui.Vision RPA is an open-source browser and desktop automation tool for building reusable macros. It offers web automation, desktop automation, web scraping, UI testing and test automation, using visual recording, Selenium-style commands or a JavaScript API. The V10 release adds an AI macro assistant and an MCP bridge for connecting AI assistants. The browser extension is available for Chrome, Edge and Firefox.
Firecrawl is a web data API designed for AI agents. It allows searching and scraping web content, returning data in formats such as JSON and Markdown. The service also provides access to Alexandria’s providers and specialized indexes. Firecrawl is open source, used by over 150,000 companies, and announced a $75 million Series B funding round.
Hyperbrowser offers cloud browsers, isolated sandboxes and web data APIs for AI agents. It provides Chrome sessions and microVMs that can be launched in one call and connected to Playwright, Puppeteer or an agent. The documentation describes automating websites, running code in isolated environments and scraping web data.
Import.io is a web data extraction and AI infrastructure platform. It converts website content into structured data, and provides web scraping tools, managed data services, pricing intelligence, and MCP tools for AI agents. It supports use cases across multiple industries including retail, ecommerce and AI development.
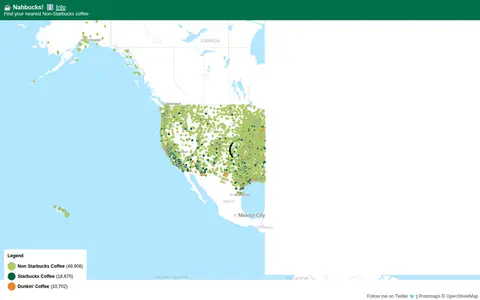
Nahbucks! shows the nearest non-Starbucks coffee shop. It states that coffee shop data was extracted from Google Maps by scraping businesses with categories such as coffee shops, coffee roasters, coffee wholesaler, coffee store and coffee stand. The page includes an affiliate link for Lifeboost Coffee.
SpiderSuite is a web crawling and security testing platform for security professionals, penetration testers and researchers. It offers specialized crawlers, traffic interception, request crafting and fuzzing, along with source and graph views of crawl data, plus import and export in formats such as HAR, WARC, CSV and JSON.
Python tool for collecting email addresses from search engines and public web sources during authorized research.
Arch Tools provides one API key for 63 tools aimed at AI agents and developers, covering web search, scraping, AI generation, OCR, transcription, crypto data, email and utilities. It supports REST and MCP protocols and offers two authentication methods: an API key or per-call x402 crypto payments in USDC on Base.
Browserflow is a browser-based tool for scraping websites and automating tasks on any website without coding. It offers a visual editor, action recording and custom JavaScript, and flows can run locally in the browser or be deployed to the cloud with scheduling and Google Sheets integration.
brozzler is an open source project with code, documentation, and setup resources for web archiving and scraping.
CopySite helps crawl, scrape, copy, or extract data and pages from websites.
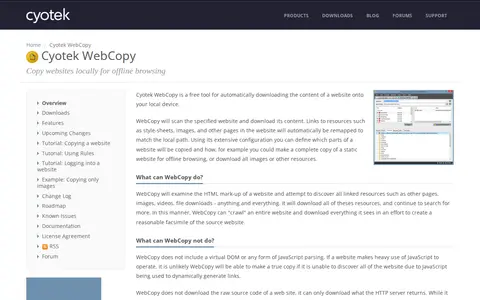
Cyotek WebCopy is a free Windows tool that scans a specified website and downloads its content for local offline browsing. It follows links to pages, images, videos and other resources, remapping them to local paths. Configuration includes rules, form and password authentication, and reports. It does not include a virtual DOM or JavaScript parsing, so JavaScript-heavy sites may not copy accurately.
datahoarder-website-to-markdown is an open source project with code, documentation, and setup resources for web archiving and scraping.
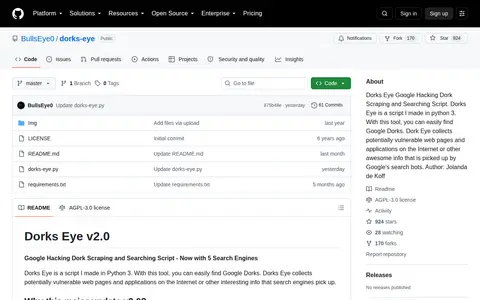
Dorks Eye Google Hacking Dork Scraping and Searching Script. Dorks Eye is a script I made in python 3. With this tool, you can easily find Google Dorks. Dork Eye collects potentially vulnerable web pages and applications on the Internet or other awesome info that is picked up by Google's search bots. Author: Jolanda de Koff