
trainchinese.com
Train Chinese provides educational videos, lessons, tutorials, or self-learning resources.
Directory
Published directory entries matching your search.
Train Chinese provides educational videos, lessons, tutorials, or self-learning resources.
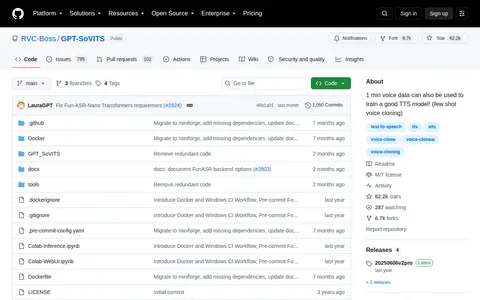
GPT-SoVITS is a few-shot voice conversion and text-to-speech WebUI. It supports zero-shot TTS from a five-second vocal sample and fine-tuning with one minute of training data. Cross-lingual inference covers English, Japanese, Korean, Cantonese and Chinese. Integrated WebUI tools include voice accompaniment separation, training set segmentation, Chinese ASR and text labeling.
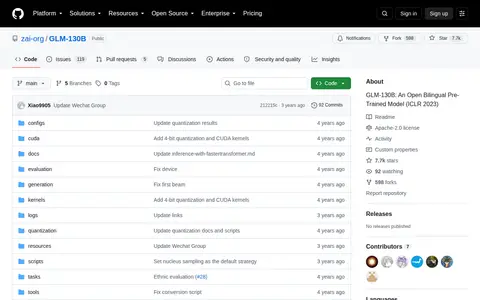
GLM-130B is an open bilingual pre-trained model with 130 billion parameters, pre-trained using the General Language Model algorithm. It was trained on over 400 billion text tokens, half Chinese and half English. With INT4 quantization, hardware requirements can be reduced to a single server with 4 RTX 3090 (24G) GPUs with almost no performance degradation.
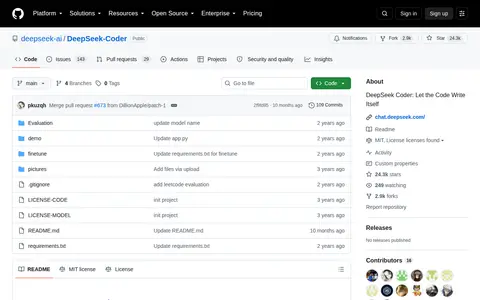
DeepSeek Coder is a series of open code language models trained from scratch on 2T tokens, composed of 87% code and 13% natural language in English and Chinese. Models are offered in 1B, 5.7B, 6.7B and 33B sizes, pre-trained on project-level code corpora with a 16K window size and a fill-in-the-blank task for completion and infilling.
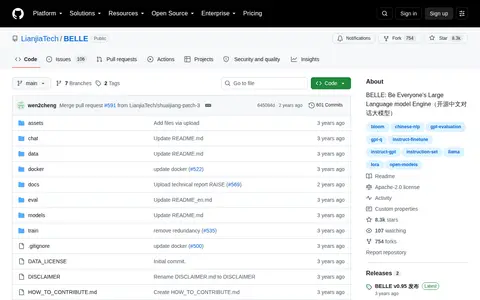
BELLE, short for Be Everyone's Large Language model Engine, is an open-source Chinese conversational large language model hosted on GitHub by LianjiaTech. The project provides relevant training code and open datasets for the model.
Benha University is a university portal presenting news on research, international cooperation and institutional agreements. It reports collaborations with Chinese universities and a cooperation protocol with a water resources training center.
pkuseg is a Python toolkit for multi-domain Chinese word segmentation, based on a 2019 paper. It provides pretrained models for news, web, medicine, tourism, and mixed domains, and supports user-trained models and part-of-speech tagging. It is distributed under the MIT license.
ZPar is an open-source statistical parser hosted on GitHub. It offers universal language support contingent on the availability of training data, with dedicated language-specific features for Chinese and English. The tool supports word segmentation, part-of-speech tagging, dependency parsing, and phrase-structure parsing.