go-ml-benchmarks is a repository of machine learning inference benchmarks for Go, focused on tabular models such as XGBoost. It compares typical implementations using different transports, encodings, preprocessing libraries and models, using the Titanic dataset. The repository was archived by the owner and is now read-only.
Directory
Search results
Published directory entries matching your search.
Chunk Tuner is a tool that benchmarks chunking strategies for a RAG corpus and recommends a configuration. It benchmarks strategies such as fixed-token windows, recursive character splitting, semantic splitting and PDF structural chunking, scoring each against retrieval metrics. It is available as a Python library, a CLI and an MCP server.
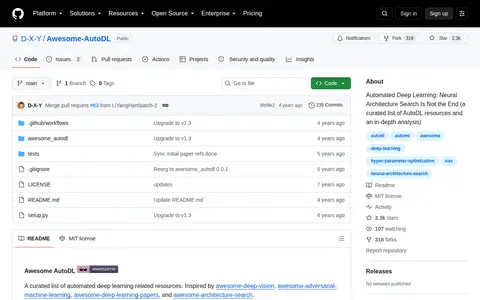
Awesome AutoDL is a curated list of automated deep learning resources and an in-depth analysis, subtitled that neural architecture search is not the end. It collects papers, libraries and benchmarks covering neural architecture search and hyper-parameter optimization.
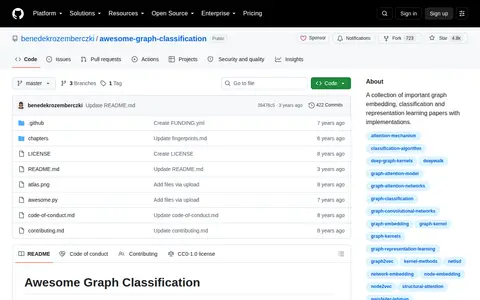
A GitHub collection of graph classification papers with reference implementations, covering embedding, deep learning, graph kernel and factorization methods. It also links to graph classification benchmark datasets and similar curated collections.
Curated list of top Hugging Face models for NLP, vision, and audio tasks with demos and benchmarks.
Curated list of free and open-source MySQL software, libraries, tools and resources. The README organizes entries into categories such as Analysis, Backup, Benchmarking, Binlog Replication, Connectors, GUI and Replication, and the list accepts and encourages pull requests.
GPT Migrate team is working on adding for the agent.
CodeGeeX is an open multilingual code generation model with 13 billion parameters, pre-trained on a code corpus of more than 20 programming languages. It supports multilingual code generation, crosslingual code translation and a VS Code extension, and the repository also releases the HumanEval-X benchmark.
DeepSWE is a GitHub repository that provides a benchmark for measuring the performance of frontier coding AI agents on original, long-horizon engineering tasks. The repository includes documentation on task format, quickstart guides, and details about supported agents and models.
Detectron2 is Facebook AI Research's next generation library providing detection and segmentation algorithms, succeeding Detectron and maskrcnn-benchmark. It supports computer vision research projects and production applications at Facebook and includes capabilities such as panoptic segmentation, Densepose, Cascade R-CNN, rotated bounding boxes, PointRend, DeepLab, ViTDet and MViTv2. Models can be exported to TorchScript or Caffe2 format for deployment.
EQ-Bench 3 is a multi-turn emotional intelligence benchmark for language models. It presents role-play scenarios and analysis tasks requiring empathy, insight and social skill, and an auxiliary judge model scores or pairwise-compares the outputs. An MIT-licensed repository with a readme, results and data folders, it includes rubric scoring and pairwise ELO analysis options.
BIG-bench is a collaborative benchmark intended to probe large language models and extrapolate their future capabilities. It includes more than 200 tasks, summarized by keyword and task name. The repository was archived by its owner and is now read-only.
Gym4ReaL is an open-source GitHub repository maintained by Daveonwave. It is a Gymnasium-based benchmarking suite for testing reinforcement learning algorithms on real-world scenarios. The repository includes documentation on supported characteristics, reinforcement learning paradigms, folder structure, contribution guidelines, and licensing terms.
Honey (I Shrunk the AI) by GreenPT is a cross-tool coding skill that reduces AI coding-agent token usage and LLM API costs. It enables writing less code and prose and supports denser agent-to-agent handoffs, with reported 53% cost reduction and no quality loss in benchmarks. It is compatible with Claude Code, Cursor, GitHub Copilot, Codex, Gemini CLI, Windsurf, Cline, and Kiro.
Library for hyperparameter optimization and black box optimization benchmarks.
Local Deep Research is a tool that achieves approximately 95% accuracy on the SimpleQA benchmark, with an example run using Qwen3.6-27B on an RTX 3090. It supports all local and cloud LLMs including llama.cpp, Ollama, and Google models, integrates over 10 search engines such as arXiv, PubMed, and private document sources, and operates with local and encrypted processing.
An open source robotics benchmark for meta- and multi-task reinforcement learning.
nanoBench is a Linux-based tool for running small microbenchmarks on recent Intel and AMD x86 CPUs, evaluated with hardware performance counters. It offers a user-space variant and a kernel module; the kernel module permits benchmarking privileged instructions and using uncore counters, but should not be used on a production system.
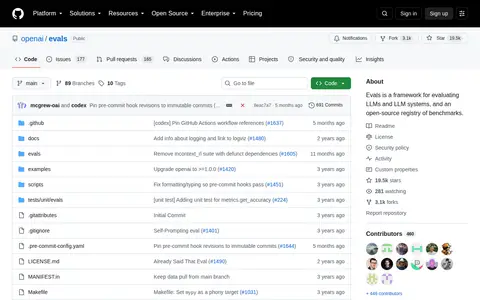
Evals is a framework for evaluating large language models and systems built using LLMs. It offers an existing registry of evals to test different dimensions of OpenAI models and the ability to write custom evals. It is available as an open-source registry of benchmarks. Evals require an OpenAI API key.
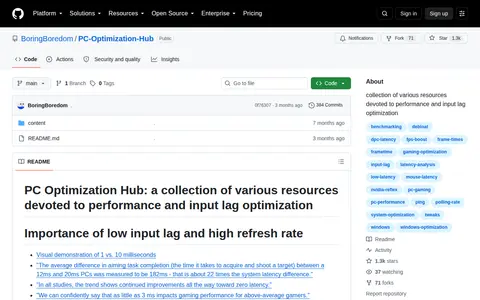
PC-Optimization-Hub is a GitHub repository collecting various resources devoted to performance and input lag optimization. It covers topics including benchmarking, debloat, DPC latency, frame times, polling rates and Windows optimization, and includes sections on data collection and physical setup.
PyTorch Geometric Temporal is a temporal extension library for PyTorch Geometric. It contains dynamic and temporal geometric deep learning, embedding and spatio-temporal regression methods from published research papers. It includes a dataset loader, train-test splitter and temporal snapshot iterator for dynamic and temporal graphs, with GPU support and benchmark datasets.
LLMeBench is a flexible framework for accelerating the benchmarking of large language models. It provides tools to run benchmarks and evaluate model performance. The project is hosted on GitHub under the qcri organization.
CLI tool for debugging and benchmarking RAG retrieval. EXPLAIN ANALYZE for your retrieval layer.
WhisperS2T is an optimized speech-to-text pipeline for the Whisper model that supports multiple inference engines. The repository provides release notes, quickstart guides, future roadmaps, and a benchmark and technical report.