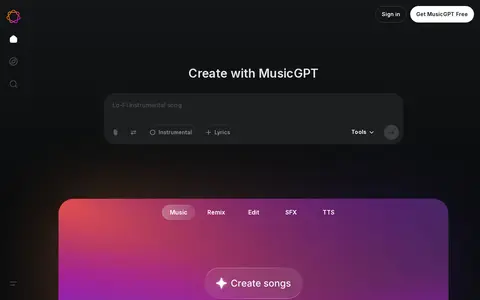
MusicGPT is an AI music generator and song maker. It creates original songs, beats, instrumentals and sound effects, and offers editing tools to split stems, change voices and enhance audio. The site lists Plus, Pro and Ultra plans, with a free start and upgrades for more minutes and commercial use.
Directory
Search results
Published directory entries matching your search.
OpenVINO AI Plugins for Audacity is a set of AI-enabled effects, generators and analyzers for Audacity. The features run locally on the PC without an internet connection, using OpenVINO to run AI models on the system's CPU, GPU or NPU. Included tools cover music separation, noise suppression, MusicGen-based music generation and continuation, Whisper transcription and audio super resolution.
Paper2GUI is an AI desktop application toolbox that is free and ready to use out of the box. It supports more than 10 AI models covering speech synthesis, video frame filling, video overscoring, target detection, image stylization and OCR recognition, on Windows, Mac OS and Linux.
python-frog is an open-source Python library hosted on GitHub providing bindings to the Dutch NLP tool Frog, which supports part-of-speech tagging, lemmatisation, named entity recognition, morphological analysis, shallow parsing and dependency parsing.
Readwise Reader is a read-it-later app that saves articles, newsletters, RSS feeds, PDFs, EPUBs, YouTube videos and Twitter threads in one place. It offers web highlighting and annotation through a browser extension and integrates with the Readwise app, which resurfaces highlights via Daily Review and exports them to note-taking tools.
Retrieval-based-Voice-Conversion-WebUI is a project for training voice conversion models from voice data, with an easy-to-use WebUI. It includes a pymss/MSST model to separate vocals and instruments and a high-pitch voice extraction algorithm to prevent a muted sound problem. Dependencies differ by hardware, including CPU, AMD, Intel and NVIDIA GPU setups.
SOUNDRAW is an AI music generator that lets users create royalty-free beats in seconds. It supports genre blending, instrument customization, stem downloads, and music monetization. Its AI is trained exclusively on in-house created music, with no use of scraped content, to ensure copyright-safe outputs for creators and artists.
spaCy is a free open-source library for Natural Language Processing in Python. It features named entity recognition, part-of-speech tagging, dependency parsing and word vectors, supports over 75 languages and provides 84 trained pipelines for 25 languages.
Suno is an AI music generator that creates original music from user prompts. It offers a browser-based digital audio workstation for editing and mixing tracks, voice cloning to make any voice sing user-written content, stem separation to split songs into individual components, and remix functionality.
Treat is a natural language processing and computational linguistics toolkit for Ruby. It covers document retrieval, text chunking, segmentation, tokenization, parsing, part-of-speech tagging, keyword extraction and named entity recognition. The README states the gem is unmaintained.
Treblo, formerly Sonauto, is a free AI music generator that turns ideas into songs with lyrics, vocals and thousands of styles. It offers unlimited songs, editing, covers and remixes, and is available on iOS and Android.
VideoLingo combines speech recognition, subtitle translation, segmentation and dubbing in a Streamlit interface. It produces subtitle files and optionally subtitled or dubbed videos, and supports input languages including English, Russian, French, German, Italian, Spanish, Japanese and Chinese.
Vocali.se is a free web service that separates vocals and music from songs or audio files, allowing users to create karaoke versions. It runs a machine learning engine using pre-trained Demucs models and requires no software installation or account registration. Processing takes less than three minutes, after which the separated files download automatically.
VocalRemover is a free online application that separates a song into a karaoke version without vocals and an acapella version with isolated vocals. It uses artificial intelligence algorithms and processing usually takes about 10 seconds.
VCClient is software that performs real-time voice conversion using AI. It supports several AI models and offers both standalone use on a local PC and voice conversion over a network, and it provides a REST API. Editions support different models, and Windows and M1 Mac versions can be downloaded from a Hugging Face repository.
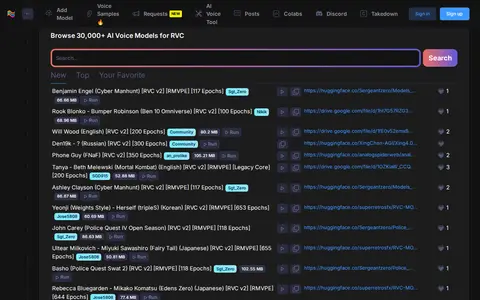
A site for browsing AI voice models for RVC. It lists 30,000+ voice models covering characters, singers and creators, allows previewing samples, and supports running compatible voices online with EasyAIVoice.
G4F Chat is a conversational AI platform that supports private, customizable conversations using multiple AI providers and models. It includes features such as cloud sync, conversation export, markdown rendering, speech recognition, voice synthesis, custom system prompt configuration and MCP server support.
Whisper is a robust speech recognition system developed by OpenAI, hosted on GitHub. It uses large-scale weak supervision for training, and the repository includes documentation on its approach, setup, available models and supported languages, plus command-line usage instructions.