A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
Directory
Search results
Published directory entries matching your search.
Whisper command line client compatible with the original OpenAI client and based on CTranslate2. It uses CTranslate2 and the Faster-whisper implementation. The project lists Docker images with pre-loaded models, speaker diarization, voice activity detection and live transcription from a microphone. It is installed as a Python package or run from a Docker image.
WolframTones uses AI for speech, voice, transcription, music, or other audio workflows.
Zenmic.com is an AI audio generation tool that converts text, documents, URLs or topics into natural-sounding audio. It is targeted at ESL teachers, learning and development teams, and podcast creators, and offers features including full script control, over 30 voices, MP3 export, support for 125 languages, up to six speaker tracks, and voice cloning. Users can start using the tool for free without a credit card.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Zyphra uses AI for speech, voice, transcription, music, or other audio workflows.
Radio Scanner Text Feeds is an open-source website that transcribes live radio scanner audio into text in real time. Audio streams are split on voice activity, transcribed with speech recognition, and published to web feeds. Visitors can read the live text, listen to the audio, suggest alternate text, and vote on the text. Audio is sourced from Broadcastify.
AIVA is an AI music generation assistant that creates new songs in more than 250 styles within seconds. Users can build style models, upload audio or MIDI influence, and edit generated tracks. A free plan offers non-commercial use with credit to AIVA and three downloads per month.
Open ASR Leaderboard is a Hugging Face Space that provides a searchable leaderboard of speech-recognition models. It displays word-error rates, real-time factors and model sizes across many languages and datasets, and users can select which entries to view.
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.
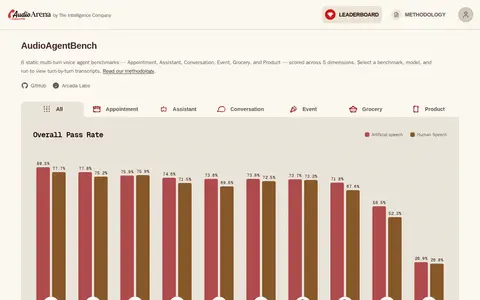
AudioArena is a site for benchmarking and comparing voice models through real conversations. It offers AudioAgentBench, a set of six static multi-turn voice agent benchmarks, scored across five dimensions, and lets users select a benchmark, model, and run to view turn-by-turn transcripts.
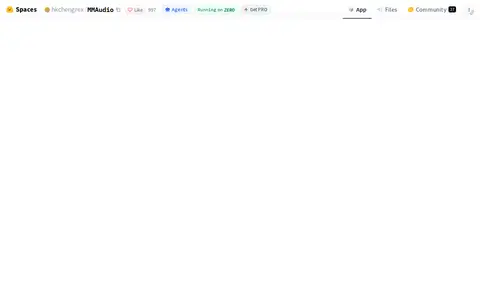
MMAudio is a Hugging Face Space that generates synchronized audio from video or text. Users can upload a short video and write a prompt, including a negative prompt, to add realistic sound, or create a standalone audio clip from a text description.
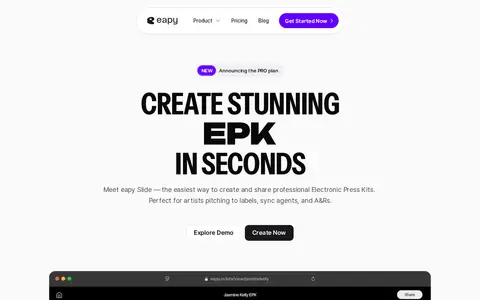
Eapy Slide is a tool for creating professional Electronic Press Kits (EPKs) for music artists. Users upload music, images, and text to generate formatted, shareable EPKs to pitch to labels, sync agents, and A&R representatives.
A Hugging Face Space that turns an ebook file or pasted text into a complete audiobook. The user selects a language, voice and audio format, then generates audio to listen to or download; sections can also be previewed and edited. The page states support for 1107+ languages.
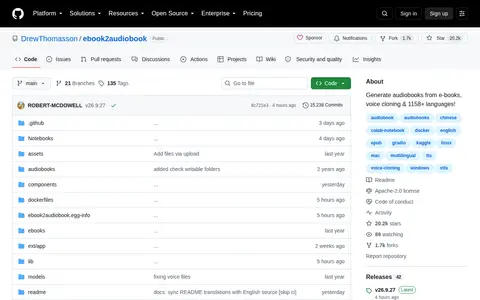
Ebook2Audiobook is an open-source GitHub repository created by DrewThomasson that generates audiobooks from e-books, supports voice cloning, and is compatible with 1158 or more languages. The tool can be run locally or remotely.
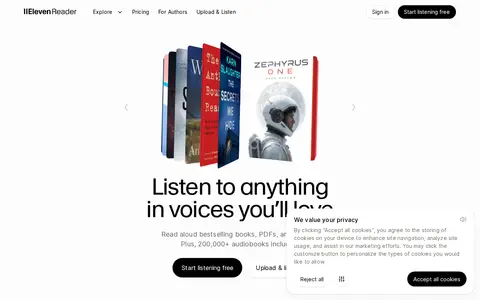
ElevenReader is a free text read-aloud application. It can read aloud PDFs, eBooks, Kindle content and web articles, provides access to over 200,000 audiobooks, and offers 1000+ natural-sounding voices in 90+ languages, supporting file upload and link input for reading.
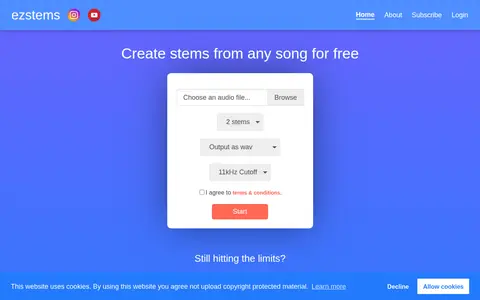
Ezstems is a website that uses Spleeter, a tool that creates stems from any audio file. Users upload an audio file and the resulting stems download in seconds. Free use is subject to limits, with a stated cap of 20 uploads per day and a 20MB file size limit.
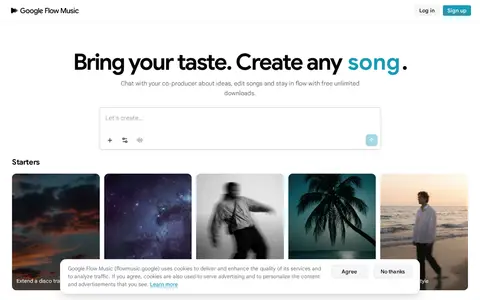
Google Flow Music is a generative AI platform for creating, remixing, and sharing songs. It includes a chat with Producer, AI music video, and tools to build audio plugins, music games, and custom DAWs. It is free to start without a credit card.
HelloChinese is an app for beginners to learn Mandarin Chinese, described as using interactive game-based learning. It covers reading, writing, speaking, vocabulary and grammar, with speech recognition, handwriting practice, native speaker videos and a spaced repetition system. It is available on Google Play and the App Store.
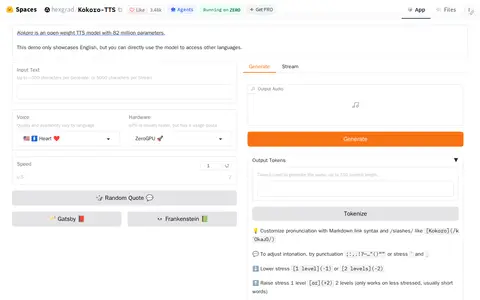
Kokoro TTS is a Hugging Face Space developed by hexgrad that converts input English text to spoken audio. Users can select a voice and speaking speed, and choose to download the generated audio or listen to a live streaming version.
Mazmazika is an online music tool platform that integrates multiple music-related functions. Its tools include vocal remover, chord analyzer, ear training, beat maker, sheet music editor, piano, metronome, audio and MIDI piano visualizer, and chord library, with free basic use available in the browser.
MMAudio is a research project on multimodal joint training for video-to-audio synthesis. It generates synchronized audio given video and/or text inputs. The work is presented at CVPR 2025 by authors from the University of Illinois Urbana-Champaign and Sony.
Mubert is an AI music generator offering royalty-free music from text prompts. It provides Render for content creators, Studio for contributing samples and loops, API for developers, and Play for listeners. The API supports track generation and music streaming integration.
MusicGen is a single-stage auto-regressive Transformer model for music generation trained over a 32kHz EnCodec tokenizer with four codebooks, part of the AudioCraft library. It supports text-to-music and text-plus-melody-to-music models ranging from 300M to 3.3B parameters. Running it locally requires a GPU, with at least 16 GB of memory recommended for medium-sized models.