
ebooksbrasil.org
eBooksBrasil is a non-English reading, font, dictionary, or language-learning resource.
Directory
Published directory entries matching your search.
eBooksBrasil is a non-English reading, font, dictionary, or language-learning resource.

Facebook is a non-English reading, font, dictionary, or language-learning resource.

Facebook is a non-English reading, font, dictionary, or language-learning resource.

Facebook is a non-English reading, font, dictionary, or language-learning resource.
FoLiA is an XML-based format for linguistic annotation intended for representing and exchanging written language resources such as corpora. It aims to accommodate many annotation types through a generalized paradigm without committing to a particular label set, language or linguistic theory. The project includes documentation, a RelaxNG schema and software libraries.
FoulaBook is a non-English reading, font, dictionary, or language-learning resource.

Honto is a non-English reading, font, dictionary, or language-learning resource.
A blog guide on FinetuneDB covering best practices for evaluating Large Language Model outputs. It explains what LLM output evaluation is, why it matters, and describes evaluation datasets, model-based judgments and human judgments as approaches for structuring the process.
IndianSignLanguage is a non-English reading, font, dictionary, or language-learning resource.
IndonesiaEbook is a non-English reading, font, dictionary, or language-learning resource.

J2team is a non-English reading, font, dictionary, or language-learning resource.

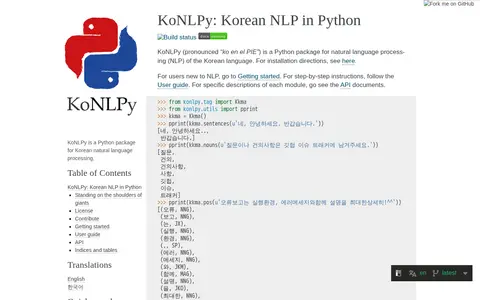
KoNLPy (pronounced "ko en el PIE") is a Python package for natural language processing of the Korean language. It is open source software released under GPL v3 or above, and users are asked to acknowledge its use with a citation.
Julia package for working with various human languages.

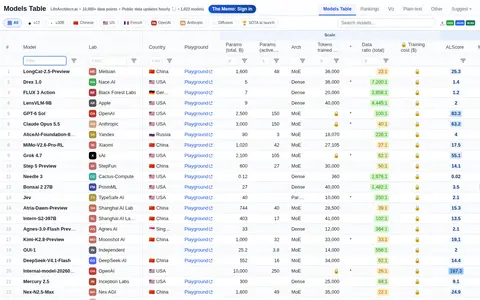
LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
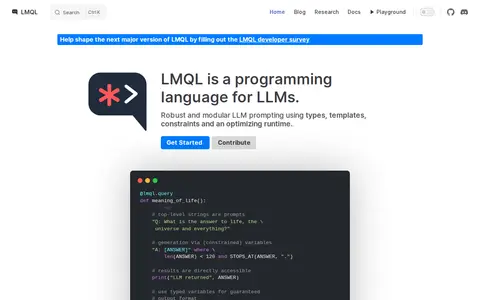
LMQL is a programming language for interacting with large language models, using types, templates, constraints and an optimizing runtime. Prompt statements have associated where clauses that specify logical constraints on output, which LMQL translates to subtoken masks enforced during generation. It works across llama.cpp, OpenAI and Transformers backends and supports nested queries.
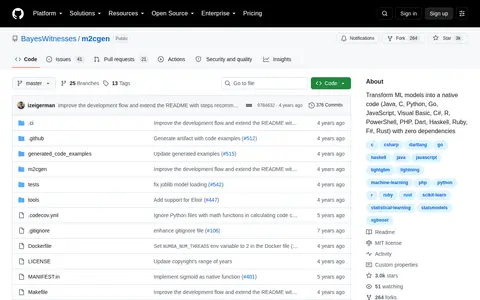
m2cgen is a tool that transforms trained machine learning models into native code across a wide range of programming languages including Java, C, Python, Go, JavaScript, C#, R, PHP, Dart, Haskell, Ruby, F#, and Rust, with zero dependencies. Its codebase is hosted in the BayesWitnesses GitHub repository, which includes navigation for installation, development guidance, supported languages, and supported model types.
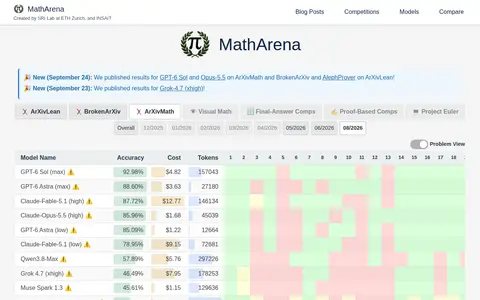
MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.

mp3-book is a non-English reading, font, dictionary, or language-learning resource.

Native Land is a resource and app for learning about Indigenous territories, languages, lands, and ways of life, and for mapping Indigenous territories, treaties, and languages. It also states that its maps are not official sources. The site notes it provides geoJSONs and an API for free.
Noor Book is a non-English reading, font, dictionary, or language-learning resource.

nunubook.com is a non-English reading, font, dictionary, or language-learning resource.
Odysseus is a self-hosted AI workspace for running language models on one's own hardware. It offers chat, autonomous agents, tools and MCP connections, model serving, an email assistant, deep research, model comparison and persistent memory. The project is described as local-first and privacy-first, with no telemetry.

PDF Books is a non-English reading, font, dictionary, or language-learning resource.
This is the official project page for the ICML 2024 research paper 'Improving Factuality and Reasoning in Language Models through Multiagent Debate' by MIT and Google Brain researchers. The paper introduces a multi-round debate approach where multiple language model instances propose answers, critique each other, and debate to improve reasoning and factual accuracy while reducing hallucinations.