github.com
Works with speech, voice, music or other audio using machine-learning models.
Directory
Published directory entries matching your search.
Works with speech, voice, music or other audio using machine-learning models.
Transgate is an AI transcription and translation service for audio and video. It offers two services: transcribe or translate in 50+ languages, with summaries, highlights and the ability to chat with transcripts. Files are uploaded, processed by AI, and results can be exported. It uses a pay-as-you-go model.
This Hugging Face Space by k2-fsa is a text-to-speech application that converts user-entered text to spoken audio. Users can select a language or model, and may upload or record a short reference audio clip to generate speech in a specific person's voice.
Works with speech, voice, music or other audio using machine-learning models.
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
Tunisian Speech Recognition is a Hugging Face Space created by SalahZa. The application transcribes spoken Tunisian Arabic into text using Arabic characters. Users can provide input audio either by recording through a microphone or uploading an audio file, and the tool returns the corresponding text transcription.
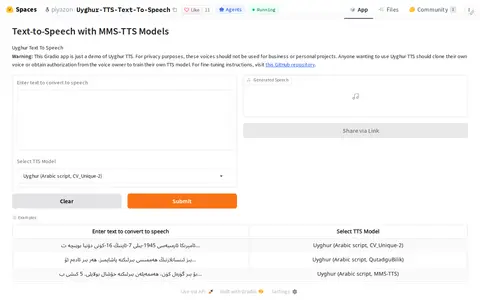
Uyghur TTS Text To Speech is a Hugging Face Space developed by piyazon. The application allows users to input Uyghur text, including numbers, Chinese characters and punctuation, select a Uyghur text-to-speech voice, and convert the typed text into natural-sounding Uyghur speech audio.
Accelerates transcription with the combination of OpenAI's Whisper Large v2, HF Transformers, Optimum, and flash attention.
Space emoji (emoji-only character allowed).

Veed.io is an AI video creation platform that offers an end-to-end idea-to-video workflow. It provides tools for generating talking heads, AI-powered video editing, dubbing, subtitle addition, AI voice and image generation, and pre-built ad and video templates, targeted at marketers and solopreneurs.
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.

Voctro Labs is a Barcelona-based company founded in 2011 that develops AI-based voice, music and audio technologies for creative companies and individuals. Its products include Voiceful, a toolkit for speech and singing voice experiences with a cloud-based API and SDK libraries, and Virtual Singers for Yamaha's VOCALOID software. Services include personalized voices and customized algorithms.
Voice Dream Reader is a text-to-speech app that reads PDFs, web pages, and books aloud. It supports importing PDFs, EPUBs, Word documents, PowerPoint files, and web pages, with highlighting, notes, offline listening, and syncing across iPhone, iPad, and Mac. Accessibility features include VoiceOver support, Dynamic Type, Voice Control, and braille display support.
Voice-Swap is an AI voice platform for musicians, content creators, and artists. It offers a text-to-speech voiceover studio, a singing studio for voice swapping and stem separation, and custom voice model training. The site states that voice modelling, generation and rights management are combined into a single system.
Voicery is a company that creates natural-sounding text-to-speech engines and custom brand voices for enterprise clients. Its solutions leverage deep-learning research optimized for specific business use cases and technical infrastructure.
Voicesphere is an AI document interaction tool that allows users to upload documents including PDFs, DOCs, PPTs, videos, texts, and CSVs to ask natural language questions and receive context-specific answers. It includes a secure document management system, and is designed for use by manufacturing companies, medical professionals, law firms, researchers, recruitment agencies, and customer service teams.
voicetoinstrument.com is an AI audio conversion platform that transforms uploaded voice recordings, hummed melodies, or vocal tracks into realistic instrument sounds. It supports conversion to more than 100 instruments including piano, guitar, violin, saxophone, drums, and flute, and offers a free online converter alongside additional AI audio tools such as stem splitters and vocal removers.
Vosk is an offline speech recognition API hosted in the alphacep/vosk-api GitHub repository. It is compatible with Android, iOS, Raspberry Pi, and server environments, and provides SDKs for Python, Java, C#, and Node.
A simple and efficient end-to-end Automatic Speech Recognition (ASR) system from Facebook AI Research.
Works with speech, voice, music or other audio using machine-learning models.
USE BAZEL VERSION=5.0.0./bazelisk-linux-amd64 build wavegru mod -c opt --copt=-march=native.
Websim AI supports software development with code generation, analysis, debugging, or documentation.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.
WFGY is an open-source project focused on AI reasoning, retrieval-augmented generation, AI agents, and real-world workflows. It is developing the WFGY 5.0 Polaris Protocol, and currently includes components such as the Problem Map, Global Debug Card, 4.0 version, and CFV Easter Egg.