Resemble AI provides multimodal deepfake detection and watermarking for enterprise. It powers real-time detection of synthetic audio, video, and images, offers APIs, intelligence insights, and identity registration. It includes tools like meetings protection, agent detection, a Chrome extension, and integrates with Microsoft Teams. The company develops research models such as DETECT-World and PerTh Multimodal. It serves industries including telecom, finance, media, health, and public sector.
Directory
Search results
Published directory entries matching your search.
Rev AI, part of the Rev family, is a developer-first API that delivers industry- accuracy and fast performance at global scale. Click to learn more.
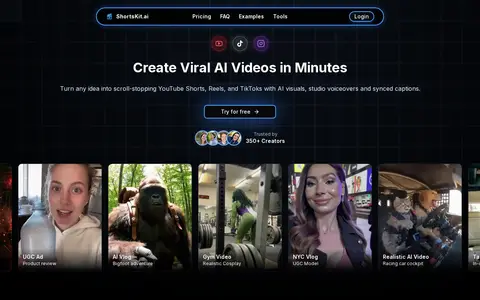
ShortsKit.ai is an AI video creation platform that turns text into short-form videos with AI visuals, voiceovers and synced captions for YouTube Shorts, TikTok and Instagram Reels. Users describe a video, generate and edit clips, then export. Plans are billed per month with credits: Hobby at $15/month, Pro at $39/month and Ultra at $159/month.
This premium domain name is available for purchase!
Soundful is an AI music platform for generating royalty-free tracks and loops. Users select a genre and template, with a human-aided AI producing unique tracks. Plans include Free, Plus, Pro, Business and Enterprise, with track downloads varying by plan.
SoundofText uses AI for speech, voice, transcription, music, or other audio workflows.
Speechma is an online text-to-speech converter that turns text into audio using a library of AI voices. The site states that no registration is required and that generated audio can be used commercially. A REST API for developers is also offered under a monthly subscription.
Splitter uses AI for speech, voice, transcription, music, or other audio workflows.
Stable Audio uses AI for speech, voice, transcription, music, or other audio workflows.
StemGen is an end-to-end music generation model trained to listen to musical context and respond appropriately. It is built on a non-autoregressive language-model type architecture similar to SoundStorm and VampNet, and is presented as examples for an ICASSP2024 paper.
Tortoise TTS is an open-source multi-voice text-to-speech system hosted on the GitHub repository neonbjb/tortoise-tts, trained with an emphasis on output quality. An associated Hugging Face space for the project is available for demonstration.
Transgate is an AI transcription and translation service for audio and video. It offers two services: transcribe or translate in 50+ languages, with summaries, highlights and the ability to chat with transcripts. Files are uploaded, processed by AI, and results can be exported. It uses a pay-as-you-go model.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
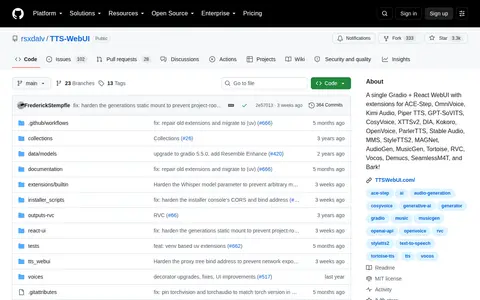
Tts Web UI is a single web interface built with Gradio and React that supports extensions for a wide range of audio and text-to-speech related models and tools, including ACE-Step, OmniVoice, Piper TTS, GPT-SoVITS, and others.
TTS WebUI is a free Gradio-based web interface for text-to-speech, audio and music generation. It can generate audio from text using over 30 AI models, including Bark, MusicGen, Tortoise and Vocos, and offers voices from the Bark Speaker Directory. Installation is available through one-click installers or manual setup.
Vocal Remover uses AI for speech, voice, transcription, music, or other audio workflows.
Accelerates transcription with the combination of OpenAI's Whisper Large v2, HF Transformers, Optimum, and flash attention.
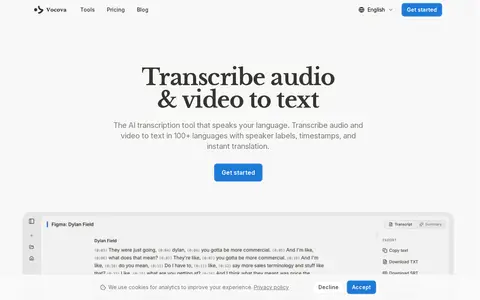
Vocova is an AI tool that transcribes audio and video to text in 100+ languages, with speaker labels, timestamps and translation. It imports from YouTube, Google Drive, Dropbox and other platforms, and exports transcripts as PDF, DOCX, SRT and more.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Voicesphere is an AI document interaction tool that allows users to upload documents including PDFs, DOCs, PPTs, videos, texts, and CSVs to ask natural language questions and receive context-specific answers. It includes a secure document management system, and is designed for use by manufacturing companies, medical professionals, law firms, researchers, recruitment agencies, and customer service teams.
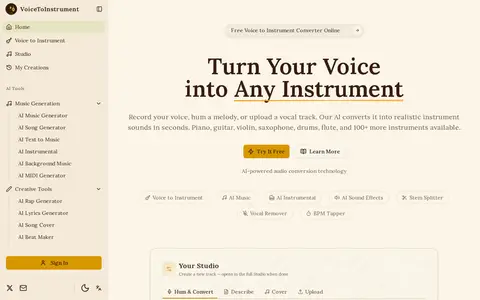
voicetoinstrument.com is an AI audio conversion platform that transforms uploaded voice recordings, hummed melodies, or vocal tracks into realistic instrument sounds. It supports conversion to more than 100 instruments including piano, guitar, violin, saxophone, drums, and flute, and offers a free online converter alongside additional AI audio tools such as stem splitters and vocal removers.
Voice to Text is a free online speech recognition tool that converts spoken words into text for writing emails, documents and essays without typing. It supports more than 30 languages, offers editing tools and transcript export, and can also convert text into speech and audio recordings into text.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.