AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.
Directory
Search results
Published directory entries matching your search.
AIVA is an AI music generation assistant that creates new songs in more than 250 styles within seconds. Users can build style models, upload audio or MIDI influence, and edit generated tracks. A free plan offers non-commercial use with credit to AIVA and three downloads per month.
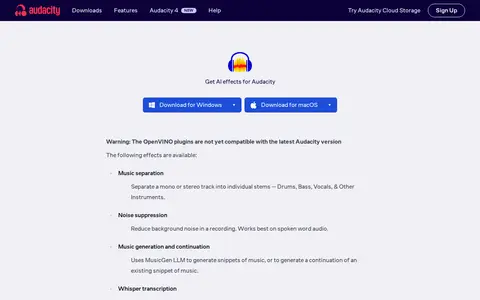
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.
AudioLDM is a text-to-audio system built on a latent space that learns continuous audio representations from CLAP latents. It generates text-conditional sound effects, human speech and music, and enables zero-shot text-guided audio style transfer, inpainting and super-resolution.
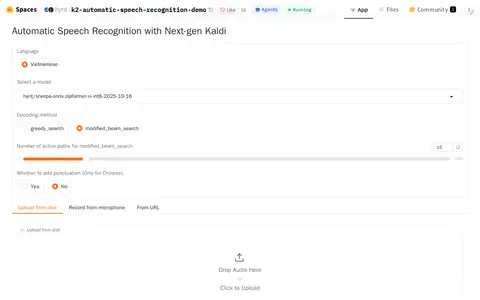
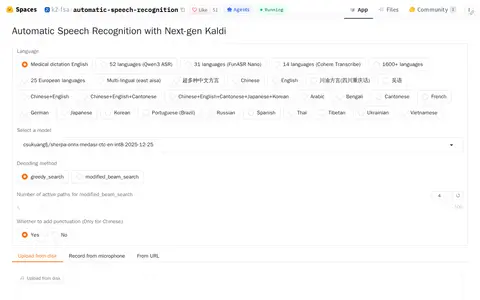
This Automatic Speech Recognition Hugging Face Space converts spoken audio to written text. Users can upload audio files, record from their microphone, or provide an audio URL, and select options including language, model, decoding method, and punctuation.
This Automatic Speech Recognition Hugging Face Space processes audio files, microphone recordings, or audio clips up to 40 seconds from a URL, and outputs the spoken content as written text.
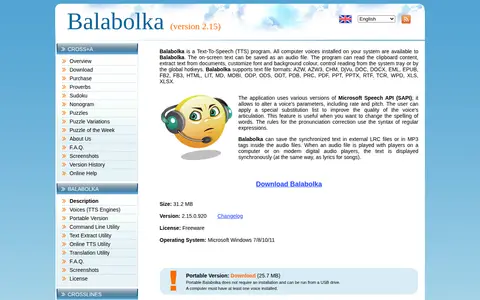
Balabolka is a freeware text-to-speech application that uses computer voices installed on the system. It can save on-screen text as an audio file, read clipboard content, extract text from documents, and save synchronized text in LRC files or MP3 tags.
Bespoke Sounds is a sonic identity studio that creates custom branded soundtracks for lifestyle, luxury, and boutique hospitality brands. The studio is run by a team of DJs, musicians, and audiophiles.
Boppy is a free AI music generator that creates full songs from a text description. It writes the lyrics and generates a complete track in under a minute, with no signup or credit card required. Tracks run up to 2 minutes, and the apps for iOS and Android add in-app Premium at US$5.99/month in the US.
Text-to-speech solutions with character.
CMUSphinx is an open source speech recognition system for mobile and server applications. It supports C, C++, C#, Python, Ruby, Java and JavaScript, and Unix, Windows, iOS, Android and hardware platforms. The related PocketSphinx 5.1.0 release adds Python 3.14 support and pre-built wheels for Linux/arm64.
Free speech-to-text tool for content creators that accurately transcribes audio & video files up to 2GB.
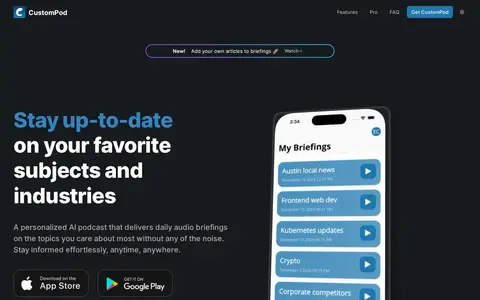
CustomPod is a personalized AI podcast service that delivers daily audio briefings on selected topics. It builds feeds from blogs, web searches, social media and personal content, and offers AI summaries, daily briefings and filtering. A free plan includes unlimited episodes and briefing sections, while a Pro plan at $4.99 per month adds automatic briefing generation and premium voices.
Dadabots describes itself as a band of music hackers using DIY neural nets and open source tools such as PyTorch and Ableton. Its featured works include 24/7 livestreams generating death metal and a neural technical death metal livestream.
Discover amazing ML apps made by the community.
DeepAI is a creative AI platform offering tools for image generation, photo editing, video, music, voice chat and AI chat, plus APIs for developers. It began in late 2016 with a browser-based text-to-image generator. A free tier is available, and DeepAI Pro costs $9.99 per month.
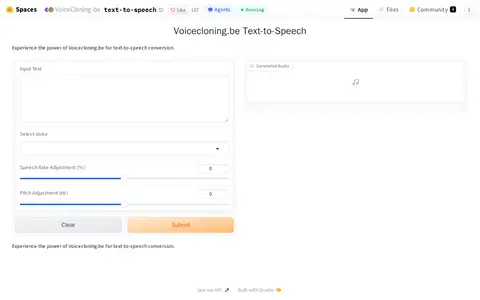
This is a duplicated instance of the Edge TTS Text To Speech Hugging Face Space, created by VoiceCloning-be. It offers the same text-to-speech functionality as the original, allowing users to input text, select voices, adjust speech rate and pitch, and generate customized audio output. The space is currently running.
Elai.io is an AI-powered tool that creates videos with customizable digital presenters from text. It offers a library of avatars, 75+ languages and voices, prompt-based video generation, voice cloning and presentation-to-video conversion. An integration uploads rendered videos directly to Thinkific courses.
EmotiVoice is an open-source text-to-speech engine that speaks English and Chinese with over 2000 voices. Its main feature is emotional synthesis across emotions such as happy, excited, sad and angry. It provides a web interface and a scripting interface for batch generation.
Endel is a mobile app that provides personalized soundscapes intended to help with focus, relaxation and sleep, backed by neuroscience. The app adapts sounds in real time using inputs such as time of day, weather, heart rate and location. It also offers versions for Apple Watch, Amazon Alexa, TV, desktop and streaming platforms.
EspNet is an end-to-end speech processing toolkit hosted on GitHub. It is open-source software designed for speech processing tasks, with repository documentation covering installation steps, quick start guidance, and details of supported processing tasks. Contributors can participate in its development via the GitHub platform.
Fast inference engine for whisper in C++ using CTranslate2.
結婚式スピーチ・弔辞・年賀状・退職挨拶・お礼状・お詫び文など、冠婚葬祭と日常の手紙・挨拶文をAIが作成します。シチュエーションを選んで項目を埋めるだけで、そのまま使える文面が完成。82種類のツールを登録不要・完全無料で今すぐ使えます。.
FunASR is an open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation and speaker diarization pipelines, with OpenAI-compatible and MCP serving. An industrial toolkit described for offline, streaming and edge deployment, it also covers emotion and audio-event models and keyword spotting. It is released under an MIT license.