Incanter is a Clojure-based, R-like platform for statistical computing and graphics. It provides charting and visualization, mathematical, statistical, matrix and linear algebra, and data manipulation functions. It can be used as a standalone interactive data analysis environment or embedded within other analytics systems as a modular suite of libraries.
Directory
Search results
Published directory entries matching your search.
ML, DL and Data Science - with a focus on text-/data-mining.
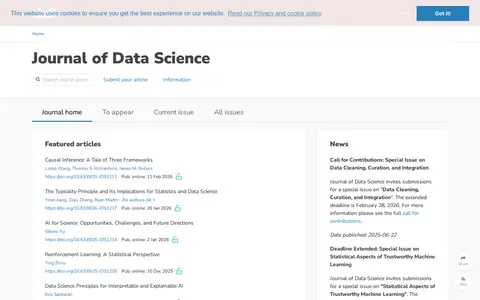
The Journal of Data Science is an academic journal listing featured articles, news, and calls for contributions. Featured articles include items on causal inference, reinforcement learning, and AI for science, each with a DOI and online publication date. The page also lists special issue calls for contributions and most-read articles.
JSON Schema is a declarative language for annotating and validating JSON documents' structure, constraints, and data types. It enables JSON data consistency, validity, and interoperability, and has a tooling ecosystem of validators, generators, and linters. Documentation covers schema design, guides, and keyword reference.
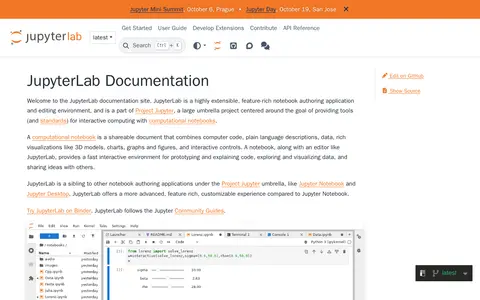
JupyterLab is an extensible notebook authoring application and editing environment within Project Jupyter. A notebook combines code, text descriptions, data and visualizations. JupyterLab provides an environment for prototyping and explaining code, exploring and visualizing data, and sharing ideas. It is a sibling to Jupyter Notebook and Jupyter Desktop and is described as offering a more advanced, customizable experience than Jupyter Notebook.
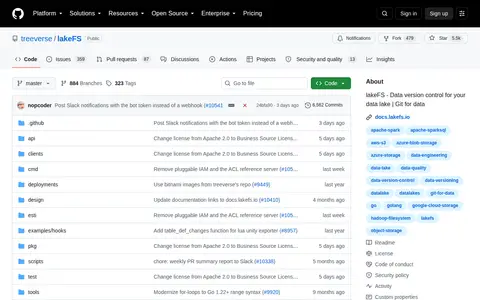
lakeFS is a source-available data version control tool that turns object storage into a Git-like repository, allowing data lakes to be managed like code. It supports AWS S3, Azure Blob Storage and Google Cloud Storage, is API compatible with S3, and works with frameworks such as Spark, Hive, AWS Athena, DuckDB and Presto.
Analyzes structured data and helps produce queries, insights or visualizations.
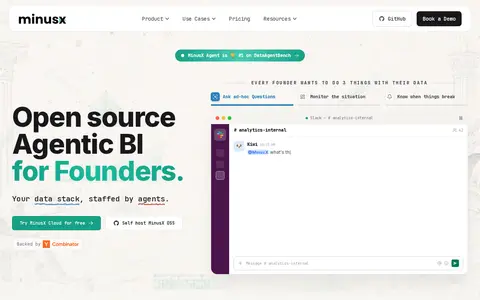
MinusX is an open source agentic business intelligence platform that combines a data agent with a BI tool. It answers questions, builds dashboards and sets alerts, with slides and data stories, visualizations and a SQL GUI. It can be self-hosted or used via MinusX Cloud, and the source is available and inspectable.
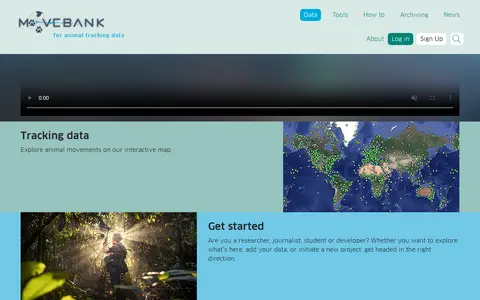
Movebank is a free online database of animal tracking data hosted by the Max Planck Institute of Animal Behavior. It helps animal tracking researchers manage, share, protect, analyze and archive their data, and offers an interactive map for exploring animal movements.
Analyzes structured data and helps produce queries, insights or visualizations.
nbshare.io is a platform for learning data analytics using Python and R. It hosts a collection of notebooks covering topics including artificial intelligence, machine learning, basic Python coding, data analytics, web scraping and other related technical subjects.
How a Social Scientist Jumps into the World of Big Data.
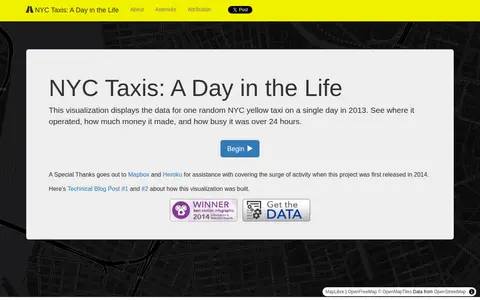
A data visualization by Chris Whong showing the activities of one random NYC yellow taxi on a single day in 2013, including where it operated and how much money it made. It uses taxi trip data provided by the Taxi and Limousine Commission via a FOIL request. Trip routes were produced with Google's Directions API and are not assumed accurate.
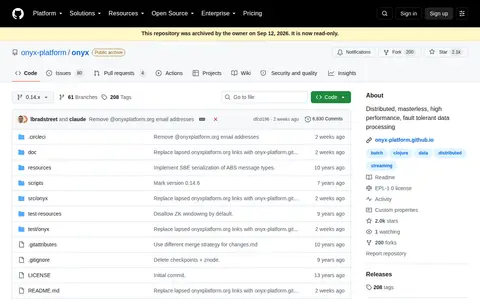
Onyx is a distributed, masterless data processing system written in pure Clojure, with a batch and stream hybrid processing model. The repository is archived and read-only. Listed uses include realtime event stream processing, extract, transform, load, and data cleaning.
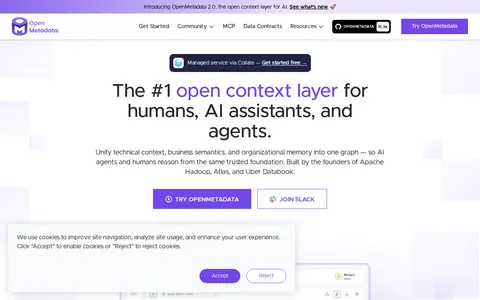
OpenMetadata is an open-source AI context layer powered by metadata, semantics, and memory that provides a shared, rich understanding of data for people and AI. It was built by the founders of Apache Hadoop, Apache Atlas, and Uber Databook. The unified platform supports data cataloging, discovery, quality, observability, governance, lineage, and collaboration.
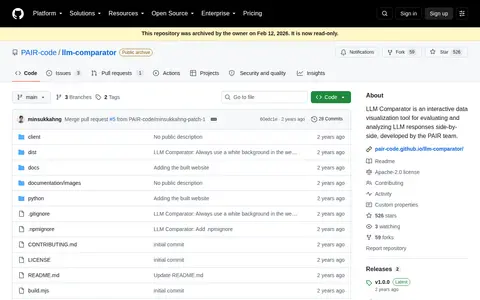
LLM Comparator is an interactive data visualization tool for evaluating and analyzing large language model responses side-by-side, developed by the PAIR team. It includes a Python library for creating JSON files and a defined JSON data format.
, a pluggable architecture for data and image processing, which can.
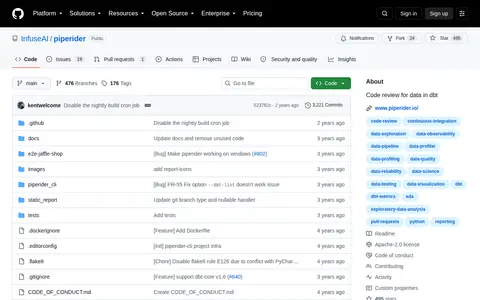
PipeRider is a tool described as code review for data in dbt. It compares data to highlight differences in impacted downstream dbt models, profiles dbt models, and generates a static HTML report each run. The project states that PipeRider has been superseded by Recce and will no longer be updated on a regular basis.
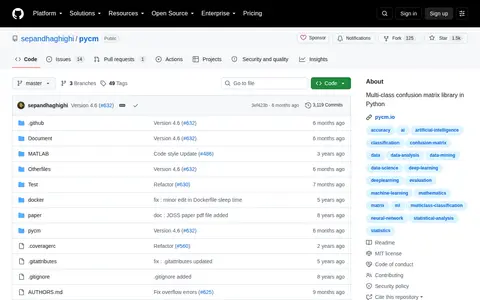
PyCM is a multi-class confusion matrix library written in Python. It supports input data vectors and direct matrices and offers post-classification model evaluation statistics. It is aimed at data scientists needing metrics for predictive models and classifiers. A MATLAB setup is also documented.
The repository holds materials and IPython notebooks for "Python for Data Analysis, 3rd Edition" by Wes McKinney, published by O'Reilly Media. Notebooks cover chapters on Python basics, NumPy, pandas, data loading, cleaning, visualization, time series and modeling libraries, plus appendices. The code is released under the MIT license.
RAWGraphs is a free and open source tool for data visualization. It is a web app that offers almost 30 visual models to visualize quantities, hierarchies and time series. Data inserted is processed only by the web browser, and projects can be saved or exported as vector or raster images.
Analyzes structured data and helps produce queries, insights or visualizations.
Skale is a distributed data processing and machine learning engine that provides a high-level API in JavaScript and a parallel execution engine on top of Node.js. The repository was archived by its owner on May 29, 2021 and is read-only. It supports multiple data sources and formats, and can run in local or distributed mode.