A free online text-to-speech tool that converts text into speech using an AI voice generator. It offers 100+ voices in 27 languages, allows MP3 download, and lets users adjust speed and pitch. No registration is required.
Directory
Search results
Published directory entries matching your search.
TTSReader is an online text-to-speech reader that turns text into natural-sounding speech for listening online or generating downloadable audio. It reads plain text, files, PDFs, e-books and websites, supports export to MP3, and remembers text and position between sessions. It runs in a browser without installation and also offers an iOS app.
Space emoji (emoji-only character allowed).
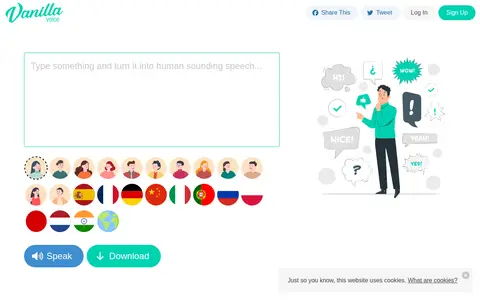
VanillaVoice is a free online text to speech tool that reads text aloud with human-sounding voices. Users can pick male, female or child voices in many languages, adjust volume and speed, and download audio as an MP3 without installing software. A Professional Plan offers a commercial license, speech-enabled products and up to 500 words per recording.
Voctro Labs is a Barcelona-based company founded in 2011 that develops AI-based voice, music and audio technologies for creative companies and individuals. Its products include Voiceful, a toolkit for speech and singing voice experiences with a cloud-based API and SDK libraries, and Virtual Singers for Yamaha's VOCALOID software. Services include personalized voices and customized algorithms.
Voice Dream Reader is a text-to-speech app that reads PDFs, web pages, and books aloud. It supports importing PDFs, EPUBs, Word documents, PowerPoint files, and web pages, with highlighting, notes, offline listening, and syncing across iPhone, iPad, and Mac. Accessibility features include VoiceOver support, Dynamic Type, Voice Control, and braille display support.
Voicery is a company that creates natural-sounding text-to-speech engines and custom brand voices for enterprise clients. Its solutions leverage deep-learning research optimized for specific business use cases and technical infrastructure.
Vosk is an offline speech recognition API hosted in the alphacep/vosk-api GitHub repository. It is compatible with Android, iOS, Raspberry Pi, and server environments, and provides SDKs for Python, Java, C#, and Node.
A simple and efficient end-to-end Automatic Speech Recognition (ASR) system from Facebook AI Research.
Works with speech, voice, music or other audio using machine-learning models.
USE BAZEL VERSION=5.0.0./bazelisk-linux-amd64 build wavegru mod -c opt --copt=-march=native.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.
A C/C++ port of OpenAI's Whisper automatic speech recognition model, providing high-performance inference without dependencies. It supports CPU-only inference and GPU backends, and runs on platforms including macOS, iOS, Android, Linux, Windows, WebAssembly and Raspberry Pi. The whisper-cli example currently runs only with 16-bit WAV files.
XTTS is a Hugging Face Space that provides multi-language text-to-speech functionality. It converts written text into spoken audio across multiple languages, and allows users to optionally upload a short voice recording or use their microphone for voice input.
Microsoft translation tool for text, speech, web pages, and multilingual communication.
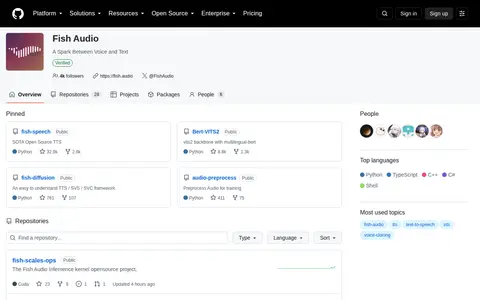
Fish Audio is an AI platform for voice generation, voice cloning, and audio storytelling, and its GitHub organization hosts open source repositories. Public repositories include fish-speech, described as SOTA open source TTS, Bert-VITS2, a vits2 backbone with multilingual-bert, and fish-diffusion, a TTS / SVS / SVC framework.
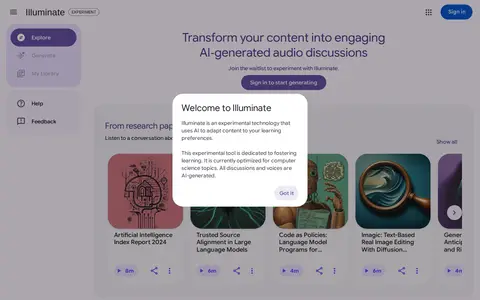
Google Illuminate uses AI for speech, voice, transcription, music, or other audio workflows.
Google translation service for translating text, web pages, documents, and speech between languages.
Acapella Extractor uses AI for speech, voice, transcription, music, or other audio workflows.
AceTagGen is a free prompt system for SUNO AI. It offers a structured 12-step Tag Builder, a library of verified tags, a prompt scorer, and a research blog with articles and guides. No signup is required.
AI Mastering is an automated online audio mastering service that uses AI. Free mastering is available, with drag-and-drop uploading, target loudness and mastering level customization, and output format, spectrum and loudness analysis. An API is documented, and a desktop offline version has been released.
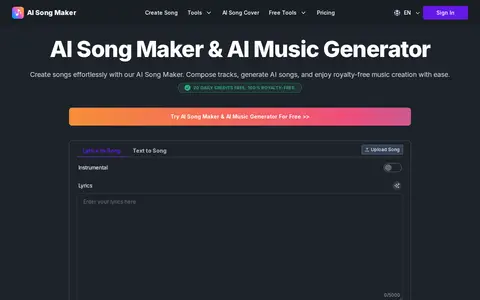
A web tool for generating songs from text, lyrics or uploaded audio, with style, voice and tempo options and instrumental-only tracks. Songs can be downloaded or shared. The free tier offers 20 daily credits and royalty-free output.
A YouTube Blog post announcing an early look at the company's first AI-related music experiments: Dream Track for Shorts and Music AI tools, built in collaboration with Google DeepMind. Dream Track is powered by the Lyria music generation model and initially lets a small group of select US creators create soundtracks of up to 30 seconds for Shorts.
AnyVoiceLab offers a free long-form text-to-speech converter that processes up to 50,000 characters, about one hour of audio, without requiring login. Users paste text and choose a voice to generate narration and can download the audio for free. A paid premium tier adds a timeline editor for pauses, speed changes, splitting and merging audio.