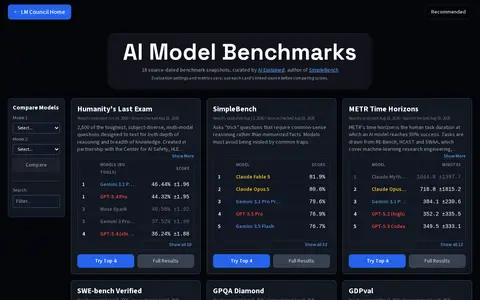
LM Council presents source-dated benchmark snapshots for AI models. It covers GPT, Claude, Gemini and other frontier models across benchmarks including Humanity's Last Exam, FrontierMath, GPQA and SWE-bench, with a comparison tool selecting two models. Each snapshot links its source and checked date, and evaluation settings and metrics vary.
Directory
Search results
Published directory entries matching your search.
Local Deep Research is a tool that achieves approximately 95% accuracy on the SimpleQA benchmark, with an example run using Qwen3.6-27B on an RTX 3090. It supports all local and cloud LLMs including llama.cpp, Ollama, and Google models, integrates over 10 search engines such as arXiv, PubMed, and private document sources, and operates with local and encrypted processing.
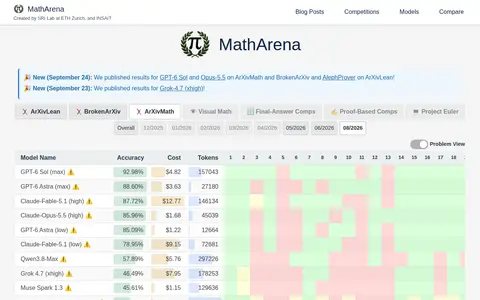
MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.
An open source robotics benchmark for meta- and multi-task reinforcement learning.
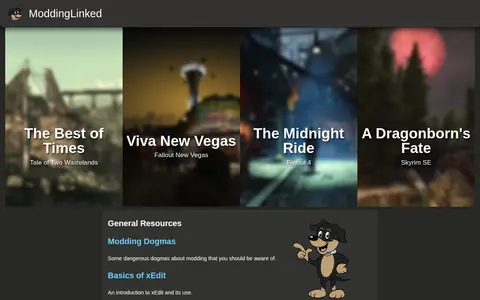
ModdingLinked is a collection of Vanilla+ modding guides for Fallout and The Elder Scrolls games. Its guides include The Best of Times, Viva New Vegas, The Midnight Ride and A Dragonborn's Fate. It also offers general resources on modding dogmas, xEdit basics, The Method conflict resolution and performance benchmarks, with an MO2 user guide noted as coming soon.
Moonshot AI is a GitHub organization focused on AI and machine learning research and development. As of the listing snapshot, it hosts 42 public repositories, with areas of work including research, benchmarks, agents, service infrastructure, and community engagement, and its code is available on GitHub.
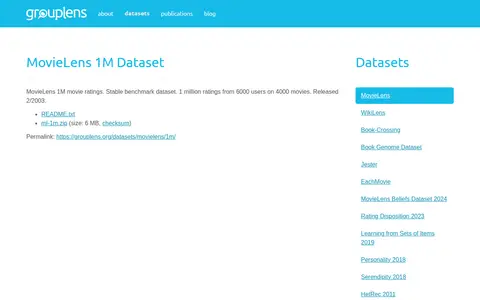
MovieLens 1M is a stable benchmark dataset of movie ratings containing 1 million ratings from 6000 users on 4000 movies, released in February 2003. It is available as a downloadable archive with a checksum and README.
MSI Kombustor is MSI's exclusive burn-in benchmarking tool based on the FurMark software. It is designed to push a graphics card to its limits to test stability and thermal performance. The tool supports 3D APIs such as OpenGL or Vulkan.
nanoBench is a Linux-based tool for running small microbenchmarks on recent Intel and AMD x86 CPUs, evaluated with hardware performance counters. It offers a user-space variant and a kernel module; the kernel module permits benchmarking privileged instructions and using uncore counters, but should not be used on a production system.
NanoReview is a platform for comparing laptops, smartphones, CPUs, and other tech devices. It collects specifications and test results in one place and provides comparisons and rankings of processors, smartphones, laptops, GPUs, and tablets. The site also accepts crowdsourced benchmark results and user comments.
Evals is a framework for evaluating large language models and systems built using LLMs. It offers an existing registry of evals to test different dimensions of OpenAI models and the ability to write custom evals. It is available as an open-source registry of benchmarks. Evals require an OpenAI API key.
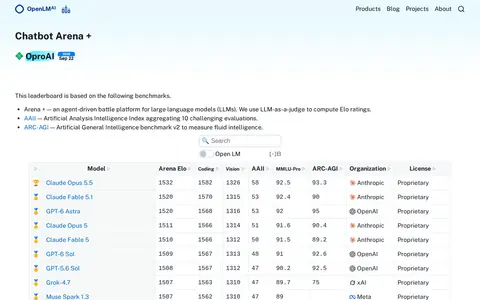
OpenLM Arena is a leaderboard site that ranks large language models. It bases rankings on three benchmarks: an agent-driven battle platform with Bradley-Terry Elo ratings from LLM-as-a-judge votes, a Model Intelligence Index, and the ARC-AGI-2 general intelligence benchmark. The page lists models with Elo, coding, vision, MII and ARC-AGI figures alongside organization and license.
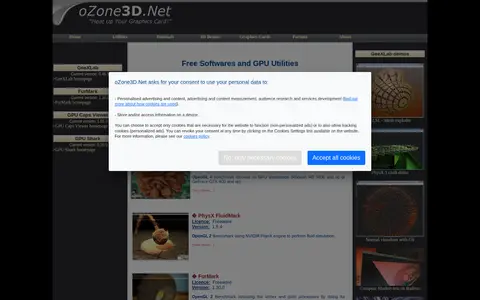
Ozone3D.Net offers free 3D graphics software and tutorials, including a set of GPU benchmarks and utilities. The listed tools include GPU Caps Viewer, a freeware utility describing graphics card capabilities, memory and OpenGL support, and GPU Shark, a GPU monitoring utility for NVIDIA and AMD/ATI cards. FurMark is a Freeware OpenGL 2 benchmark stressing vertex and pixel processors through fur rendering.
PC-Optimization-Hub is a GitHub repository collecting various resources devoted to performance and input lag optimization. It covers topics including benchmarking, debloat, DPC latency, frame times, polling rates and Windows optimization, and includes sections on data collection and physical setup.
PocketPal AI is an open-source app for running language models directly on a device, available on iOS and Android. It supports GGUF models from Hugging Face, on-device processing, device benchmarking, conversation history and adjustable inference settings.
Ponytail 5 is a ruleset for AI coding agents intended to make them write the least code that works. It provides a review command and an audit command, and states tests accompany risky logic. The project reports benchmark comparisons against running without it.
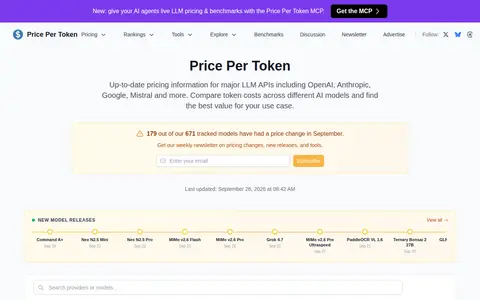
PricePerToken is a free comparison site for LLM API pricing. It presents per-token costs for models from providers including OpenAI, Anthropic, Google and Mistral, alongside model listings with context windows and benchmark figures. Pages cover individual models such as Amazon Nova Lite 1.0 and Nova Micro 1.0, whose pricing and context windows are stated.
PyTorch Geometric Temporal is a temporal extension library for PyTorch Geometric. It contains dynamic and temporal geometric deep learning, embedding and spatio-temporal regression methods from published research papers. It includes a dataset loader, train-test splitter and temporal snapshot iterator for dynamic and temporal graphs, with GPU support and benchmark datasets.
LLMeBench is a flexible framework for accelerating the benchmarking of large language models. It provides tools to run benchmarks and evaluate model performance. The project is hosted on GitHub under the qcri organization.
CLI tool for debugging and benchmarking RAG retrieval. EXPLAIN ANALYZE for your retrieval layer.
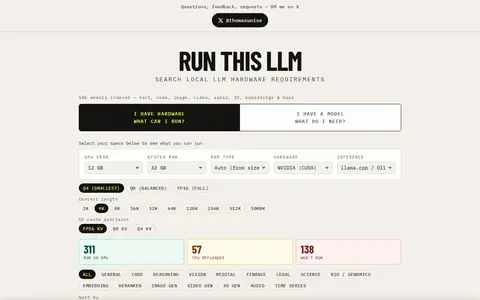
RunThisLLM is a website that provides hardware requirements for running local AI models. It lists over 295 models with full build specifications, performance estimates, and benchmarks. It also offers a Chrome extension and a custom machine building service.
WhisperS2T is an optimized speech-to-text pipeline for the Whisper model that supports multiple inference engines. The repository provides release notes, quickstart guides, future roadmaps, and a benchmark and technical report.
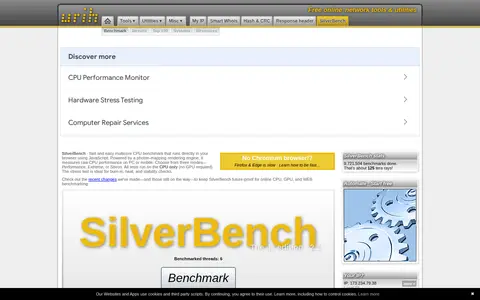
SilverBench is a JavaScript-based CPU benchmark and stress test that runs in a browser. It offers Performance, Extreme and Stress modes and measures CPU performance on PCs and mobile devices using a photon-mapping rendering engine, with all tests running on the CPU only.
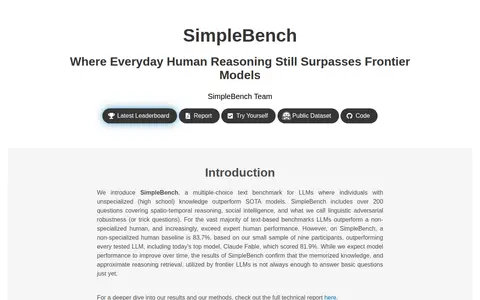
SimpleBench is a multiple-choice text benchmark for LLMs with over 200 questions covering spatio-temporal reasoning, social intelligence and trick questions. Its report states a non-specialized human baseline of 83.7 percent from a small sample of nine participants.