wave-ai.net
Works with speech, voice, music or other audio using machine-learning models.
Directory
Published directory entries matching your search.
Works with speech, voice, music or other audio using machine-learning models.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.

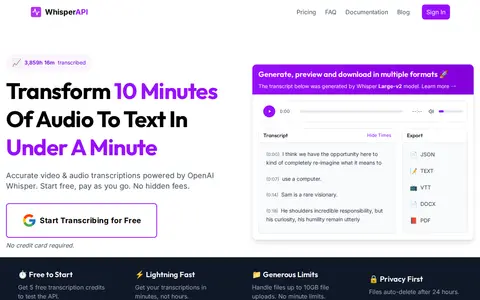
A transcription API built on OpenAI Whisper that converts audio and video files to text. It supports file uploads and remote URLs, multiple output formats, and model size selection for speed versus accuracy. A no-code dashboard offers drag-and-drop transcription. Pricing is pay-as-you-go with credit bundles, and files auto-delete after 24 hours.
Works with speech, voice, music or other audio using machine-learning models.
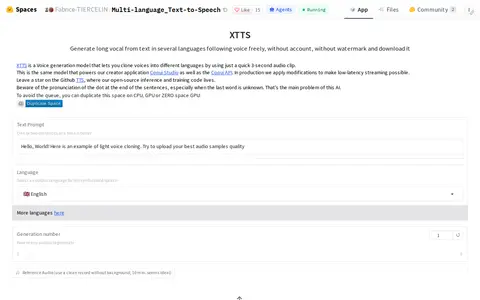
XTTS is a Hugging Face Space that provides multi-language text-to-speech functionality. It converts written text into spoken audio across multiple languages, and allows users to optionally upload a short voice recording or use their microphone for voice input.
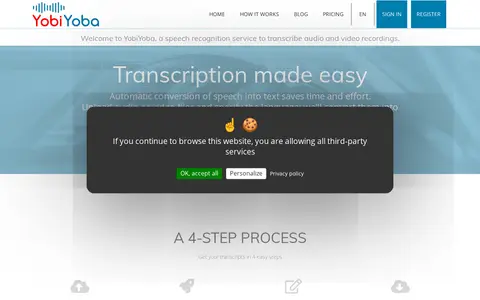
YobiYoba is a speech recognition service that transcribes audio and video recordings into editable, time-coded text. Users upload files, specify or auto-detect the language, verify and edit transcripts, then download them in formats such as SRT, PDF, or VTT. Processing produces speaker labels, time codes, and confidence scores. Pricing is pay-as-you-go, from 0.01 € per minute of speech.
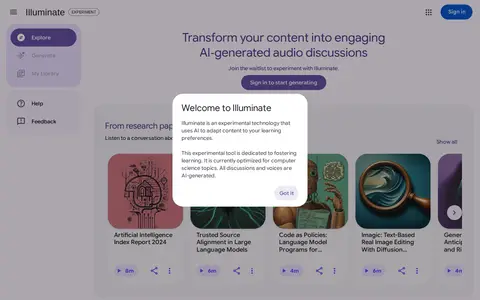
Google Illuminate uses AI for speech, voice, transcription, music, or other audio workflows.
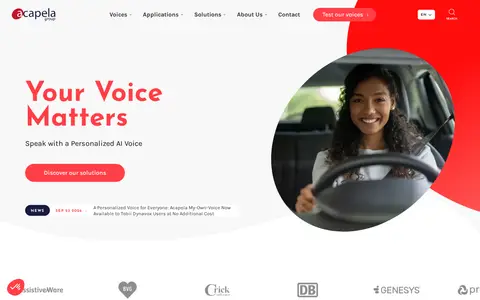
Acapela Group is a company that develops personalized digital voices using voice AI technology. It offers text-to-speech solutions for services, applications and devices, with support for over 30 languages and more than 200 pre-made voices, plus custom voice creation options. The company provides SDKs for multiple platforms, cloud streaming APIs, and specialized solutions including voice AI for accessibility, transport and customer interaction.
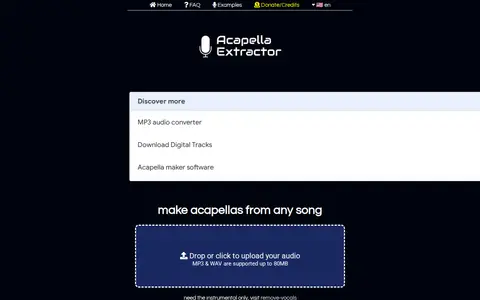
Acapella Extractor uses AI for speech, voice, transcription, music, or other audio workflows.
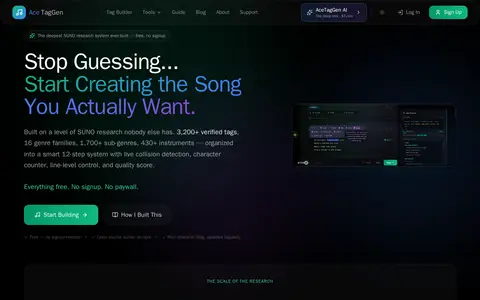
AceTagGen is a free prompt system for SUNO AI. It offers a structured 12-step Tag Builder, a library of verified tags, a prompt scorer, and a research blog with articles and guides. No signup is required.
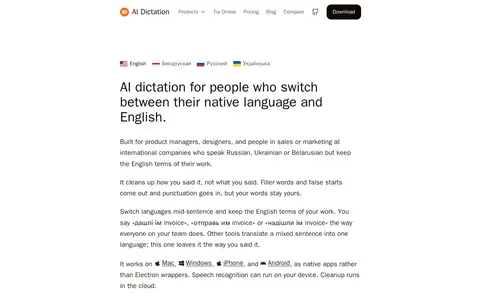
AI Dictation is a voice typing app for people who mix English into Russian, Ukrainian or Belarusian. It removes filler words and adds punctuation without translating work terms. It runs on Mac, Windows, iPhone and Android, and speech recognition can run on device while cleanup runs in the cloud.
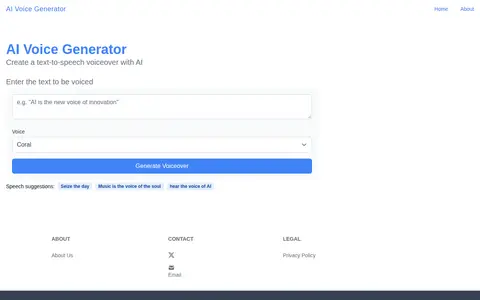
AI Voice Generator is a free online tool that produces natural-sounding text-to-speech voice overs. Users enter text, select from various AI voices, and generate a voiceover. The service emphasizes simplicity and accessibility for creating spoken content.

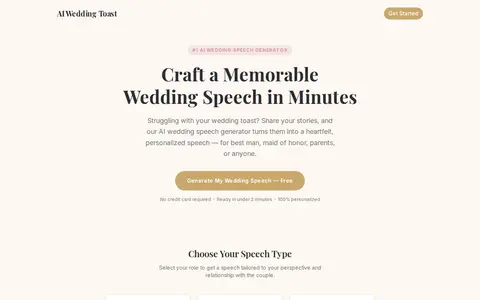
AI Wedding Toast is a free AI wedding speech generator that turns shared stories and memories into personalized speeches. It offers speech types including best man, maid of honor, father of the bride, groom, bride, wedding vows and others, generated in under two minutes without a credit card.
AIVA is an AI music generation assistant that creates new songs in more than 250 styles within seconds. Users can build style models, upload audio or MIDI influence, and edit generated tracks. A free plan offers non-commercial use with credit to AIVA and three downloads per month.
AIVocal is an AI-powered voice assistant platform. It provides tools for AI voice generation, voice cloning, text-to-speech, speech-to-text, vocal removal, audiobook generation, podcast generation and audio transcription, serving creators and professionals for voice-related work.
A YouTube Blog post announcing an early look at the company's first AI-related music experiments: Dream Track for Shorts and Music AI tools, built in collaboration with Google DeepMind. Dream Track is powered by the Lyria music generation model and initially lets a small group of select US creators create soundtracks of up to 30 seconds for Shorts.
Applio is an open-source AI voice conversion suite. It provides voice conversion, real-time voice changing, speech synthesis, model training, voice blending and audio analysis. The project states it is MIT licensed and runs on Windows, macOS and Linux, with a desktop app or Gradio WebUI, and no accounts or telemetry.

AssemblyAI provides voice AI infrastructure, including pre-recorded, realtime and synchronous speech-to-text APIs, a voice agent API, speech understanding features and guardrails. Features such as speaker diarization, summarization, sentiment analysis and PII redaction run on the same transcription request.
Audacity Effects is a set of OpenVINO AI plugins for Audacity, offering effects such as music separation into stems, noise suppression, music generation with MusicGen, Whisper transcription and audio super resolution. It is available for Windows and macOS. The plugins are noted as not yet compatible with the latest Audacity version.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
You can also find more comprehensive list on and There's an AI AI Voice Cloning list.
Open-source project that uses AI for speech, voice, transcription, music, or other audio workflows.
Bespoke Sounds is a sonic identity studio that creates custom branded soundtracks for lifestyle, luxury, and boutique hospitality brands. The studio is run by a team of DJs, musicians, and audiophiles.

Boomy uses AI for speech, voice, transcription, music, or other audio workflows.