Speechify is a text to speech and voice typing assistant that reads books, PDFs, documents and web pages aloud with natural-sounding voices. It offers text highlighting, speed control and scan and listen, and is available as browser extensions, desktop apps for Windows and Mac, and mobile apps for iOS and Android.
Directory
Search results
Published directory entries matching your search.
A Hugging Face Space by amphion titled Text To Speech. The application converts text into speech using various voice options, with speaker selection and adjustable speaking rate. For advanced users, it also allows mixing two voices.
Works with speech, voice, music or other audio using machine-learning models.
The Prompter vicc Substack uses AI for speech, voice, transcription, music, or other audio workflows.
Works with speech, voice, music or other audio using machine-learning models.
This Hugging Face Space by k2-fsa is a text-to-speech application that converts user-entered text to spoken audio. Users can select a language or model, and may upload or record a short reference audio clip to generate speech in a specific person's voice.
Works with speech, voice, music or other audio using machine-learning models.
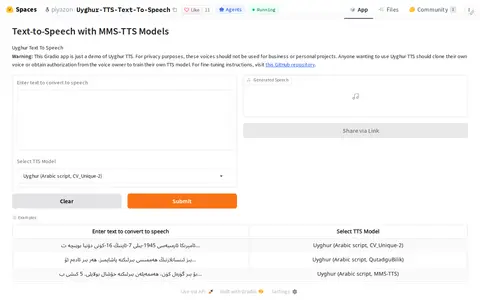
Uyghur TTS Text To Speech is a Hugging Face Space developed by piyazon. The application allows users to input Uyghur text, including numbers, Chinese characters and punctuation, select a Uyghur text-to-speech voice, and convert the typed text into natural-sounding Uyghur speech audio.
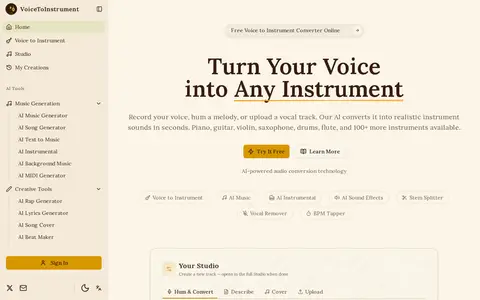
voicetoinstrument.com is an AI audio conversion platform that transforms uploaded voice recordings, hummed melodies, or vocal tracks into realistic instrument sounds. It supports conversion to more than 100 instruments including piano, guitar, violin, saxophone, drums, and flute, and offers a free online converter alongside additional AI audio tools such as stem splitters and vocal removers.
Works with speech, voice, music or other audio using machine-learning models.
WellSaid uses AI for speech, voice, transcription, music, or other audio workflows.
Works with speech, voice, music or other audio using machine-learning models.
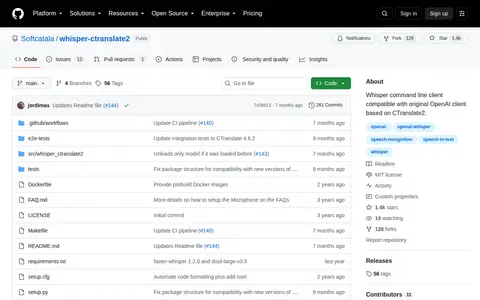
Whisper command line client compatible with the original OpenAI client and based on CTranslate2. It uses CTranslate2 and the Faster-whisper implementation. The project lists Docker images with pre-loaded models, speaker diarization, voice activity detection and live transcription from a microphone. It is installed as a Python package or run from a Docker image.
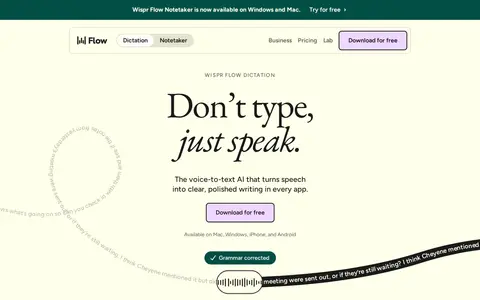
Wispr Flow is a voice-to-text dictation tool that converts speech into text in any app and on every device. It includes a Notetaker feature. It is available on Mac, Windows, iPhone, and Android. A free plan includes speech-to-text in any app and 100+ languages; paid plans add team management and admin controls.
Audio diffusion library for PyTorch that includes models for unconditional audio generation, text-conditional audio generation, diffusion autoencoding, upsampling, and vocoding. The models are waveform-based, and the U-Net, DiffusionModel, diffusion method, and samplers are customizable for other formats. No pre-trained models are provided.
StemGen is an end-to-end music generation model trained to listen to musical context and respond appropriately. It is built on a non-autoregressive language-model type architecture similar to SoundStorm and VampNet, and is presented as examples for an ICASSP2024 paper.
Google Illuminate uses AI for speech, voice, transcription, music, or other audio workflows.
Acapella Extractor uses AI for speech, voice, transcription, music, or other audio workflows.
AnyVoiceLab offers a free long-form text-to-speech converter that processes up to 50,000 characters, about one hour of audio, without requiring login. Users paste text and choose a voice to generate narration and can download the audio for free. A paid premium tier adds a timeline editor for pauses, speed changes, splitting and merging audio.