webcrawler.com
WebCrawler is a web search engine or search directory for finding websites, pages, and online information.
Directory
Published directory entries matching your search.
WebCrawler is a web search engine or search directory for finding websites, pages, and online information.
WebSitesSearch is a web search engine or search directory for finding websites, pages, and online information.
Yandex is a technology company that develops intelligent products and services powered by machine learning. It has provided search and information services since 1997, and also offers on-demand transportation, navigation, and mobile applications. The company operates 17 offices worldwide and has been listed on the NASDAQ since 2011.
Search engine for finding web pages and specialized online information.
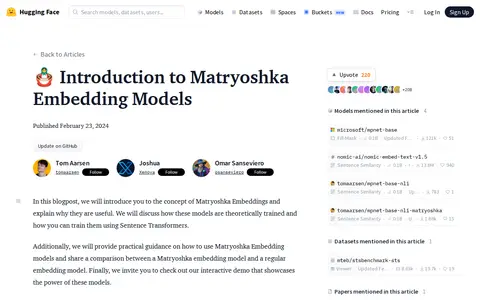
A Hugging Face blog post introducing Matryoshka Embedding models. It explains embeddings as numerical representations and describes how Matryoshka models store more important information in earlier dimensions, allowing large embeddings to be truncated while remaining useful. It covers theoretical training and training with Sentence Transformers, with a comparison to a regular embedding model.
Interactive Hugging Face app that helps find, analyze or synthesize information for research and knowledge discovery.
Microsoft search engine for web results, images, videos, maps, news, and AI-assisted answers.
8bitconcepts is an embedded AI consulting practice that works inside operating businesses to ship AI workflow and process systems. It targets repetitive operations, support, data-preparation and review workflows, and publishes research papers and data snapshots alongside live AI products.
Paper by Dipankar Dasgupta, Deepak Venugopal and Kishor Datta Gupta.
This arXiv paper by Dirk Lewandowski and Philipp Mayr provides a critical review of Bergman's 2001 study on the Deep Web. It introduces the concept of the Academic Invisible Web, defined as databases and collections relevant to academia but not searchable by general-purpose internet search engines, and reviews approaches for indexing it. The authors question Bergman's size estimate and suggest collaboration.

Accord.MachineLearning is a NuGet package, part of the Accord.NET Framework, that contains Support Vector Machines, Decision Trees, Naive Bayesian models, K-means, Gaussian Mixture models, and general algorithms such as Ransac, Cross-validation and Grid-Search for machine-learning applications. Version 3.8.0 targets .NET Standard 1.4 and .NET Framework 3.5.
Paper published in the Proceedings of the 2023 AAAI/ACM Conference on AI, Ethics, and Society.
An article by Andy Baio examining how AI companies use datasets and models from academic and nonprofit research groups. It describes Meta's Make-A-Video using Shutterstock clips and YouTube videos collected by Microsoft, and notes nonprofit datasets used for Stable Diffusion and other models. It argues this outsourcing shifts accountability and legal liability away from corporations.
25th Aug, 2023 Feature: Adding TextArea for custom prompts.
Algorithms of Oppression by Safiya Umoja Noble is a book published by NYU Press in February 2018 under the title How Search Engines Reinforce Racism. It examines how negative biases against women of color are embedded in search engine results and algorithms.
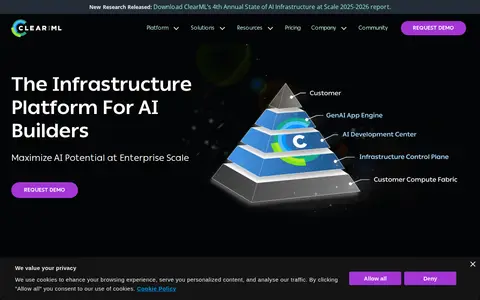
ClearML is an AI infrastructure platform organized in three layers. The Infrastructure Control Plane connects and manages GPU clusters across on-premises, cloud, and hybrid environments, with multi-tenancy, role-based access control, and billing. The AI Development Center provides a workbench for developing, training, and testing models. The GenAI App Engine deploys LLMs onto clusters, with ClearML handling networking, authentication, and security.
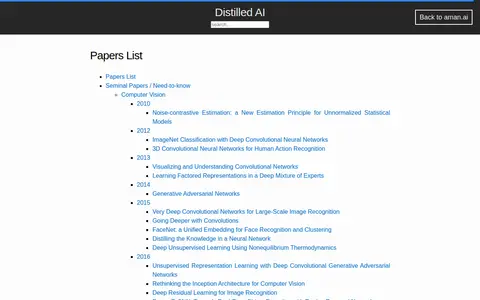
Aman's AI Journal papers list compiles seminal and need-to-know computer vision papers, organized by publication year from 2010 onward. Entries include titles such as ImageNet Classification with Deep Convolutional Neural Networks, Generative Adversarial Networks, and Deep Residual Learning for Image Recognition. The site also offers course notes and learning material for Artificial Intelligence and Deep Learning Stanford classes.

Custom Google search engine focused on finding video and streaming resources across selected websites.
Archivarix Tube Search is a search engine for finding deleted, removed, and unavailable YouTube videos. It searches the Wayback Machine, Common Crawl, and other web archives to recover video metadata, thumbnails, subtitles, and links to archived video files. Users can search by channel, by video URL or ID, or full-text.

Search engine for finding arguments, claims, and supporting sources for debates.

Artificial Intelligence: A Modern Approach is the official companion site for the 4th US edition of the AI textbook of the same name, authored by Stuart Russell and Peter Norvig. The textbook is the most widely used AI textbook, adopted by over 1500 schools. The site provides supporting resources including the book's table of contents, code, course materials, exercises, figures, and errata.
Question-focused search engine and web portal for finding answers, pages, images, and news.

Custom Google search engine focused on finding audio resources across selected websites.
Audiolabs, formally the International Audio Laboratories Erlangen, is a joint research institution operated by Fraunhofer IIS and Friedrich-Alexander-Universität Erlangen-Nürnberg (FAU), founded in 2010. The organization conducts research in audio and multimedia technologies, with focus areas including audio coding, audio signal analysis, and perceptual spatial audio signal processing. It also hosts academic events including the International Symposium on the Internet of Sounds.