Imagen is a text-to-image diffusion model from Google Research's Brain Team that creates photorealistic images from input text. It builds on large transformer language models for text understanding and cascaded diffusion models for image generation. The project also introduced DrawBench, a benchmark for comparing text-to-image models.
Directory
Search results
Published directory entries matching your search.
The Indico LLM Leaderboard provides benchmarking for large language models on extractive, classification, and predictive tasks. It includes accuracy comparisons, cost of ownership assessments, and datasets such as CORD and Kleister NDA, with the latest update in August 2024.
The Institute of Museum and Library Services provides a data page with tools and reports for exploring library and museum data. It includes Library Search & Compare for individual library data and ten-year trends, an indicators workbook on economic status and broadband, a state funding report compilation, a state comparison tool, public library benchmarking tables, and administrative discretionary grant data.
Edit /src/streamlit app.py to customize this app to your heart's desire.:heart:.
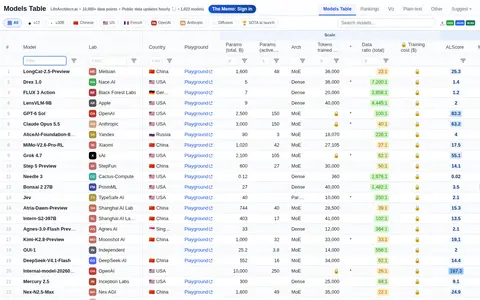
LifeArchitect.ai hosts a Models Table of large language model data, including parameters, tokens trained, and benchmark scores such as MMLU, MMLU-Pro, GPQA and HLE. The page also presents rankings, a data dictionary and visualization snapshots of frontier models.
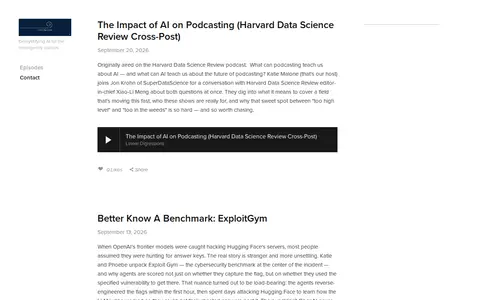
Linear Digressions is a podcast series covering machine learning and AI topics, with episodes such as "LLM as a Judge," a cross-post on AI and podcasting from the Harvard Data Science Review, and a benchmark installment on ExploitGym. One episode examines mechanistic interpretability, described as an approach that opens the model itself to trace why it behaves as it does.
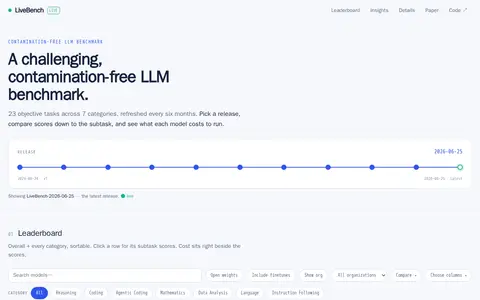
A Challenging, Contamination-Free LLM Benchmark.
LLM Explorer is a directory of open-source language models and AI agents. It lists 150 AI agents and 64,811 open-source large and small language models, grouped into categories with benchmarks and analytics.
LLM Stats is an AI leaderboard that ranks GPT, Claude, Gemini, Llama, DeepSeek and more than 300 AI models by intelligence, speed and price. Scores are computed from public benchmarks and live API metrics.
LM Council presents source-dated benchmark snapshots for AI models. It covers GPT, Claude, Gemini and other frontier models across benchmarks including Humanity's Last Exam, FrontierMath, GPQA and SWE-bench, with a comparison tool selecting two models. Each snapshot links its source and checked date, and evaluation settings and metrics vary.
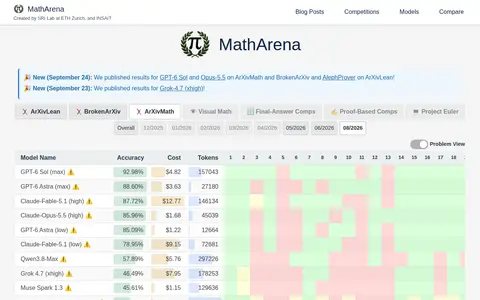
MathArena evaluates large language models on uncontaminated math benchmarks. It presents model analysis across competitions such as ArXivLean, BrokenArXiv, ArXivMath, Visual Math, Final-Answer Comps, Proof-Based Comps and Project Euler. A competition is selected to load tables and a leaderboard, and clicking a cell shows the raw model output.
ModdingLinked is a collection of Vanilla+ modding guides for Fallout and The Elder Scrolls games. Its guides include The Best of Times, Viva New Vegas, The Midnight Ride and A Dragonborn's Fate. It also offers general resources on modding dogmas, xEdit basics, The Method conflict resolution and performance benchmarks, with an MO2 user guide noted as coming soon.
Moonshot AI is a GitHub organization focused on AI and machine learning research and development. As of the listing snapshot, it hosts 42 public repositories, with areas of work including research, benchmarks, agents, service infrastructure, and community engagement, and its code is available on GitHub.
MovieLens 1M is a stable benchmark dataset of movie ratings containing 1 million ratings from 6000 users on 4000 movies, released in February 2003. It is available as a downloadable archive with a checksum and README.
MSI Kombustor is MSI's exclusive burn-in benchmarking tool based on the FurMark software. It is designed to push a graphics card to its limits to test stability and thermal performance. The tool supports 3D APIs such as OpenGL or Vulkan.
NanoReview is a platform for comparing laptops, smartphones, CPUs, and other tech devices. It collects specifications and test results in one place and provides comparisons and rankings of processors, smartphones, laptops, GPUs, and tablets. The site also accepts crowdsourced benchmark results and user comments.
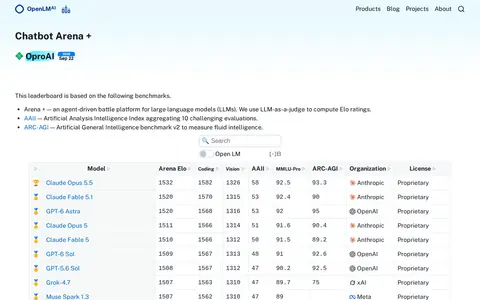
OpenLM Arena is a leaderboard site that ranks large language models. It bases rankings on three benchmarks: an agent-driven battle platform with Bradley-Terry Elo ratings from LLM-as-a-judge votes, a Model Intelligence Index, and the ARC-AGI-2 general intelligence benchmark. The page lists models with Elo, coding, vision, MII and ARC-AGI figures alongside organization and license.
Ozone3D.Net offers free 3D graphics software and tutorials, including a set of GPU benchmarks and utilities. The listed tools include GPU Caps Viewer, a freeware utility describing graphics card capabilities, memory and OpenGL support, and GPU Shark, a GPU monitoring utility for NVIDIA and AMD/ATI cards. FurMark is a Freeware OpenGL 2 benchmark stressing vertex and pixel processors through fur rendering.
PocketPal AI is an open-source app for running language models directly on a device, available on iOS and Android. It supports GGUF models from Hugging Face, on-device processing, device benchmarking, conversation history and adjustable inference settings.
Ponytail 5 is a ruleset for AI coding agents intended to make them write the least code that works. It provides a review command and an audit command, and states tests accompany risky logic. The project reports benchmark comparisons against running without it.
PricePerToken is a free comparison site for LLM API pricing. It presents per-token costs for models from providers including OpenAI, Anthropic, Google and Mistral, alongside model listings with context windows and benchmark figures. Pages cover individual models such as Amazon Nova Lite 1.0 and Nova Micro 1.0, whose pricing and context windows are stated.
RunThisLLM is a website that provides hardware requirements for running local AI models. It lists over 295 models with full build specifications, performance estimates, and benchmarks. It also offers a Chrome extension and a custom machine building service.
SilverBench is a JavaScript-based CPU benchmark and stress test that runs in a browser. It offers Performance, Extreme and Stress modes and measures CPU performance on PCs and mobile devices using a photon-mapping rendering engine, with all tests running on the CPU only.
SimpleBench is a multiple-choice text benchmark for LLMs with over 200 questions covering spatio-temporal reasoning, social intelligence and trick questions. Its report states a non-specialized human baseline of 83.7 percent from a small sample of nine participants.