ReadStat.jl, listed as Data Read, is an open-source Julia library for reading data files in Stata, SAS, and SPSS formats. The project is hosted on GitHub under the queryverse organization, where users can access source code and contribute to its development.
Directory
Search results
Published directory entries matching your search.
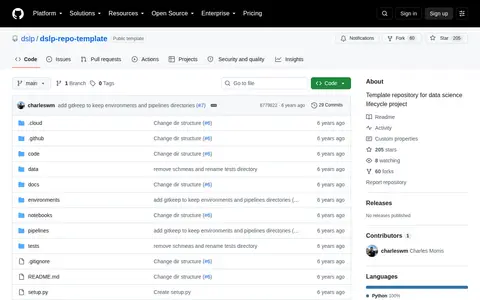
A public GitHub template repository for data science lifecycle projects. It provides a default directory structure including folders for code, data, docs, environments, notebooks, pipelines and tests, plus issue templates and a .github labels file. The source describes it as a launch-off point with minimal opinions. One manual step is creating labels from the labels file.
DataComPy is a package for comparing two DataFrames or tables. It supports Pandas, Polars, Spark (classic and Spark Connect), and Snowflake, and was originally created as a replacement for SAS PROC COMPARE for Pandas DataFrames. It prints stats and lets users adjust required match accuracy.
DataDeps.jl is a Julia package designed to facilitate reproducible data setup for scientific research. It manages data dependencies and includes features such as progress callbacks. The repository is maintained on GitHub.
DataFrames.jl is a Julia library that provides in-memory tabular data structures for data manipulation and analysis. It is developed by the JuliaData organization and its source code is hosted on GitHub.
A lightweight framework for data analysis in JavaScript.
Collect, clean and visualize your data in Python.
A GitHub Repository Where you can Learn Datavisualizatoin Basics to Intermediate level.
DeepAlpha is an AI-powered cryptocurrency trading bot that uses a deep neural network combining BiLSTM and attention mechanisms, trained on GPU. It supports 25 coins with a reported 84.9% accuracy rate, integrates with Bybit, Binance, OKX, and Gate.io exchanges, and is available as a free cloud or self-hosted service.
An agentic LLM for autonomous data science that performs data preparation, analysis, modeling, visualization, and report generation without human intervention. It supports open-ended research on structured, semi-structured, and unstructured data sources, and the model, code, training data, and demo are open-sourced.
Deepchecks is an open-source project for validating machine learning models and data from research to production. It includes built-in and custom checks and suites for tabular, NLP and CV validation, CI and testing management, and monitoring of deployed models. Installation is via pip.
Deepnote is a drop-in replacement for Jupyter with an AI-first design. It uses the Deepnote kernel, adds block types, native data integrations and an AI agent, and supports Python, R and SQL locally in an IDE before scaling to Deepnote Cloud for collaboration and deployable data apps.
A listener that streams your spark events logs to delight, a free and improved spark UI.
Delta Lake is an open-source storage framework designed to support the construction of a Lakehouse architecture. It is compatible with multiple compute engines including Apache Spark, PrestoDB, Flink, Trino, and Hive, as well as associated APIs.
Desbordante is a high-performance open-source data profiler. It uses a variety of algorithms to discover different patterns in data and supports running data cleaning scenarios using these algorithms. The tool is available as a console version and an easy-to-use web application.
distilabel is a framework for synthetic data generation and AI feedback intended for engineers. It provides fast, reliable, and scalable pipelines based on verified research papers, supporting data synthesis for AI systems and on-the-fly feedback addition. The framework aims to improve AI output quality via enhanced data quality, give users control over their data and models, and boost efficiency through rapid iteration on research and large language models.
A Julia package for probability distributions and associated functions.
Library of SAS Enterprise Miner process flow diagrams to help you learn by example about specific data mining topics.
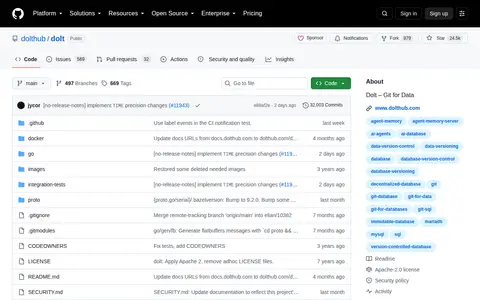
SQL database that you can fork, clone, branch, merge, push and pull just like a git repository.
Tools for exploratory data analysis in Python.
DuckDB is an analytical in-process SQL database management system. It is a high-performance analytical database system designed to be fast, reliable, portable and easy to use, with a rich SQL dialect supporting nested correlated subqueries, window functions, collations and complex types. It is available as a standalone CLI application with clients for Python, R, Java and Wasm.
Data Version Control - Git for Data & Models - ML Experiments Management.
Framework to create ChatGPT like bots over your dataset.
Functions and data dependencies for loading various word embeddings.